On June 10, 2026, Visa gave ChatGPT a payment network. Nobody gave it a reason to say no.
At the Visa Payments Forum in San Francisco, Visa announced it was wiring its network directly into ChatGPT: link a card once, and an OpenAI agent can complete real purchases across more than 175 million merchants without a human clicking "buy." Source: Digital Commerce 360, "Visa, OpenAI work together to support agent-led payments," June 2026 That single announcement is the fourth payment rail shipped for autonomous agents in nine months, and every one of the four ships the same safety mechanism: a spending limit. A per-transaction cap. A merchant whitelist. A session budget that expires. What none of them ship is a way to tell whether the purchase the agent is about to make, comfortably inside that limit, is actually a good idea.
This blog has made that exact argument about token spend before: a $500 million Anthropic bill in one month and the industry's reflex response of caps and dashboards fixes volume, not unit economics, and attackers and well-meaning employees produce the identical invoice because nothing watching the traffic counts in dollars. Now the same architecture is shipping for real money leaving real bank accounts, and it is worth being precise about what changed, what didn't, and what a spending limit actually buys you.
Four rails, nine months, one shared design.
Line the launches up and the pattern is obvious in retrospect.
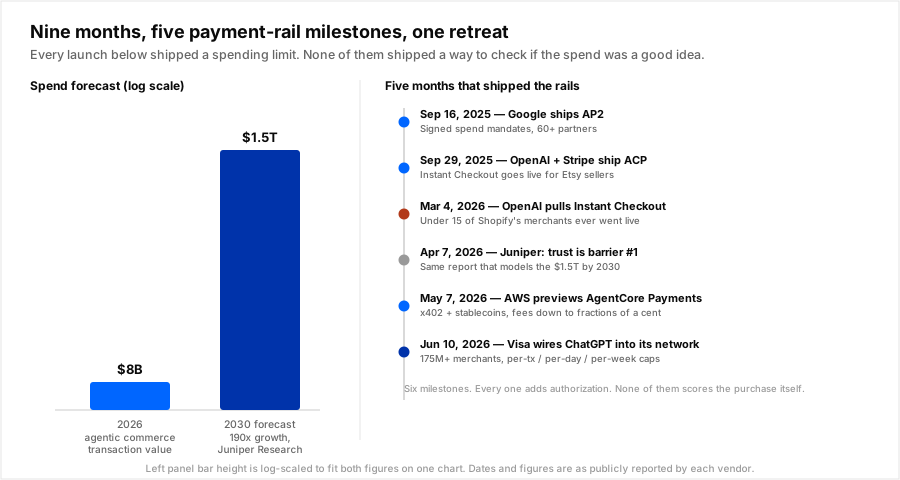
- September 16, 2025 — Google ships AP2 (Agent Payments Protocol). An open, vendor-neutral standard with more than 60 launch partners including Mastercard, PayPal, American Express, Coinbase, and Etsy. Its core primitive is a Mandate: a cryptographically signed statement from a human defining exactly what an agent may spend, on what, and for how long, that travels with the transaction so a merchant or network can verify real authorization happened. Source: Google Cloud Blog, "Announcing Agent Payments Protocol (AP2)," September 2026
- September 29, 2025 — OpenAI and Stripe ship ACP (Agentic Commerce Protocol) and Instant Checkout. A standardized checkout flow between an AI agent and a merchant, live at launch for US ChatGPT users buying from Etsy sellers, with more than a million Shopify merchants slated to follow. Source: Stripe Newsroom, "Stripe powers Instant Checkout in ChatGPT," September 2025
- May 7, 2026 — AWS previews Bedrock AgentCore Payments. Built on x402, an open, HTTP-native protocol from Coinbase that returns a 402 Payment Required status and settles in stablecoins, making fractional-cent transactions viable where a credit card rail can't operate. Developers set a time-bound, session-level budget, AWS's own example is "$1.00, expires in 5 minutes", enforced deterministically at the infrastructure layer rather than trusted to the agent's own restraint. Source: AWS, "Agents that transact: Amazon Bedrock AgentCore now includes Payments," May 2026
- June 10, 2026 — Visa wires its network into ChatGPT. Tokenized card credentials, real-time fraud monitoring, and per-transaction, per-day, and per-week spending caps plus merchant whitelists, all authorized in advance by the user, ChatGPT, and Visa together. Source: Digital Commerce 360, June 2026
Four different companies, four different technical approaches, cryptographic mandates, stablecoin micropayments, card-network tokenization, and every single one converged on the same control surface: cap the ceiling, whitelist the surface area, expire the session. That convergence is not a coincidence. It's the load-bearing lesson from a decade of API rate limiting, applied to a new kind of caller. It is also, on its own, an incomplete lesson.
The market thinks this is real. It also just watched the first version of it fail.
Juniper Research's April 2026 study forecasts agentic commerce transaction value growing from $8 billion in 2026 to $1.5 trillion by 2030, a roughly 190x increase, with Mastercard, Visa, and Stripe leading its infrastructure-provider leaderboard. The same report names trust as the number one barrier to adoption, ahead of technical readiness. Source: Juniper Research, "Agentic Commerce Set to Generate $1.5 Trillion Globally by 2030," April 2026
That trust gap is not theoretical. It already sank the first production deployment. OpenAI pulled Instant Checkout on March 4, 2026, five months after launch, after fewer than 15 of Shopify's millions of merchants ever went live on it, and replaced in-chat purchasing with a discovery-first model that routes the user back to the merchant's own app to actually pay. Source: CNBC, "OpenAI revamps shopping experience in ChatGPT after struggling with Instant Checkout offering," March 2026 The postmortem consensus wasn't that the spending limits failed. It's that the gap between "the agent can show you a product" and "the agent can correctly and safely close a sale", inventory sync, multi-item carts, returns, customer service, was operational, and no cap on transaction size touches any of it. Source: Forrester, "What It Means That The Leader In 'Agentic Commerce' Just Pulled Back," March 2026
That's the pattern worth sitting with: the industry shipped authorization infrastructure quickly and well. It has not yet shipped judgment infrastructure at all, and the one team that got furthest fastest hit that gap first.
What a spending limit actually verifies, and what it doesn't.
Every rail above answers one question: was this agent allowed to spend this much, here, right now? None of them answer a different, harder question: was spending it a good idea?
| Protocol | Ships | Controls | Doesn't check |
|---|---|---|---|
| AP2 (Google) | Signed spend mandates | What, where, how much, until when | Whether the specific purchase matches user intent |
| ACP (OpenAI + Stripe) | Standardized checkout handshake | Which merchants, which SKUs | Whether the checkout should have happened |
| x402 (Coinbase, via AWS AgentCore) | Per-call stablecoin micropayments | Session budget, expiry | Whether the paid call was worth the fee |
| Visa network | Card tokenization, fraud monitoring | Per-tx / per-day / per-week caps, merchant whitelist | Whether each transaction inside the cap made sense |
A cap set at $50 per transaction and $500 per day doesn't distinguish an agent that buys the right $40 item once from an agent that buys the wrong $40 item ten times before anyone notices the pattern, because both stay under every limit on the sheet the whole time. This is precisely the failure mode this blog has already documented for token spend: a cap prevents catastrophic blowouts and does nothing about the much larger, quieter bill run up entirely inside it. A rate limiter counts requests. A spend cap counts dollars. Neither one scores a decision.
The x402 detail that matters more than it looks like it does.
Of the four rails, x402 deserves a second look, because it isn't just a payment protocol for agents buying retail goods. It's a metering protocol for agents calling paid APIs, MCP servers, and paywalled data, priced down to fractions of a cent per call, settled per request instead of billed monthly. Source: Coinbase, "Introducing Amazon Bedrock AgentCore Payments, Powered by x402 and Coinbase"
That is functionally identical to the problem this blog spends most of its time on: an agent deciding, per step, whether a costly call is worth making. The Retry Tax, the Re-Review Tax, and the MCP tool-schema overhead already describe agents that call an expensive resource reflexively, inside whatever budget they've been handed, without a step that asks whether the call was warranted. x402 doesn't introduce a new failure mode. It puts a real-money price tag, settled instantly, on a decision agents were already making badly for free.
The fix already exists. It's a cascade, not a cap.
The cascade pattern this blog has documented for LLM cost, route cheap by default, escalate only when a verification step says the higher-cost path is actually warranted, generalizes directly to agent-initiated spend. The rails above enforce the ceiling. A verification gate in front of the spend decides whether this specific call, purchase, or API fee should happen at all before it ever reaches the payment rail:
def verified_spend(agent_action, mandate, verifier):
    """Runs before any payment call, not instead of the rail's own cap.
    mandate: the AP2/ACP/Visa-style authorization (amount, merchant, expiry).
    verifier: a cheap model or rule set scoring THIS specific decision."""

    if agent_action.amount > mandate.max_amount:
        return deny("outside mandate ceiling")  # the rail's job

    score = verifier.score(
        intent=agent_action.user_intent,
        proposed_action=agent_action,
        prior_actions=agent_action.session_history,
    )

    if score.confidence < CONFIDENCE_FLOOR:
        return escalate_to_human(agent_action)  # the judgment's job

    if score.is_duplicate_of_recent(agent_action.session_history):
        return deny("repeats a call already made this session")

    return execute(agent_action)
The verifier doesn't need to be another frontier-model call, that would just add a second cost decision on top of the first. A small classifier trained on confirmed-good versus reversed or disputed actions, the same shape of model this blog's cascade posts already route low-risk traffic through, is enough to catch the two failure modes a static cap structurally can't: repeated low-value calls that individually clear every threshold, and a single call that clears the mandate but doesn't match what the user actually asked for.
Nadir runs this exact pattern today for LLM API spend: a request hits a fast, cheap check before it's allowed to escalate to an expensive model, and the routing decision itself costs single-digit milliseconds. The mandates and caps that AP2, ACP, x402, and Visa ship are the correct place to enforce a ceiling. They were never going to be the place that catches a well-authorized, perfectly-in-budget decision that just wasn't a good one, because none of them were built to.
What to run this week.
- Read your own mandate scopes as if you were the agent, not the developer. If a per-transaction and per-day cap is the only thing standing between "authorized" and "trusted," you have authorization, not governance.
- Log every agent-initiated spend decision with the same discipline you log LLM calls. Amount, merchant or endpoint, and the intent it was supposedly satisfying, not just pass/fail against the cap.
- Add a cheap verification step in front of the payment call, not just around the budget. The same cascade math that works for model routing works for "should this specific purchase happen," at a fraction of the cost of blocking it after the fact.
- Watch for repetition, not just size. A duplicate $2 API call ten times in a session is invisible to a $500 daily cap and is exactly the pattern denial-of-wallet research has already shown attackers and misconfigured agents both produce.
- Don't treat x402 fees as a rounding error. A fractions-of-a-cent price per call sounds unimportant until an agent makes ten thousand of them in an afternoon loop with no verification step asking if call number 4,000 was necessary.
Conclusion.
Four different companies spent nine months building genuinely good infrastructure for a real problem: proving an agent had permission to spend money. None of them built the layer that decides whether the money should have been spent, because that was never the problem the rails were designed to solve. The one team that got furthest fastest found the gap first, and it wasn't a fraud problem or a cap that was set too high. It was the absence of anything that could look at one specific decision and say no. Token spend went through this exact cycle over the past year, caps first, judgment later, and the fix that stuck wasn't a lower ceiling. It was a cheap check run before the expensive call, every time. The agent has a wallet now. It still needs the same thing your API budget did.
Sources: [Digital Commerce 360, "Visa, OpenAI work together to support agent-led payments," June 2026](https://www.digitalcommerce360.com/2026/06/12/visa-openai-agent-led-payments/). [Google Cloud Blog, "Announcing Agent Payments Protocol (AP2)," September 2025](https://cloud.google.com/blog/products/ai-machine-learning/announcing-agents-to-payments-ap2-protocol). [Stripe Newsroom, "Stripe powers Instant Checkout in ChatGPT," September 2025](https://stripe.com/newsroom/news/stripe-openai-instant-checkout). [AWS, "Agents that transact: Amazon Bedrock AgentCore now includes Payments," May 2026](https://aws.amazon.com/about-aws/whats-new/2026/04/amazon-bedrock-agentcore-payments-preview/). [Juniper Research, "Agentic Commerce Set to Generate $1.5 Trillion Globally by 2030," April 2026](https://www.juniperresearch.com/press/agentic-commerce-set-to-generate-15-trillion-globally-by-2030-as-payments-infrastructure-leaders-revealed/). [CNBC, "OpenAI revamps shopping experience in ChatGPT after struggling with Instant Checkout offering," March 2026](https://www.cnbc.com/2026/03/24/openai-revamps-shopping-experience-in-chatgpt-after-instant-checkout.html). [Forrester, "What It Means That The Leader In 'Agentic Commerce' Just Pulled Back," March 2026](https://www.forrester.com/blogs/what-it-means-that-the-leader-in-agentic-commerce-just-pulled-back/). [A company burned $500M on Claude in 30 days. Spending caps are not the fix.](/blog/500m-claude-bill-spending-caps-wrong-fix). [Denial of Wallet Is the New DDoS](/blog/denial-of-wallet-llm-agent-security).