AT&T's daily token usage more than tripled. Its AI bill fell 90% anyway.
The instinct in most finance teams is to treat AI cost and AI usage as the same line moving together: more tokens, bigger bill. Deloitte's account of AT&T's rollout breaks that assumption in public. AT&T scaled generative AI across more than 100,000 employees and was processing roughly 8 billion tokens a day. After it restructured the work around multi-agent systems, that volume grew to 27 billion tokens a day, a 3.4x increase, while the company's AI cost fell by 90%. Source: Deloitte, "AI token economics for CFOs," 2026 Same company, more work getting done, a smaller bill. The lever wasn't spending less. It was changing what each token was spent on.
The figures in this post come from Deloitte's published account of AT&T's deployment and from OpenRouter's own funding announcement, not from Nadir's production data. Treat the specific multipliers as one documented case and one platform's self-reported growth curve, not universal constants every enterprise will replicate.
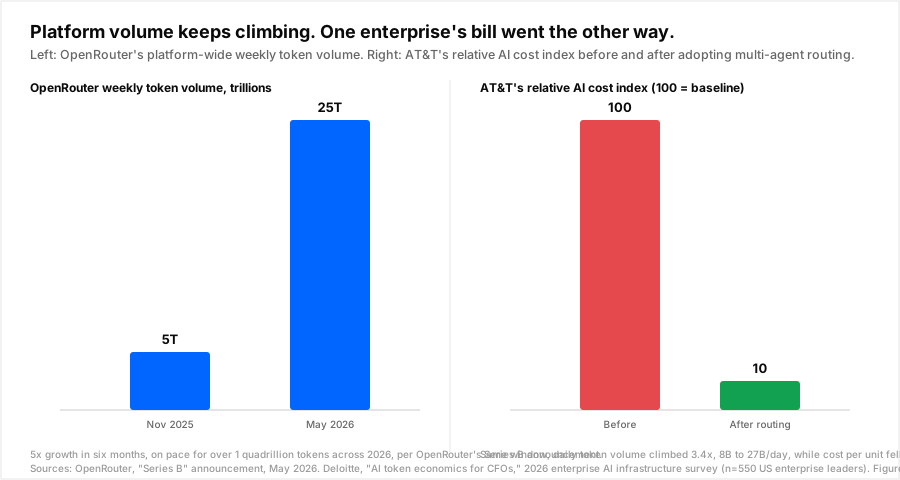
The volume wave is bigger than any one company
AT&T's growth curve isn't an outlier shape, it's the shape everywhere finance teams are looking right now. OpenRouter's own Series B announcement put its weekly platform-wide token volume at 5 trillion in November 2025 and 25 trillion by late May 2026, a 5x jump in six months, with the company on pace to process over a quadrillion tokens across all of 2026. Source: OpenRouter, "Series B" announcement, May 2026 Google separately reported processing 480 trillion tokens a month in 2025, a 50x year-over-year increase. Deloitte's own survey of 550 US enterprise AI leaders found 37% already consuming between 1 and 10 billion tokens a month, and another 30% above 10 billion. Source: Deloitte, "AI token economics for CFOs," 2026 None of this is a forecast anymore. It's the current run rate, measured across three independent sources that don't talk to each other.
Why usage keeps climbing even as the price per token falls
The obvious question is why volume is accelerating at all, given how far per-token prices have dropped over the same period. We've written about the price side of this separately: a blended average of $1.16 to $1.18 per million tokens in August 2026, down 43% in about ten weeks. Cheaper tokens should mean a flatter bill, not a steeper one. Two mechanisms explain the gap. First, reasoning and agentic workloads generate tokens a chatbot never did, thinking tokens before an answer, tool calls, multi-step trajectories, and Deloitte names this shift explicitly as a driver of the consumption curve. Second, this is the standard Jevons paradox pattern we've covered before: when the cost of doing a unit of work drops, teams don't hold spend flat and pocket the difference, they do more units of work. A cheaper token doesn't reduce the bill. It removes the reason not to run ten more agent loops than you would have last quarter.
The same growth curve, two different outcomes
Deloitte's report also carries the other half of the story: a healthcare enterprise whose token consumption grew 8% to 10% a month, compounding to roughly 1 trillion tokens over six months, and translating into more than $6 million in unplanned annualized cost. Same underlying force as AT&T, usage climbing on its own trajectory as adoption spreads through the organization. Different result, because nothing changed about how the work was architected. Every additional token flowed through the same undifferentiated path to the same model tier it always had.
| Healthcare enterprise | AT&T | |
|---|---|---|
| What grew | Token volume, 8-10%/month, ~1T tokens over 6 months | Token volume, 8B to 27B tokens/day |
| What changed architecturally | Nothing reported | Moved to multi-agent systems |
| Cost outcome | $6M+ unplanned annualized cost | Cost index fell ~90% |
| The difference | Growth absorbed at the existing per-token cost | Growth absorbed at a lower cost per unit of work |
Both are Deloitte-documented cases from the same 2026 survey. The variable that separated a $6 million surprise from a 90% reduction wasn't the growth rate. It was whether anything sat between the request and the most expensive model available to answer it.
What actually decouples the bill from the volume
AT&T's own account credits multi-agent orchestration, not usage restraint, and the mechanism generalizes past their specific stack:
- Route by what the request needs, not by default. A flat policy that sends every request to the same frontier model prices the easiest and hardest requests identically. Most of that traffic doesn't need the expensive model to begin with.
- Treat spend caps as a backstop, not a strategy. A hard ceiling on spend stops the bleeding after the fact; it doesn't change what each request costs before it's sent.
- Instrument cost per outcome, not cost per token. A token count with no attached task, model, or result tells finance a volume trend and nothing about whether that volume is buying anything. This is the same visibility gap FinOps-for-AI programs exist to close.
- Re-check the routing policy on a real cadence. The price floor moved 43% in ten weeks this year alone. A routing decision calibrated in Q1 is running on stale prices by Q3.
- Expect the growth to keep coming, and build for it now. Every source cited in this post, OpenRouter's, Google's, Deloitte's, points the same direction: more tokens, not fewer, arriving faster than the price per token is falling.
Where this fits next to routing
This is the same argument we made about Gartner's 90%-cheaper-inference forecast: a falling unit price doesn't lower a bill that's growing on volume, only a falling cost per unit of work does, and those are two different numbers. Nadir exists to be the layer AT&T's account describes in the abstract, deciding per request which model tier a given task actually needs, verifying the cheap answer before accepting it, and surfacing cost per request in the dashboard so growth in usage stops being indistinguishable from growth in spend. The token wave documented here isn't going to reverse. Whether it shows up on the invoice as AT&T's outcome or the healthcare enterprise's is an architecture decision, not a forecasting problem.
Conclusion.
Three independent sources agree the token volume flowing through AI systems is climbing fast, and none of them expect it to slow down. What separates a company that absorbs that growth from one that gets a surprise invoice isn't how much AI usage grows. It's whether every one of those tokens still routes to the same model tier it did a year ago, or whether something in the path is deciding, request by request, what that token actually needs to cost.
Sources: [Deloitte, "AI token economics for CFOs," 2026](https://www.deloitte.com/us/en/services/consulting/articles/cfo-guide-ai-token-economics.html); [OpenRouter, "Series B" announcement, May 2026](https://openrouter.ai/blog/announcements/series-b/).