A discount with an expiration date, attached to a change that doesn't expire
Claude Sonnet 5 went live on June 30, 2026, priced at $2 per million input tokens and $10 per million output. Source: Anthropic, "Claude Sonnet 5" That's a third off the $3 input / $15 output rate that has priced every Sonnet release since Sonnet 4. It's introductory. Anthropic's own pricing page states the discount runs "through August 31, 2026," after which "the standard pricing of $3/$15 per million input/output tokens will take effect." Source: Anthropic, Claude Platform Docs, Pricing Thirty-seven days from today.
The same page carries a second note, easy to skim past because it isn't attached to a dollar figure: Sonnet 5 uses the tokenizer that first shipped with Claude 4.7, and "this tokenizer produces approximately 30% more tokens for the same text" than the tokenizer Sonnet 4.6 and earlier models use. Sonnet 4.6 keeps the old tokenizer. Sonnet 5 doesn't. The discount is temporary. The extra tokens are not.
Same rate card, different tokenizer
Line up the two Sonnet 5 rows against Sonnet 4.6 and the shape gets obvious fast.
| Model | Input | 5m cache write | 1h cache write | Cache hit | Output |
|---|---|---|---|---|---|
| Claude Sonnet 4.6 | $3.00 | $3.75 | $6.00 | $0.30 | $15.00 |
| Claude Sonnet 5, through Aug 31, 2026 | $2.00 | $2.50 | $4.00 | $0.20 | $10.00 |
| Claude Sonnet 5, from Sept 1, 2026 | $3.00 | $3.75 | $6.00 | $0.30 | $15.00 |
Source: Anthropic, Claude Platform Docs, Pricing
Every column in the September row matches Sonnet 4.6 exactly. Anthropic isn't raising Sonnet's price on September 1. It's letting a temporary discount lapse back to the number Sonnet has held since Sonnet 4. What doesn't show up in this table is a tokenizer column, because there isn't one to show. Claude Opus 4.7 shipped this same tokenizer in May with no compensating discount at all, so the underlying pattern isn't new. What's new is that Anthropic priced Sonnet 5's transition to land close to cost neutral today, which means the token-count increase is currently hidden inside a price cut instead of sitting on an invoice where it's easy to spot.
The concrete number
Take a task that used 10,000 input tokens and 2,000 output tokens on Sonnet 4.6's tokenizer, costing $0.060. Feed the identical prompt and get an equivalent completion out of Sonnet 5, and Anthropic's own docs say to expect roughly 30% more tokens on both sides, around 13,000 input and 2,600 output, with the actual range running 1.0x to 1.35x depending on content type, code and non-English text trending toward the high end. Source: Anthropic, Claude Sonnet 5 announcement
Run that token count through today's intro price and the total comes to $0.052, about 13% below the Sonnet 4.6 baseline. Run the identical token count through the September 1 price and the total is $0.078, 30% above baseline. Nothing else about the request changed between those two numbers. Only the calendar did.
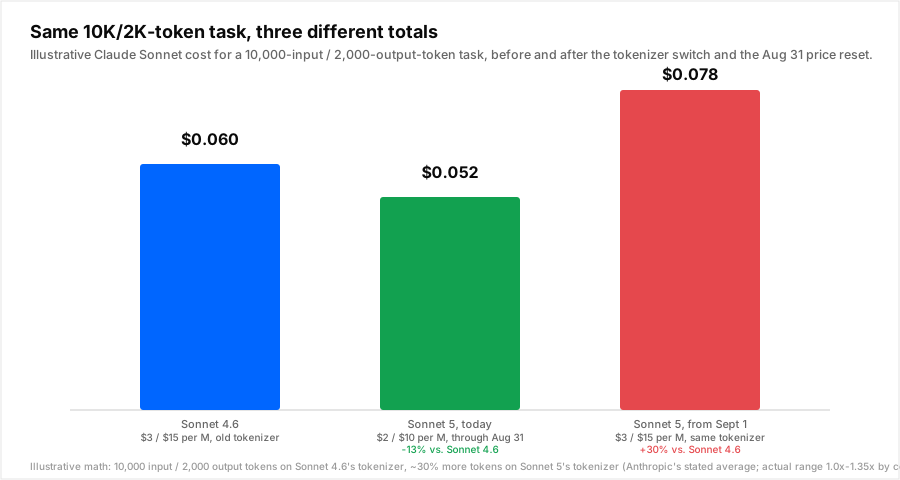
That's a 50% swing in total cost for the exact same task between what a team pays today and what the same code pays on September 1, driven entirely by which side of the price table the request lands on. Nobody has to change a model string, a prompt, or a line of infrastructure for that swing to hit. The rate card does it on a fixed date Anthropic already published.
This already happened once, and Opus didn't get a discount
Opus 4.7 shipped the same class of tokenizer change in May 2026, at an unchanged $5/$25 rate card and no introductory discount to offset it. Teams that assumed "same price, same model family" carried a silent 25 to 35% token increase into every Opus 4.7 call from day one, no countdown, no note in a pricing table framing it as temporary. Sonnet 5 is a gentler version of the same rollout: Anthropic built in six weeks of runway and named the tokenizer change directly in its pricing docs instead of leaving teams to notice it in a monthly total. That's a real difference, and it's also the reason this is easy to miss twice. A team that read the Opus post, checked its Opus spend, and moved on has no obvious trigger to go check Sonnet, because on the surface nothing looks wrong yet. It won't, until September 1.
The same blind spot that breaks a hardcoded model name on a deprecation notice breaks a hardcoded price assumption on a tokenizer swap: a routing layer that checks a live model string against a deprecation calendar is solving the same category of problem as one that checks live cost per request against a rate card that's still sitting inside its introductory window.
What to actually do this week
- Measure your own inflation factor, not Anthropic's 30% average. Run a representative sample of your actual prompts through Sonnet 4.6's and Sonnet 5's tokenizers and compare counts directly. Code-heavy or non-English workloads can land closer to the 35% ceiling Anthropic states, not the 30% midpoint.
- Put September 1 on a dashboard, not a memory. A cost jump that's fully explained by a published rate card change still reads as a mystery spike to whoever reviews the bill without that context in front of them.
- Don't treat "stay on Sonnet 4.6" as a free fix. It avoids the tokenizer question today, and it's the same static bet that broke teams who hardcoded a model name straight into a deprecation notice. Sonnet 4.6 isn't marked deprecated in Anthropic's pricing table yet, but nothing in that table promises it stays priced or available forever.
- Route the easy half of the workload off Sonnet entirely. A meaningful share of what teams send to Sonnet doesn't need Sonnet's reasoning depth. Haiku 4.5 at $1/$5 input/output sidesteps this specific tokenizer question because it's a different comparison, not a Sonnet-vs-Sonnet one.
- Watch cost per request, not cost per model name. The verifier-gated cascade Nadir runs on RouterBench reprices every request against whichever tier can currently handle it, so a rate card change like this one becomes a routing input the day it takes effect, not a retroactive line item three weeks later.
import openai

client = openai.OpenAI(
    base_url="https://api.getnadir.com/v1",
    api_key="YOUR_NADIR_KEY",
)

response = client.chat.completions.create(
    model="auto",  # Nadir prices each request against live provider rate
                    # cards, so the Sept 1 Sonnet 5 change lands the same
                    # day the invoice would, not a quarter later
    messages=[{"role": "user", "content": task_prompt}],
)

print(response.model)
print(response.model_extra["nadir_metadata"]["cost"]["total_cost_usd"])
Conclusion
August 31 isn't a surprise. Anthropic put the date and both rate cards in the same table on day one. What's easy to miss is that the thing the discount is offsetting, the extra tokens the same text now produces, already happened on June 30 and doesn't carry an expiration date of its own. A team that measures its own inflation factor this month knows exactly what September 1 costs before it arrives. A team that waits finds out on the first invoice that lands after the countdown runs out.
Sources: [Anthropic, "Claude Sonnet 5"](https://www.anthropic.com/news/claude-sonnet-5). [Anthropic, Claude Platform Docs, Pricing](https://platform.claude.com/docs/en/about-claude/pricing).