A router that escalates at "70% confidence" has no idea what 70% means until someone checks.
Route Bench, RouteLLM, FrugalGPT-style cascades, most confidence-gated routers share one design assumption nobody tests: that the number the model or the classifier hands back at inference time, 0.7, 0.85, 0.93, behaves like a probability of being correct. It's usually treated as one. A threshold gets set at 0.7 because that "feels" like a reasonable bar, traffic gets escalated above it, and the team moves on. This blog's own sweep of a confidence-gated cascade modeled that threshold across its full range and found a knee, a peak, and a frontier that bends backward past 0.73, all without ever asking whether the 0.73 on the x-axis corresponded to 73% actual correctness. That's not an oversight specific to one post. It's the default assumption almost every routing system ships with, and a May 2026 paper on cascade routing measured just how wrong that assumption can be: an Expected Calibration Error of 0.12 on the uncalibrated confidence signal, cut to 0.03 after a one-line fix. Source: "UCCI: Calibrated Uncertainty for Cost-Optimal LLM Cascade Routing," arXiv:2605.18796, May 2026
This post is the fix. What calibration actually measures, why a router's raw confidence score is probably lying to you by a wide margin, and the code to check your own.
What "calibrated" actually means.
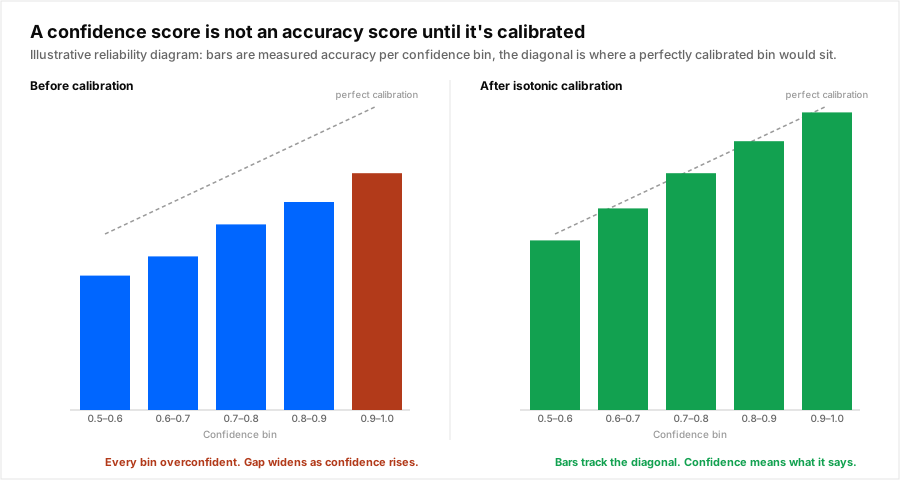
A confidence score is calibrated when, across every request where the model reports 0.7, roughly 70% of those requests are actually correct. Not 70% on average across the whole traffic mix. Specifically among the 0.7 bucket. That's the entire definition, and it's stricter than it sounds: a model can be highly accurate overall and still be badly calibrated, because calibration is about whether the number matches the bucket, not whether the model is good.
The standard way to measure the gap is Expected Calibration Error (ECE). Bucket every (confidence, correct-or-not) pair from your logs into bins, say ten bins from 0.0 to 1.0, then for each bin compare the average confidence the model reported against the actual fraction that was correct, weight by how many requests landed in that bin, and sum the absolute differences:
import numpy as np

def expected_calibration_error(confidences, correct, n_bins=10):
    """confidences: array of reported confidence scores, 0-1.
    correct: array of 0/1, whether that request's answer was right."""
    bins = np.linspace(0, 1, n_bins + 1)
    n = len(confidences)
    ece = 0.0
    for lo, hi in zip(bins[:-1], bins[1:]):
        mask = (confidences > lo) & (confidences <= hi)
        if mask.sum() == 0:
            continue
        bin_confidence = confidences[mask].mean()
        bin_accuracy = correct[mask].mean()
        ece += (mask.sum() / n) * abs(bin_accuracy - bin_confidence)
    return ece
A perfectly calibrated router scores 0.0. In practice, ECE in the 0.10-0.15 range on raw model confidence is common, and that's exactly the 0.12 the UCCI paper measured before calibration on its production task. Source: arXiv:2605.18796 It doesn't take an exotic model to get there. It's the default behavior of an uncalibrated score.
Why this isn't a fringe failure mode.
Overconfidence in learned models is not new and not specific to LLMs. The 2017 paper that made ECE and reliability diagrams standard tooling, "On Calibration of Modern Neural Networks," found that deeper and wider networks got more accurate and less calibrated at the same time, and that a single-parameter fix, temperature scaling, recovered most of the gap on the models they tested. Source: Guo et al., "On Calibration of Modern Neural Networks," ICML 2017, arXiv:1706.04599 Nine years and several model generations later, the same shape of problem shows up in LLM-based cascades: the signal that decides whether to escalate, a self-reported confidence, a verifier score, a margin between the top two token probabilities, is a useful ranking signal and an unreliable probability at the same time. It tells you which requests are relatively riskier than others. It does not, by default, tell you what fraction of requests at a given score will actually be wrong.
That distinction is exactly what a routing threshold needs and doesn't get for free.
What an uncalibrated threshold actually costs you.
Set an escalation threshold at 0.7 expecting it to mean "escalate anything likely to be wrong more than 30% of the time," and an uncalibrated router with 0.12 ECE can hand you a bucket where the true error rate is anywhere from roughly 18% to 42% instead, depending on the direction and size of the miscalibration in that region of the score range. The threshold sweep this blog ran earlier modeled a knee at 0.53 and a peak in task success at 0.73, both measured against the model's own reported score, not against ground truth per bin. If that score is overconfident the way the UCCI paper's uncalibrated baseline was, the true knee sits somewhere else on the same chart, and nobody notices until enough wrong answers accumulate to force a re-tune. A cascade with no verification at all at least fails obviously. A cascade with a miscalibrated verification step fails quietly, in the specific bin where you least expect it, because the number on the dashboard says "70% confident" and the actual rate is something else entirely.
The fix, and what it actually bought in production.
UCCI's approach is not exotic. It maps a token-level uncertainty signal to a per-query error probability using isotonic regression, a monotonic, non-parametric fit that only assumes higher raw uncertainty corresponds to higher true error rate, without assuming a specific curve shape the way temperature scaling's single parameter does. On a production named-entity-recognition workload processing 75,000 queries with 4B and 12B instruction-tuned models measured on H100s, calibration cut ECE from 0.12 to 0.03 and the resulting cost-aware threshold selection delivered a 31% inference cost reduction (95% CI: 27%-35%) at a held operating point of micro-F1 0.91, beating entropy thresholding, split-conformal routing, and FrugalGPT-style learned thresholds run at matched performance levels. Source: arXiv:2605.18796 The numbers are specific to that workload and that model pair, not a universal constant, but the mechanism generalizes: a calibrated confidence signal lets a cost-minimizing threshold search trust the number it's optimizing against, which an uncalibrated one can't.
The recalibration step itself is a few lines once you have logged (confidence, correct) pairs from live traffic:
from sklearn.isotonic import IsotonicRegression

# train_confidence, train_correct: from a held-out slice of logged traffic
calibrator = IsotonicRegression(out_of_bounds="clip")
calibrator.fit(train_confidence, train_correct)

# apply to new requests before comparing against the escalation threshold
calibrated_score = calibrator.predict(raw_confidence)
if calibrated_score < ESCALATION_THRESHOLD:
    response = call_model(FRONTIER_MODEL, query)
Isotonic regression needs a reasonable number of labeled (confidence, correct) pairs to fit a stable curve, not thousands per bin, and it needs periodic refitting: the same way a threshold needs re-tuning as workload mix and model pricing shift, a calibration curve drifts as the underlying model updates or the query distribution changes. Refit on a rolling window, not once at launch.
Where this sits next to routing, not instead of it.
Calibration doesn't replace a cascade's escalation logic or a verifier that checks the actual answer. It's the step that makes the number those systems threshold against mean what it claims to mean. A cascade with a well-calibrated confidence signal and a bad threshold is still miscosted. A cascade with a badly calibrated signal and a perfectly chosen threshold is optimizing against the wrong curve. Both matter, and most teams only ever tune the second one because it's the one with a single slider in the config file.
Nadir's own verifier is measured the same way. A reference-assisted RouterBench research experiment, where the verifier was given the expensive reference answer that the deployed reference-free path does not have, measured AUROC 0.961 and ECE 0.016 on 11,420 held-out triples at tau 0.8. Source: RouterBench cascade benchmark Those are research figures from that specific experiment, not deployed accuracy, a customer forecast, or a billing baseline; verification in production is optional for complete non-streaming responses, streaming bypasses it, and verifier errors fail open rather than blocking a response. The point of measuring ECE at all, on our own numbers or anyone else's, is the same point this post is making: a confidence score is a claim, and a claim gets checked, not assumed.
What to run this week.
- Pull (confidence, correct) pairs from your router's own logs. You need a ground-truth correctness label, from a held-out eval set, human review, or a downstream signal like a retry or edit, not just the score the router already emitted.
- Compute ECE with the ten-line function above before touching anything else. If it's above roughly 0.05, your threshold is being tuned against a number that doesn't mean what you think it means.
- Fit isotonic regression on a held-out slice, then re-run your threshold sweep against the calibrated score, not the raw one. The knee moves. Where it moves to is workload-specific; whether it moves is not in question.
- Refit on a schedule, not once. Model updates and traffic-mix drift both shift the calibration curve independently of anything you changed in your routing config.
- Don't conflate a ranking signal with a probability until you've checked. A score that correctly orders "riskier than" is not automatically a score that means "wrong X% of the time." Only the second one is safe to threshold against a cost target.
Conclusion.
The math behind an escalation threshold is simple once the input to it is trustworthy: pick the cutoff where the cost of over-escalating equals the cost of under-escalating, and route accordingly. Almost every cascade in production skips the step that makes that input trustworthy in the first place. Nine years after the field learned that modern models are overconfident by default, and one paper this year showing a 0.12-to-0.03 ECE swing translating directly into a 31% cost reduction at held quality, the fix is a bucket-and-compare function and, in most cases, an off-the-shelf isotonic fit. The number on your dashboard that says "70% confident" either means that or it doesn't. Check it before you build a threshold on top of it.
Sources: ["UCCI: Calibrated Uncertainty for Cost-Optimal LLM Cascade Routing," arXiv:2605.18796, May 2026](https://arxiv.org/abs/2605.18796). [Guo et al., "On Calibration of Modern Neural Networks," ICML 2017, arXiv:1706.04599](https://arxiv.org/abs/1706.04599). [The Threshold Nobody Tunes: Sweeping a Model Router's Confidence Cutoff](/blog/router-confidence-threshold-sweep-cost-quality-pareto). [RouterBench cascade benchmark](/blog/routerbench-cascade-benchmark).