Abstract.
Every LLM context window is managed the same way, regardless of framework, agent harness, or provider: as one flat buffer. The system prompt, every tool schema, every tool result, every message the user or the agent has ever sent in the session, all of it sits in the same tier for the entire lifetime of that session, because there is nowhere else for it to go. A March 2026 systems paper names that gap directly: a context window is L1 cache, small, fast, and expensive, and the field has been building on top of it as if it were the whole memory system. There is no L2. There is no virtual memory. There is no paging. The paper measured what that costs: across 857 production sessions and 4.45 million effective input tokens, 21.8% was structural waste, content sitting in context doing nothing for the current turn. It then built Pichay, a transparent proxy that evicts stale content, detects a page fault when the model re-requests something that was evicted, and pins whatever fault history says is actually part of the working set. In live production deployment over 681 turns, one session's context dropped from 5,038 KB to 339 KB, a 93% reduction, and an offline replay across 1.4 million simulated evictions held a 0.0254% fault rate. This post lays the classical memory hierarchy next to what most agent harnesses actually do today, and what changes about your bill when you add the layer that's currently missing.
Research question.
If a context window has no eviction policy, no fault detection, and no distinction between the working set and everything a session has ever produced, is that a prompting problem or a systems problem, and does treating it as the latter, borrowing working-set theory and demand paging wholesale from operating systems, actually hold up once it's carrying real production traffic instead of a benchmark replay?
The field skipped a layer.
Every fix this blog has covered for context bloat, chronological pruning, tool-output masking, a final self-summary, or measuring where accuracy degrades before the context limit does, is a fix applied inside L1. None of them ask the more basic question: why is there only one tier at all? A conventional computer never keeps every byte a program has ever touched resident in L1 cache. It evicts what isn't being used, keeps a fault-driven record of what actually gets re-requested, and pages the rest out to somewhere slower and cheaper. LLM context management, as shipped in nearly every agent framework in production today, skipped that layer entirely and went straight from "L1 only" to "let the model's own summarization ability paper over it," which is a different thing from a memory hierarchy and behaves differently under load.
| Layer | Classical OS analog | What most agent harnesses do today | Pichay |
|---|---|---|---|
| L1 | CPU cache | The entire context window. Everything lives here for the whole session. | Active working set only. |
| L2 | Paged-out RAM | Doesn't exist. Content either stays resident or a human or a summarizer deletes it for good. | Evicted content, recoverable the moment the model page-faults on it. |
| L3 | Disk / swap | A final self-summary, if the harness happens to write one before hitting the limit. | Model-initiated conversation compaction: a durable, queryable record. |
| Cross-session | Persistent storage | Nothing carries over between sessions. | Identified as the remaining frontier, not yet shipped. |
The reframing matters because the problems this blog keeps measuring, cost scaling with every token carried forward, attention degrading well before the advertised limit, state getting lost across sessions, are not three separate problems with three separate fixes. The paper's claim is that they're the same problem wearing different clothes: a memory hierarchy problem, and the tools to solve it, working set theory (Denning, 1968), demand paging, fault-driven replacement policies, already exist and are decades old.
Eviction, fault, pin: how Pichay actually works.
Pichay is implemented as a transparent proxy sitting between the client and the inference API, not a change to the model or a new prompting pattern. It interposes on the message stream itself.
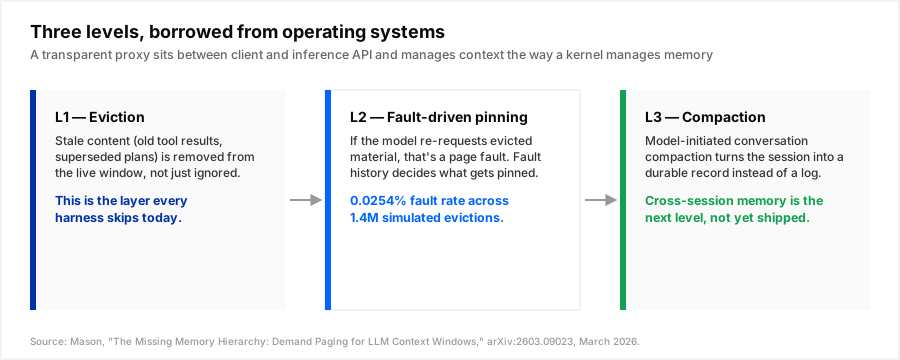
L1, eviction. Stale content, superseded plans, tool results nothing downstream still depends on, gets removed from the live window instead of just aging in place. This is the layer every default harness skips: without it, "context management" means "wait for the limit and truncate," which is a symptom response, not a policy.
L2, fault-driven pinning. If the model asks for something that was evicted, that's a page fault, the same signal a real memory system uses to know its eviction guess was wrong. Pichay doesn't try to predict relevance up front; it watches which evicted pages actually get re-requested and pins those, the same working-set logic Denning described for programs accessing memory, applied to a model accessing its own history.
L3, compaction. Rather than a human-authored summary bolted on at the end, compaction here is model-initiated: the conversation gets turned into a durable, queryable record instead of a flat log that only ever grows. It's the paper's version of paging out to disk, slower to reconstruct from, but not gone.
The design detail worth keeping: none of these three levels require the model to behave any differently. The proxy does the accounting. That's also why it's a proxy and not a framework change, the same architectural choice this blog has flagged before as the difference between a fix that ships this quarter and one that requires every downstream team to rewrite their agent loop.
The numbers.
| Measurement | Result |
|---|---|
| Structural waste, baseline | 21.8% of 4.45M tokens across 857 production sessions |
| Fault rate, offline replay | 0.0254% across 1.4 million simulated evictions |
| Context reduction, live deployment | Up to 93% (5,038 KB to 339 KB) over 681 production turns |
| Behavior under extreme sustained pressure | Remains operational; exhibits the expected thrashing pathology, repeated fault-in of evicted content |
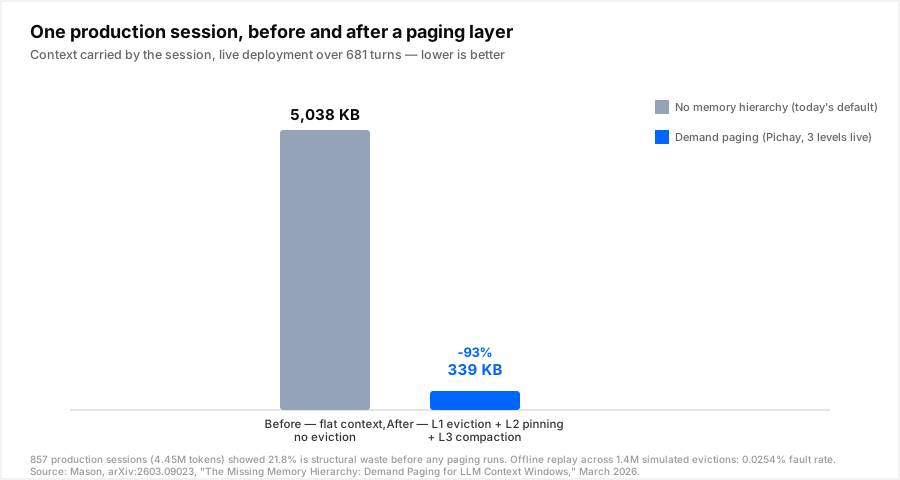
The honest line in that table is the last row. The paper doesn't stop at the win, it reports what happens when a session pushes past what any eviction policy can reasonably hold: thrashing, the same pathology a real virtual memory system exhibits when the working set exceeds available memory and the system spends its time paging content in and out instead of making progress. That's the mark of a systems paper rather than a demo, a caching layer that only reports its best case isn't describing a memory hierarchy, it's describing a cherry-picked benchmark.
What a minimal version of this looks like.
The full Pichay design has three levels and a fault-tracking mechanism behind them. The part worth prototyping first is the smallest one: evict, and track whether eviction was wrong.
from dataclasses import dataclass, field
import time

@dataclass
class Page:
    id: str
    content: str
    last_used_turn: int
    fault_count: int = 0
    pinned: bool = False

class ContextPager:
    """L1 eviction + L2 fault-driven pinning, as a proxy step
    between the client message and the inference call."""

    def __init__(self, working_set_size: int):
        self.pages: dict[str, Page] = {}
        self.working_set_size = working_set_size
        self.turn = 0

    def touch(self, page_id: str, content: str):
        self.turn += 1
        page = self.pages.get(page_id) or Page(page_id, content, self.turn)
        page.content, page.last_used_turn = content, self.turn
        self.pages[page_id] = page

    def request(self, page_id: str) -> str | None:
        """The model re-requesting something evicted is a page fault:
        the eviction guess was wrong, and fault history should say so."""
        page = self.pages.get(page_id)
        if page is None:
            return None  # truly gone, not just evicted
        if not page.resident:
            page.fault_count += 1
            if page.fault_count >= 2:
                page.pinned = True  # working set, by observed behavior, not a guess
        page.last_used_turn = self.turn
        return page.content

    def evict_stale(self):
        """Keep the working_set_size most recently used, unpinned pages
        resident; the rest move to L2, recoverable on the next fault."""
        live = [p for p in self.pages.values() if p.pinned]
        candidates = sorted(
            (p for p in self.pages.values() if not p.pinned),
            key=lambda p: p.last_used_turn,
            reverse=True,
        )
        for page in candidates[: self.working_set_size - len(live)]:
            page.resident = True
        for page in candidates[self.working_set_size - len(live):]:
            page.resident = False  # evicted, not deleted
The detail that makes this a paging system rather than a truncation heuristic: eviction never deletes page.content. It only flips resident, and fault_count is the signal that decides what graduates to pinned. That's the whole mechanism, applied at whatever granularity a harness can address, tool results, file reads, prior plan steps, rather than a fixed window of the N most recent messages.
What this doesn't solve.
This is a single-author systems paper describing one deployed proxy, not a benchmark run across every agent framework, and the 93% figure is one production session, not a guaranteed rate. Thrashing under sustained pressure is a real, reported failure mode, not a hypothetical, a session whose genuine working set exceeds what any policy keeps resident will still degrade, the same way a real OS thrashes when a process's working set outgrows physical RAM. And cross-session memory, carrying a working set forward once a session ends, is explicitly named as the frontier the paper doesn't yet ship, so anything claiming a full four-level hierarchy today is ahead of what's been deployed and measured.
What to check before you build one.
- Instrument fault rate before you trust an eviction policy. A policy that never gets challenged by a re-request looks perfect and might just be evicting into a part of the conversation nothing ever revisits; a policy with a high fault rate is actively lying to you about what the working set is.
- Never delete on eviction, only mark non-resident. The entire value of a demand-paging approach over a truncation heuristic is that a wrong eviction guess is recoverable instead of a permanent, silent loss the next turn has no way to detect.
- Watch for thrashing as its own alert, not just as slow requests. Repeated fault-in of the same evicted content on the same session is the signal something's working set genuinely doesn't fit, and the fix there is scoping the task down, not tuning the eviction policy harder.
- Treat L3 compaction as a durable record, not a one-shot summary. A summary written once near the context limit is a snapshot; a queryable, model-initiated compaction is closer to what actually survives being paged back in later.
- **Nadir's Context Optimize already strips redundant tool schemas and repeated boilerplate before a request goes out**, which is the L1 half of this picture on a single call. Pairing that with routing, so the model choice and the context shape get optimized together instead of independently, is the same instinct this paper applies across an entire session's memory hierarchy instead of one request.
Conclusion.
The paper's real argument isn't the 93% number, it's the reframe underneath it: context limits, attention degradation, cost scaling, and state lost between sessions have been treated as four separate problems with four separate fixes, when they're one problem, the field never built past L1. Working set theory and demand paging aren't new ideas that need inventing, they're fifty-year-old ideas that never got applied to this substrate until now. A proxy that evicts, tracks faults, and pins by observed behavior instead of a guess cut one production session's context by 93% and held a fault rate under three-hundredths of a percent across 1.4 million simulated evictions, and it did that without changing a single line of the model or the prompt. The next context-cost fix worth checking isn't a better summarizer. It's whether there's a memory hierarchy underneath your agent at all.
Sources: [Mason, "The Missing Memory Hierarchy: Demand Paging for LLM Context Windows," arXiv:2603.09023, submitted March 9, 2026](https://arxiv.org/abs/2603.09023). Denning, "The Working Set Model for Program Behavior," Communications of the ACM, 1968. [The Context Garbage Collector](/blog/self-gc-context-garbage-collection-agents). [The RULER Gap](/blog/ruler-gap-context-window-advertised-effective). [Context Engineering Is Not Prompt Engineering](/blog/context-engineering-not-prompt-engineering). [Compression saves you once. Routing plus compression saves you twice.](/blog/compression-plus-routing-save-twice)