A fourth lab just cut the frontier price by 75%
On July 9, 2026, Meta opened its first paid model API to developers in public preview: Muse Spark 1.1, priced at $1.25 per million input tokens and $4.25 per million output tokens. Source: Meta AI, "Introducing Muse Spark 1.1". Against the two models most teams route their frontier traffic to today, Claude Opus 4.8 at $5/$25 and GPT-5.5 at roughly $5/$30, that is a quarter of the output price and a fifth of the input price. Source: Tech Times, "Meta's Muse Spark 1.1 Opens Paid API at One-Quarter of Anthropic, OpenAI Rates". It even undercuts DeepSeek V4 on input, $1.25 against $1.74, though DeepSeek stays cheaper on output.
Muse Spark 1.1 is not a toy model shipped to make a pricing headline. It is a multimodal reasoning model built specifically for agentic work, tool use, computer use, and coding, with a 1-million-token context window, and it is Meta Superintelligence Labs' second release in this line after the original Muse Spark debuted in April. Source: DataCamp, "Muse Spark 1.1: Meta's Agentic Model and API". Every developer account that opened this week, with $20 in free credits attached, can start routing production coding-agent traffic to it today.
The obvious move is to point your router's cheap tier at it this afternoon. That is also the move that has already burned the last team who tried it with a different quarter-price model.
The table before the excitement
| Model | Input ($/M) | Output ($/M) | Released | Track record |
|---|---|---|---|---|
| Muse Spark 1.1 | $1.25 | $4.25 | Jul 9, 2026 | Days |
| DeepSeek V4 | $1.74 | $3.48 | May 2026 | Months |
| Claude Opus 4.8 | $5.00 | $25.00 | Frontier | Established |
| GPT-5.5 | $5.00 | $30.00 | Frontier | Established |
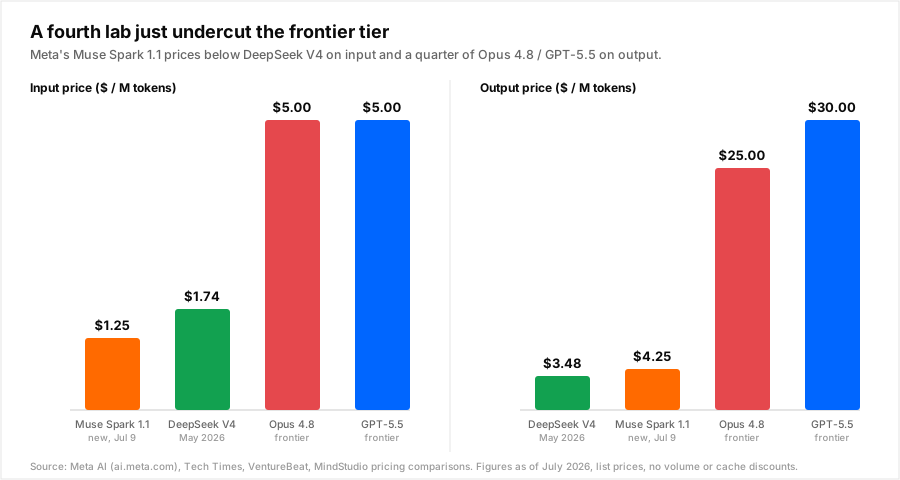
The price columns are the easy part to compare. The column that actually decides whether Muse Spark 1.1 belongs in your routing pool, track record, is nearly empty. It launched days before this post. Nobody outside Meta's own benchmarks has run it against a large, messy, real production prompt set yet.
The last team that skipped that column
This blog covered exactly that experiment when MiniMax M3 shipped at roughly a tenth of Opus 4.8's price. On 198 real prompts, MiniMax matched Opus within one point on 70% of them and cost 8x less. On the surface, an obvious swap.
The number that mattered was the one the aggregate hid: 27% of answers came back clearly worse, a severe two-point-or-more quality drop, and that rate more than tripled on complex prompts, up to 58%. Even on simple prompts, the severe-drop rate was 18%, roughly one answer in six, and it was not predictable in advance from prompt length or topic.
A quarter-price model that fails one production request in six is not a savings story. It is a support-ticket generator with a discount attached. The fix was never "don't use the cheap model." It was "route it only the traffic it has actually proven it can handle."
What has to be true before a new model earns traffic
- Replay real prompts, not vendor benchmarks. Meta's own numbers for Muse Spark 1.1 are measured on Meta's own benchmark suite. Your production traffic, your tool schemas, your prompt lengths, your edge cases, is a different distribution. Vendor benchmarks tell you a model is worth testing, not that it is ready to serve.
- Score blind, against your current tier, not a leaderboard. Run the candidate and your incumbent model on the same prompt set and score both without knowing which answer came from which model. This is itself an LLM workload with its own bill, judge calls do not run for free, so budget for it rather than skipping it because you are trying to save money.
- Segment by difficulty before trusting the average. MiniMax M3's headline number, within one point 70% of the time, hid an accuracy split from 81% on medium prompts to 40% on complex ones. Any aggregate pass rate you compute for Muse Spark 1.1 needs the same breakdown, or you are making a routing decision on a number that only describes your easy traffic.
- Shadow the candidate before it serves anyone. Send it the same requests your production tier is already answering, in parallel, without showing the user its output. Nadir's outcome-conditioned routing runs this as a standing mechanism, cross-tier calibration probes, roughly 2% of traffic mirrored to a candidate tier, so a new model's real capacity estimate is built from live traffic before it is trusted with any of it.
- Promote gradually, with an automatic rollback trigger. Start the candidate at single-digit percentages of real traffic, watch the failure signal (empty, malformed, or clearly-worse responses) tighten or widen, and let the routing layer pull back automatically the moment the rate crosses a threshold, rather than waiting for someone to notice in a weekly report.
Where Muse Spark 1.1 actually stands today
Run it against that checklist and here is what is known and what is not, days in. Known: the price, $1.25/$4.25, and a 1M-token context window. Known: Meta says it delivers major gains in tool use, computer use, coding, and multimodal understanding, and this is Meta's first paid model API, so it is a serious commercial commitment, not a research demo. Source: DataCamp, "Muse Spark 1.1: Meta's Agentic Model and API".
Not yet known: how it performs on anyone's real agentic tool-calling traffic outside Meta's own demos, whether its computer-use claims hold on your actual UI surfaces, and whether it has the same complex-prompt cliff MiniMax M3 had. The public preview is US-only, which itself limits how much production volume can even flow through it yet to build a track record. None of that makes Muse Spark 1.1 a bad model. It makes it a model with close to zero production hours logged anywhere outside Menlo Park, which is precisely the profile that belongs behind a calibration probe, not in front of live traffic.
The pattern is bigger than one model
Muse Spark 1.1 is not a one-off. DeepSeek V4 did this in May, landing within 2 to 3 benchmark points of Opus 4.7 at roughly a sixth of the cost. Apple, Perplexity, and Google all shipped their own routing layers within weeks of each other. MiniMax M3 did it with a specific, measured failure mode attached. A new quarter-of-frontier-price entrant now shows up roughly every six to eight weeks, and the pattern is accelerating, not slowing down, as more labs open commercial APIs to fund their training runs.
The actual infrastructure question is not whether to switch to Muse Spark 1.1 today. It is whether your routing layer has a standing process that can absorb whichever model is cheapest this quarter without betting production quality on a five-day-old benchmark. A hardcoded model string in your application code cannot do that. A routing layer with calibration probes built in can add Muse Spark 1.1 as a shadow candidate today and let it earn its way into the cheap tier on your own traffic, at your own pace:
curl https://api.getnadir.com/v1/router/candidates \
  -H "X-API-Key: $NADIR_API_KEY" \
  -d '{
    "model": "meta-muse-spark-1.1",
    "tier": "cheap",
    "mode": "shadow",
    "probe_rate": 0.02
  }'
The candidate mirrors 2% of the cheap tier's real traffic, gets scored against the requests your current model already answered, and only shows up as a routing option once its capacity estimate clears the same bar the incumbent had to clear. No user ever sees an unqualified answer, and the savings, up to 75% on output tokens if Muse Spark 1.1 holds up, land the moment it actually qualifies rather than the moment it looked cheap in a pricing table.
Every price cut is real money left on the table if you never capture it, and a real quality risk if you capture it blind. Start free and let the router run this qualification on your own traffic, or read the complete guide to cutting LLM API costs for the rest of the playbook this fits into.