The paper that turned a cheap model into a cheat code
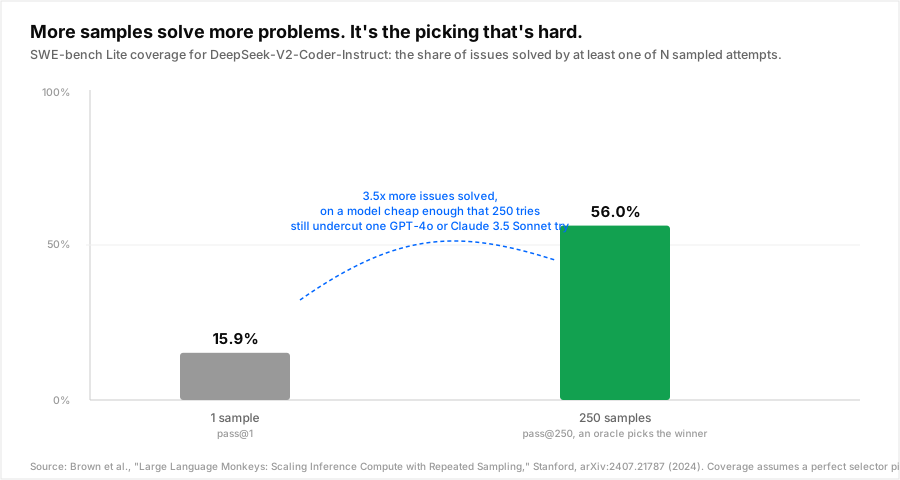
In July 2024, a Stanford team published a result that reads like a loophole: sample a model enough times, and a cheap one starts beating an expensive one, on both accuracy and price, at once. Source: Brown et al., "Large Language Monkeys: Scaling Inference Compute with Repeated Sampling," arXiv:2407.21787. On SWE-bench Lite, DeepSeek-V2-Coder-Instruct solved 15.9% of issues given one attempt. Given 250 attempts, it solved 56%, more issues than a single try from GPT-4o or Claude 3.5 Sonnet, and at lower total cost than either. The relationship wasn't a fluke of one model or one benchmark: coverage, the fraction of problems solved by at least one sample, scaled with sample count as a log-linear power law across every task and model family the paper tested.
That's the pitch every "test-time compute" headline since has repeated in some form: don't train a bigger model, just ask a smaller one more times. The paper's own title is a wink at why that pitch is incomplete. Give infinite monkeys infinite typewriters and one of them eventually types Hamlet. The number that made headlines, 56% coverage, assumes something the metaphor glosses over: somebody already knows which page is Shakespeare. Coverage is a pass@k number. It credits a set of N samples with a win the moment any one of them is correct, whether or not anything in your system could have identified which one. Production doesn't get to return a set. It has to return one answer. Picking that answer, cheaply and reliably, is the part the coverage curve never bills you for.
Two ways to pick, two very different bills
There are two standard ways to turn N generated samples into one returned answer, and they fail in opposite directions.
Self-consistency, the original 2022 technique, samples N full reasoning chains and takes a majority vote on the final answer. Source: Wang et al., "Self-Consistency Improves Chain of Thought Reasoning in Language Models," arXiv:2203.11171. No reward model, no extra scoring pass, just a vote. The catch is in how many votes a close call needs: recent sample-complexity analysis shows self-consistency requires Θ(1/Δ²) samples to reliably surface the correct answer, where Δ is the probability gap between the correct answer and the next most likely one. Source: "Sample Complexity and Representation Ability of Test-Time Scaling Paradigms," arXiv:2506.05295. Squared. The requests where the model is most genuinely torn between two plausible answers, exactly the ones a voting scheme exists to rescue, are the ones that need quadratically more samples before the vote can be trusted.
Best-of-N with a reward or verifier model scores every sample and returns the highest-scoring one. The same analysis found it needs only Θ(1/Δ) samples for the same reliability, quadratically fewer than plain voting. But every one of the N samples now has to be scored, by a separate model call, which is its own token bill stacked directly on top of the N generations it's judging. This blog has already measured how expensive that judge call gets on its own; running it N times per request multiplies a cost that was already easy to underestimate.
Either method is usually implemented with N fixed once, at integration time, as a flat constant: 5, 10, 20, 40 samples, applied to every request in the traffic mix regardless of whether that particular request needed one try or would have needed three hundred. That flat constant is the monkey tax: full generation cost, and often a full scoring pass, paid on requests a single sample would have nailed, while the rare request that actually needed the full budget is still capped at the same number as everything else.
What a year of test-time-scaling research actually fixed
The gap between "coverage exists" and "coverage is affordable" is where most of 2025 and 2026's test-time-compute research has been spent. None of it argues against sampling. All of it argues against spending the same fixed N on every request.
ST-BoN watches how consistent a sample's internal decoding state looks before it finishes generating, and truncates the ones that are already trailing instead of paying to complete them. No separate reward model required. Source: "Sampling-Efficient Test-Time Scaling: Self-Estimating the Best-of-N Sampling in Early Decoding," NeurIPS 2025, arXiv:2503.01422. Reported result: over 80% less GPU memory, 50% less latency, and either 70 to 80% lower cost at matched accuracy, or 3 to 4 points higher accuracy at matched cost, against a full Best-of-N baseline.
Slim-SC applies the same instinct to self-consistency specifically: it prunes reasoning chains that would cast a redundant vote, a sample that's substantively the same as one already drawn, so the ensemble reaches the same voting confidence on fewer complete generations. Source: "Slim-SC: Thought Pruning for Efficient Scaling with Self-Consistency," arXiv:2509.13990.
Uncertainty-Aware Budget Allocation moves the decision up one more level: instead of fixing N per method, it fixes a budget and spends it per query, based on measured uncertainty, drawing more samples for a request the model is genuinely unsure about and stopping at one or two for a request it already agrees with itself on. Source: "Uncertainty-Aware Budget Allocation for Adaptive Test-Time Reasoning," arXiv:2605.26849.
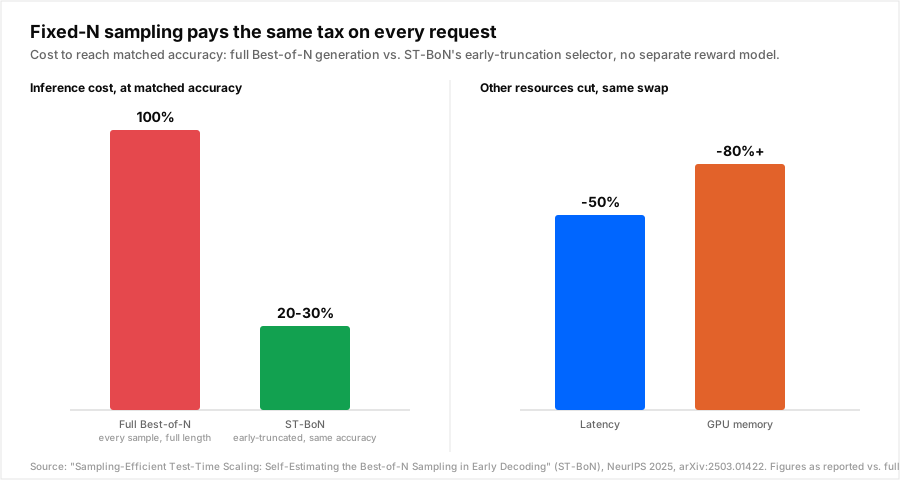
The common thread across all three is the same sentence repeated three ways: stop treating N as a number you set once. Each one turns "how many tries does this request need" into a live, per-request measurement instead of a constant copied into a config file during initial integration and never revisited.
The same decision, one level down from routing
That sentence should sound familiar. It's the same argument this blog makes about model choice: a router that sends every request to the same model regardless of difficulty pays a tax on the easy majority to cover the hard minority; a sampling scheme that draws the same N regardless of difficulty does exactly that, one layer further into the request. Both problems have the same shape, and both have the same fix: a calibrated signal that knows when the cheap path has already converged, and escalates, in tries or in model tier, only when it hasn't.
This blog has already covered what a verifier-gated cascade buys over blind escalation: the value isn't the ceiling case, it's removing the cost of continuing past the point where continuing stopped helping. The same verifier score that decides whether to escalate a request from a cheap model to an expensive one is the same kind of signal that decides whether a second sample is worth drawing at all. Treated as two separate engineering problems, they get solved twice, once per team, often with two different ad hoc thresholds nobody has measured against real traffic. Treated as one problem, calibrated confidence gating an escalation, in tier or in sample count, it's a single mechanism.
What to check this week
- Measure your actual agreement rate at your current fixed N. Pull the last 1,000 self-consistency or best-of-N calls and check how often the majority answer was already decided after 1 sample, after 2, after 3. Most production traffic converges far earlier than the configured N.
- Add an early stop. Stop drawing samples once k consecutive draws agree, or once a verifier score clears a calibrated threshold, instead of always running to the full N.
- Decouple the generator from the scorer. The model producing candidate samples doesn't need to be the same, or as expensive, as the one judging or voting on them; route each to the cheapest model that job tolerates.
- Track wasted samples as their own line item. Completions generated after the answer was already decided, multiplied by your per-token completion price, is the exact dollar size of your own monkey tax, and it's invisible in a bill that only shows total token spend.
A minimal version of the early-stop, routed so the generation step and the agreement check use whichever models are actually cheapest for each:
from collections import Counter
import openai

client = openai.OpenAI(
    base_url="https://api.getnadir.com/v1",
    api_key="ndr_...",
)

def adaptive_sample(prompt, max_samples=20, agreement_threshold=3):
    votes = Counter()
    for _ in range(max_samples):
        response = client.chat.completions.create(
            model="auto",
            messages=[{"role": "user", "content": prompt}],
        )
        answer = response.choices[0].message.content.strip()
        votes[answer] += 1

        top_answer, top_count = votes.most_common(1)[0]
        # Stop as soon as one answer has a clear, stable lead —
        # not when max_samples is reached.
        if top_count >= agreement_threshold and top_count > sum(votes.values()) - top_count:
            return top_answer, sum(votes.values())

    return votes.most_common(1)[0][0], sum(votes.values())
Same call shape as talking to any OpenAI-compatible endpoint. Nadir routes each of those calls to the cheapest model and provider that can handle it and reports the routing decision per request, so the sample count this loop settles on, not a hardcoded N, becomes the only variable left to tune.
Related reading
- A calibrated verifier is what makes escalation worth its cost, not just its ceiling.
- The LLM-judge call you added to check quality has its own token bill, and it compounds with everything downstream of it.
- Extended thinking tokens are billed like any other output token; more reasoning per sample is a cost lever with the same shape as more samples.
- Routing without a verifier is dead reckoning: confident, cheap, and wrong exactly when it matters.
- The elasticity of six different cost levers, measured independently against the same baseline.
Sources: [Brown et al., "Large Language Monkeys: Scaling Inference Compute with Repeated Sampling," arXiv:2407.21787](https://arxiv.org/abs/2407.21787). [Wang et al., "Self-Consistency Improves Chain of Thought Reasoning in Language Models," arXiv:2203.11171](https://arxiv.org/abs/2203.11171). ["Sample Complexity and Representation Ability of Test-Time Scaling Paradigms," arXiv:2506.05295](https://arxiv.org/abs/2506.05295). ["Sampling-Efficient Test-Time Scaling: Self-Estimating the Best-of-N Sampling in Early Decoding," NeurIPS 2025, arXiv:2503.01422](https://arxiv.org/abs/2503.01422). ["Slim-SC: Thought Pruning for Efficient Scaling with Self-Consistency," arXiv:2509.13990](https://arxiv.org/abs/2509.13990). ["Uncertainty-Aware Budget Allocation for Adaptive Test-Time Reasoning," arXiv:2605.26849](https://arxiv.org/abs/2605.26849).