A compression ratio of 0.3 cut input tokens by 70%. On one benchmark, it made the model write 56 times more output.
Prompt compression's pitch is simple: shrink the input, shrink the bill. A new benchmark study puts a number on when that pitch breaks. Across 5,400 API calls spanning three benchmarks and three models, an arXiv preprint found that truncating a prompt to 30% of its original length doesn't just risk a wrong answer, it can make the model write dramatically more of one. On DeepSeek-Chat, the same 0.3 compression ratio produced a 56.4x output-token expansion on MBPP and a 5.2x expansion on HumanEval, using an identical compression method against the same model. Source: Johnson, "Compression Method Matters: Benchmark-Dependent Output Dynamics in LLM Prompt Compression," arXiv:2603.23527, Mar 2026 The variable that moved wasn't the model. It was which task the prompt was for.
Figures in this post come from a single arXiv preprint, not from Nadir's own production traffic, and the paper has not (as of this writing) cleared peer review. The compression method it tests is deliberately naive, first-N-words truncation, not a semantic compressor like the LLMLingua family [we've covered separately](/blog/prompt-compression-llmlingua-input-token-reduction). Treat the exact multipliers as one controlled experiment's findings, not a universal constant.
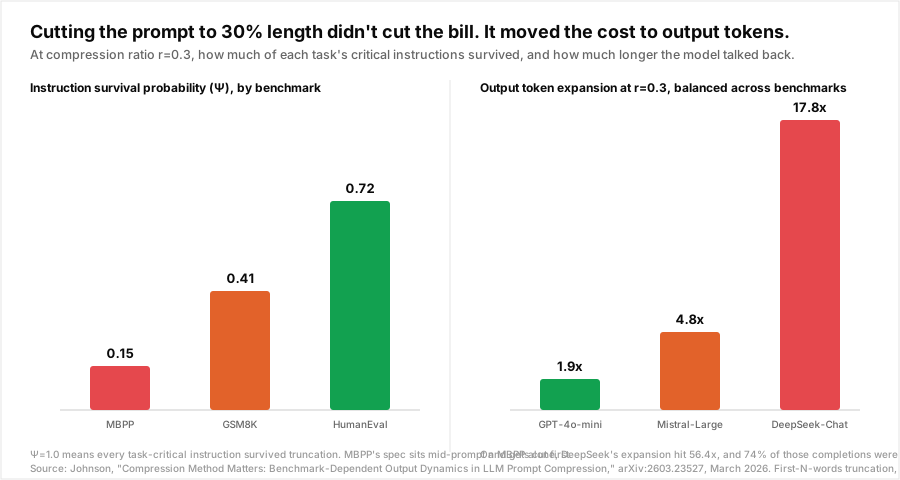
Two benchmarks, two different bills, from one compression method
The paper's core move is testing the same truncation method, the same ratios, and the same three models against three benchmarks with structurally different prompts: MBPP (500 Python problems, task spec placed mid-prompt), HumanEval (164 Python problems, function signature stated early), and GSM8K (100 grade-school math problems, instructions distributed across the prompt). To explain why identical compression produced wildly different outcomes, the authors define instruction survival probability, Ψ, a weighted measure of how much of a prompt's task-critical content is still present after truncation. At r=0.3, Ψ came out to 0.15 on MBPP, 0.41 on GSM8K, and 0.72 on HumanEval. First-N-words truncation kept HumanEval's early-stated function signature almost intact. It gutted MBPP's mid-prompt task spec.
The paper's headline claim follows from that gap: whether compression is safe is a property of where the critical instruction sits in the prompt, not a property of the model or the compression ratio alone. A ratio that's fine for one task shape can be destructive for another, using the exact same setup.
Why the model starts talking more when you take words away
The mechanism the paper proposes: models exhibit what it calls "verbose compensation" once instruction survival drops below a threshold, roughly Ψ ≈ 0.35 in their data. Below that line, a model that no longer has a clear signal for how much output the task calls for doesn't fail quietly, it starts producing more. On MBPP at r=0.3, DeepSeek-Chat's output expansion was severe enough that 74% of its completions hit the study's 1,024-token ceiling before finishing, meaning the reported 56.4x multiplier likely understates how far the model would have kept going uncapped.
That's the opposite of what a compression pass is supposed to buy you. The point of cutting input tokens is a smaller bill. A model that responds to a stripped prompt by writing paragraphs instead of the four-line function it was asked for moves the cost to the side of the ledger that was already priced against you: output tokens run 5 to 8 times the price of input tokens on every major provider's rate card.
Not every model reacts the same way, and the ranking isn't obvious
To make robustness comparable across benchmarks, the paper introduces a Compression Robustness Index (CRI) that combines how much task quality (pass@1) survives compression with how much output length grows, normalized against a token ceiling. At r=0.3:
| Model | CRI at r=0.3 | Reading |
|---|---|---|
| GPT-4o-mini | 0.848 | Highly robust to truncation |
| Mistral-Large | 0.424 | Moderately robust |
| DeepSeek-Chat | 0.090 | Compression-sensitive |
A smaller, cheaper model coming out roughly ten times more robust than a 671B-parameter MoE model on the same compression method isn't the ranking most teams would guess going in. The paper attributes the gap to differences in training and architecture rather than raw capability, and doesn't claim the ranking generalizes past these three models. The finding worth taking away isn't "GPT-4o-mini is compression-safe," it's that robustness to truncation doesn't track with model tier, so it has to be measured per model, not assumed.
The energy story undercuts itself the same way
The study also ran direct GPU power measurements (NVML, RTX 4090, TinyLlama-1.1B on vLLM) alongside its token-counting experiments, because a separate, common claim, that fewer tokens means proportionally less energy, turns out not to hold either. A 17.4% cut in total tokens produced only a 4.8% cut in joules, and energy-per-token actually rose 15.6%. The paper's own energy model prices output tokens at roughly 3x the joules of input tokens (0.45 mJ versus 0.15 mJ per token in their measurement), which is the same asymmetry that shows up in dollar pricing: shifting the token mix toward output, even while shrinking the total, can raise the real cost per request. "Token savings" and "cost savings," in either currency, are not the same measurement.
Do the dollar math before a compressor ships
Take a request that would normally run 1,000 input tokens and 200 output tokens against a typical $3 / $15 per-million-token rate card, a 5x output premium in line with the numbers above. Uncompressed, that's $0.003 input plus $0.003 output, $0.006 total. Compress the prompt to r=0.3 (300 input tokens) and apply this paper's balanced Mistral-Large multiplier, a 4.8x output expansion, and output climbs to roughly 960 tokens: $0.0009 input plus $0.0144 output, $0.0153 total. The prompt got 70% shorter. The request got 2.5x more expensive. This is an illustrative calculation built on the paper's reported multiplier and a representative rate card, not a measured production bill, but the arithmetic is exactly why "fewer input tokens" isn't a proxy for "lower cost" once output can move.
What actually ships this week
- Measure output-token delta before and after compression, per task type, not just once. A compressor validated on one benchmark shape (function-signature-first code, short chat turns) can fail silently on another (spec-in-the-middle tasks, long-form generation).
- Watch for hit-the-ceiling completions as a leading indicator. If a meaningful share of compressed requests are getting truncated by your own max-tokens setting, the model was trying to write more than you're seeing, and the real expansion is worse than what got billed.
- Don't assume a bigger or newer model is more compression-tolerant. This paper's data has the smaller model an order of magnitude more robust than the largest one tested. Test the model you're actually running, not a proxy for it.
- Price the output side, not just the input side, before adopting a compression ratio as policy. A ratio that helps on your rate card's input price can still lose money once it's multiplied against the output price it's structurally more expensive to shift toward.
Where this fits next to routing
This is the same failure shape that shows up whenever a cost lever gets applied as a blanket rule instead of checked per request: a policy that's correct on average and wrong on the specific case where it costs the most. We've made the same argument about routing to the cheapest model and about shipping an answer without a check. Compression is no different. Nadir treats context reduction the same way it treats model choice: something to test against the request that's actually running, with the resulting cost, input and output both, visible per request in the dashboard, rather than a ratio set once in a config file and left to compound against whichever task shape happens to hit it hardest.
Conclusion.
The instinct behind prompt compression is correct: most prompts carry tokens the model doesn't need. What this paper adds is that a savings estimate built only from the input side can be wrong in the specific direction that matters, the bill going up instead of down, and that it can happen with the same compression method, the same ratio, and the same model, just because the task shape changed. A 56x output expansion on one benchmark and a 1.7x expansion on another, from an identical setup, is a strong argument for validating compression per task before it ships, not a strong argument against compression itself.
Source: [Johnson, "Compression Method Matters: Benchmark-Dependent Output Dynamics in LLM Prompt Compression," arXiv:2603.23527, March 2026](https://arxiv.org/abs/2603.23527).