Three ways to run a model. Three completely different bills.
There are three ways to put an LLM behind your product, and teams keep comparing them like they're the same purchase with different price tags. They aren't. Self-hosting is buying fixed capacity. A managed API for an open-weight model is buying variable, pooled capacity at a thin margin. A frontier API is buying the model itself, priced at whatever the lab that trained it decides to charge. Each one carries a real monthly number, and the "free" one on that list is very often not the cheapest.
What each option is actually made of
| Self-host | Managed open-weight API | Frontier API | |
|---|---|---|---|
| What you're paying for | Rented or owned GPUs, 24/7 | Someone else's GPUs, pooled across customers | The model itself, plus the lab's own compute |
| Cost shape | Fixed: the bill is close to the same whether you send 1 token or 10 million | Variable: scales with tokens sent | Variable: scales with tokens sent |
| Who absorbs utilization risk | You. Idle GPU-hours are still billed hours | The provider, pooled across every customer on the platform | The lab, pooled across every customer on the platform |
| Engineering time | Real and recurring: patching, monitoring, scaling | Near zero | Near zero |
| Typical $/M tokens | $0.15-$0.80 depending on model size | Roughly $0.05-$0.90 depending on model and provider | $2-$15 depending on model and lab |
| Where it wins | High, steady volume against an expensive alternative | Low-to-mid volume, open-weight quality is enough | Any volume where the quality ceiling matters more than the per-token price |
The middle column is the one most "self-host vs API" comparisons skip entirely, which is a real gap, because a managed open-weight API gets you open-weight pricing without taking on any of the fixed cost or utilization risk in the left column.
The GPU math, priced honestly
Cloud H100 rental runs $1.49 to $6.98 an hour across more than a dozen providers, averaging around $3.20 to $3.39, with hyperscaler on-demand pricing running well above that: AWS around $6.88/hour, Azure around $12.29/hour, versus specialized GPU clouds in the $2-3/hour range. Source: IntuitionLabs, "H100 Rental Prices Compared," 2026; Source: Spheron, "GPU Cloud Pricing Comparison 2026," 2026. A single A100 80GB at roughly $2/hour runs about $1,440 a month rented around the clock; two of them run about $2,880. Source: DevTk.AI, "Self-Host LLM vs API: Real Cost Breakdown 2026".
That's before the fudge factor every honest TCO estimate adds. A common rule of thumb multiplies the raw GPU rental cost by 1.3x to 2x to reach a realistic total cost of ownership, once load balancing, monitoring, and redundancy are priced in, which puts a single well-run A100 deployment around $3,000 to $3,500 a month before it has served a single production token. Source: DevTk.AI, "Self-Host LLM vs API: Real Cost Breakdown 2026". Fixed monthly GPU spend for a Llama-3-class 8B model on an L40S lands around $900 to $1,500; a 70B model on A100s runs $1,500 to $2,500. Source: Tensoria, "Self-Host LLMs or Use the API? Real $/1M Token Numbers in 2026".
None of that includes the part almost every calculator leaves out.
The line item that gets skipped: your own time
A maintained self-hosted deployment needs 10 to 20 hours a month of a senior engineer's time for patching vLLM, watching dashboards, and chasing down the 2am page. At $75 to $150 an hour for a senior DevOps or ML engineer, that's $750 to $3,000 a month, recurring, whether or not the fleet is busy. Source: DevTk.AI, "Self-Host LLM vs API: Real Cost Breakdown 2026". On a single-GPU deployment, that labor line can be larger than the GPU rental itself. It's also the part of the bill nobody puts on a pricing page, which is exactly why it's the part that gets left out of the comparison.
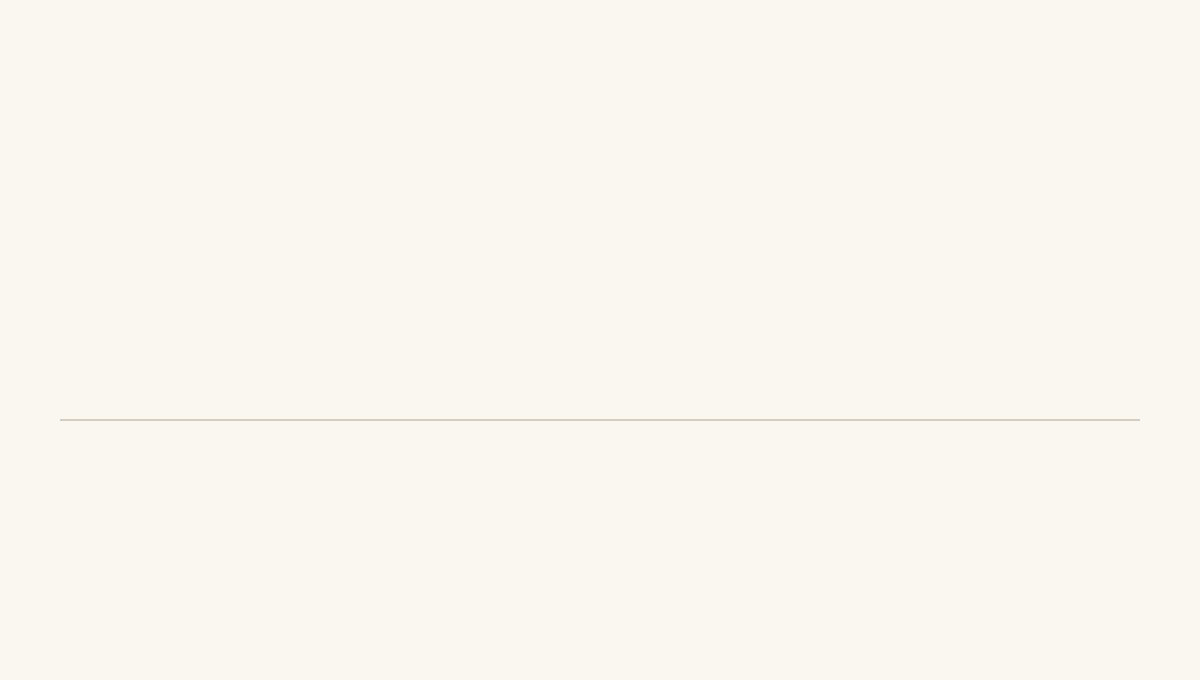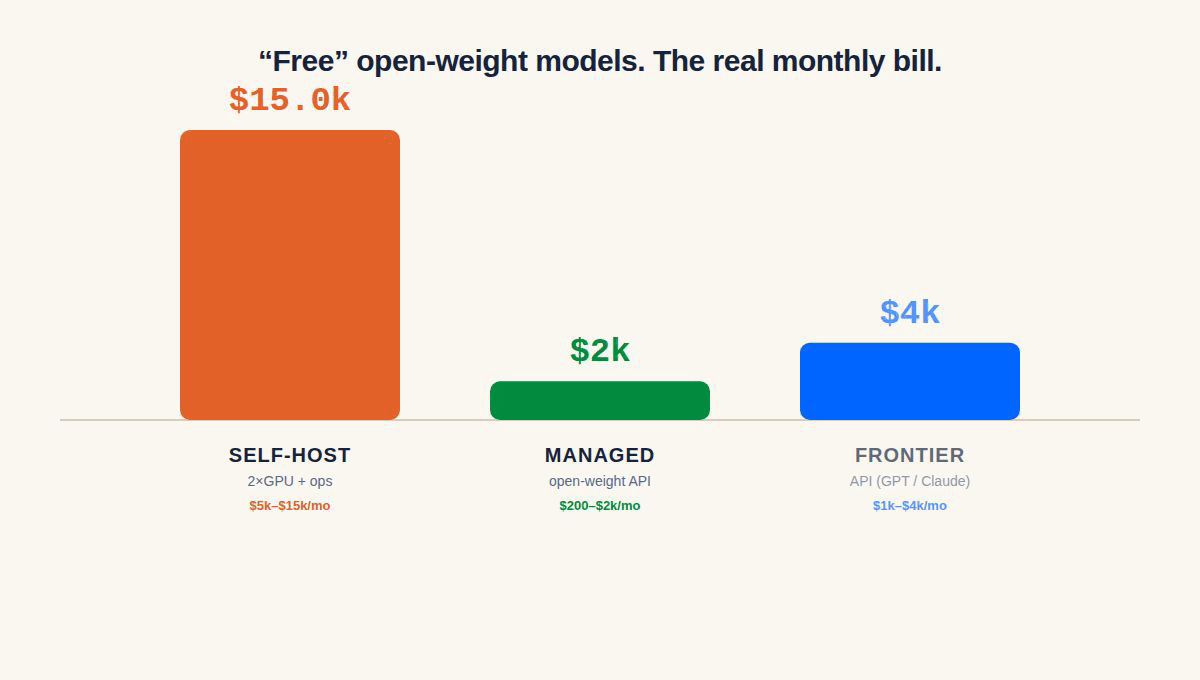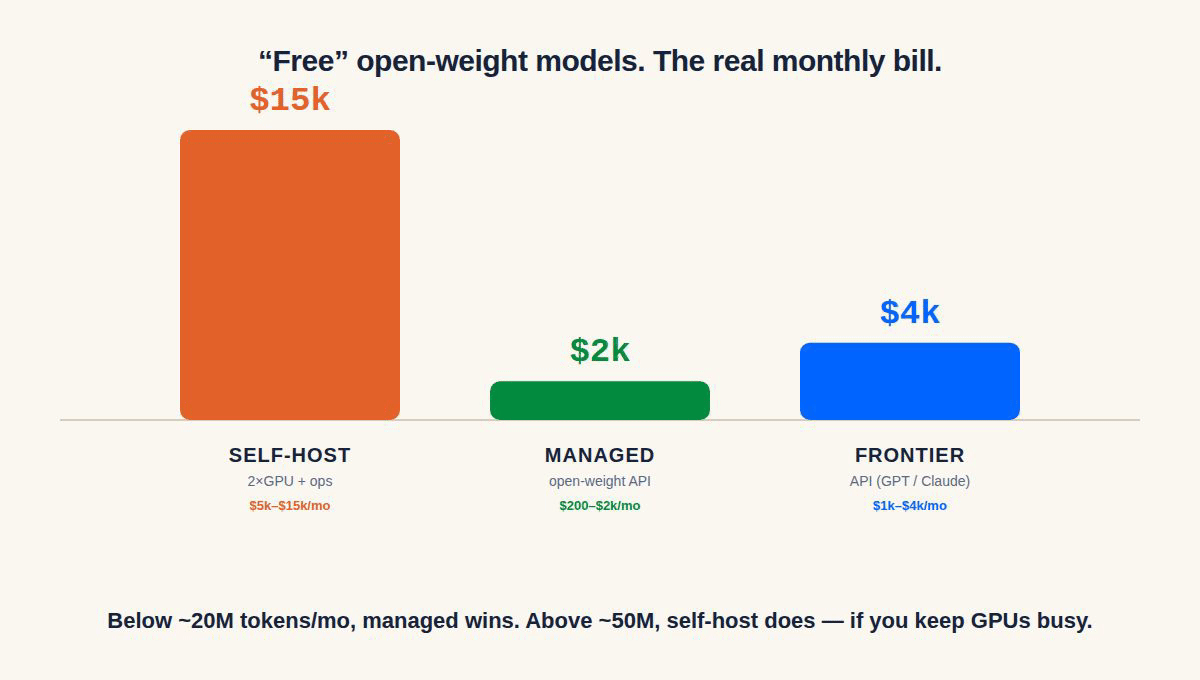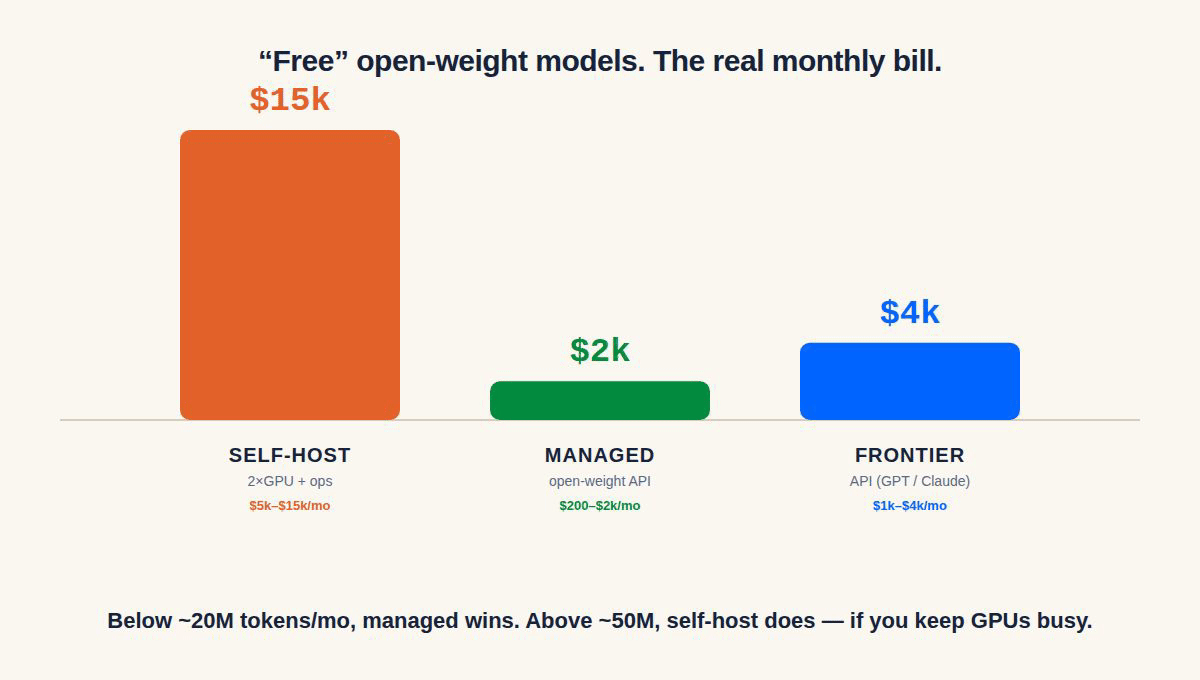
Add the GPU rental, the TCO multiplier, and the engineering time together and a small self-hosted deployment, the kind a mid-sized team would actually run, lands in the same $5,000 to $15,000-a-month range that shows up whenever anyone actually itemizes it rather than quoting the GPU-hour price alone.
The breakeven volume is not one number
Here's the finding that should change how this comparison gets made. Priced against different APIs, the volume where self-hosting starts to win moves by more than an order of magnitude:
- Against a flagship frontier model, self-hosting a comparable open-weight model breaks even around 256 million tokens a month, roughly 8.5 million tokens a day.
- Against DeepSeek V4 Flash, a fast, cheap model near the bottom of the market, the breakeven volume runs to roughly 6.86 billion tokens a month.
- Against Gemini 2.5 Flash-Lite, similarly cheap, breakeven runs to roughly 5.76 billion tokens a month.
Source: DevTk.AI, "Self-Host LLM vs API: Real Cost Breakdown 2026". A separate, more general estimate puts self-hosting an open-weight model at "economically rational" somewhere between 50 and 200 million tokens a month, which sits in between those two extremes because it assumes you're displacing a mid-priced API, not the cheapest one on the market and not the most expensive. Source: Tensoria, "Self-Host LLMs or Use the API? Real $/1M Token Numbers in 2026".
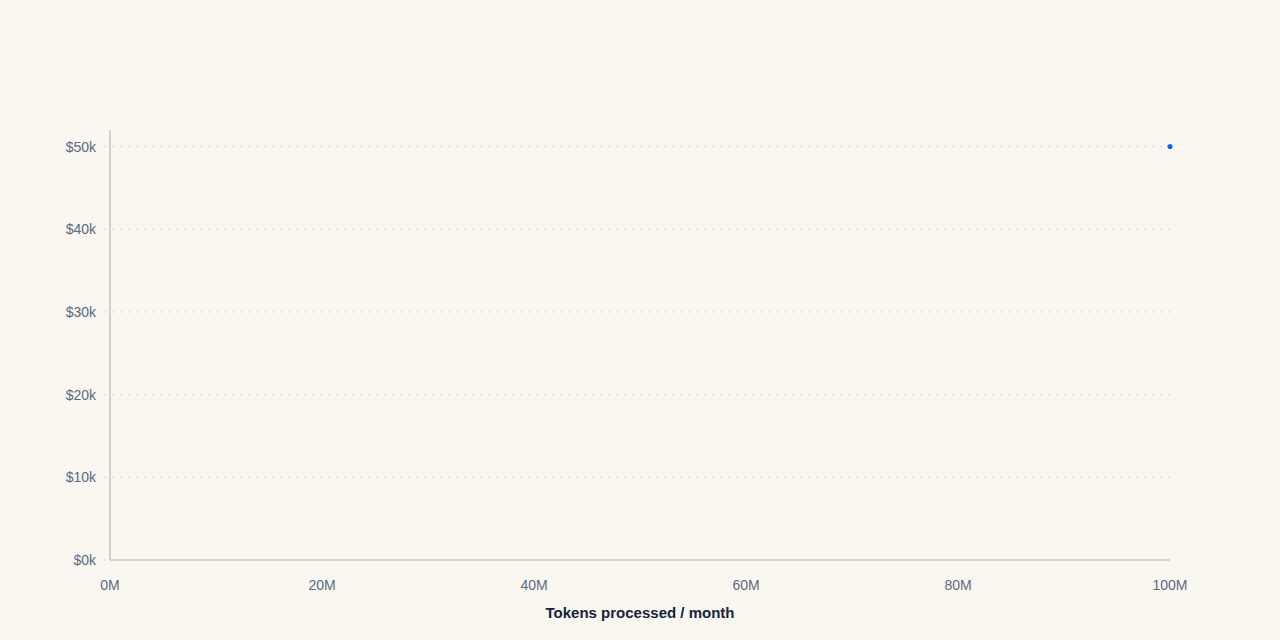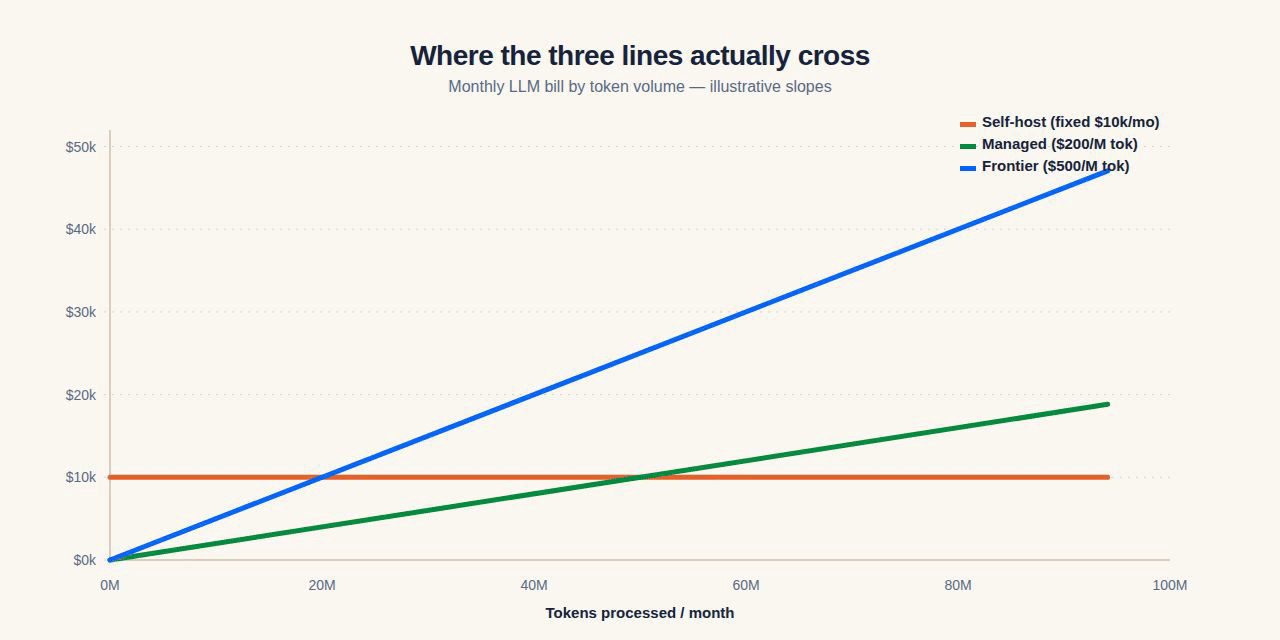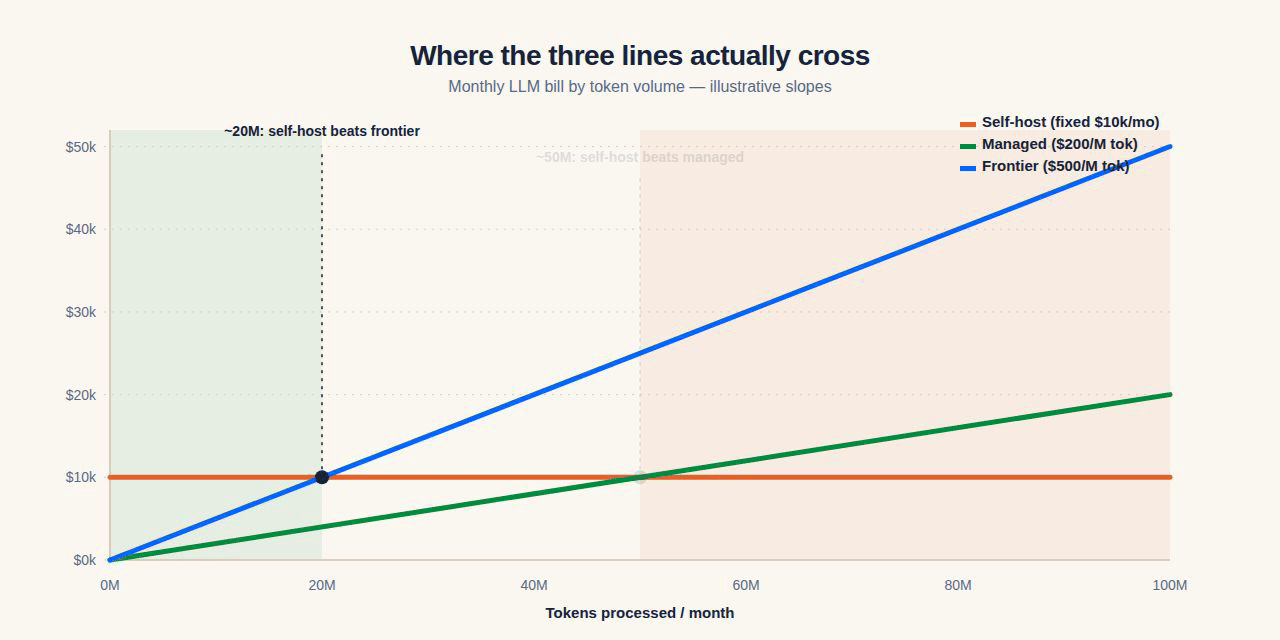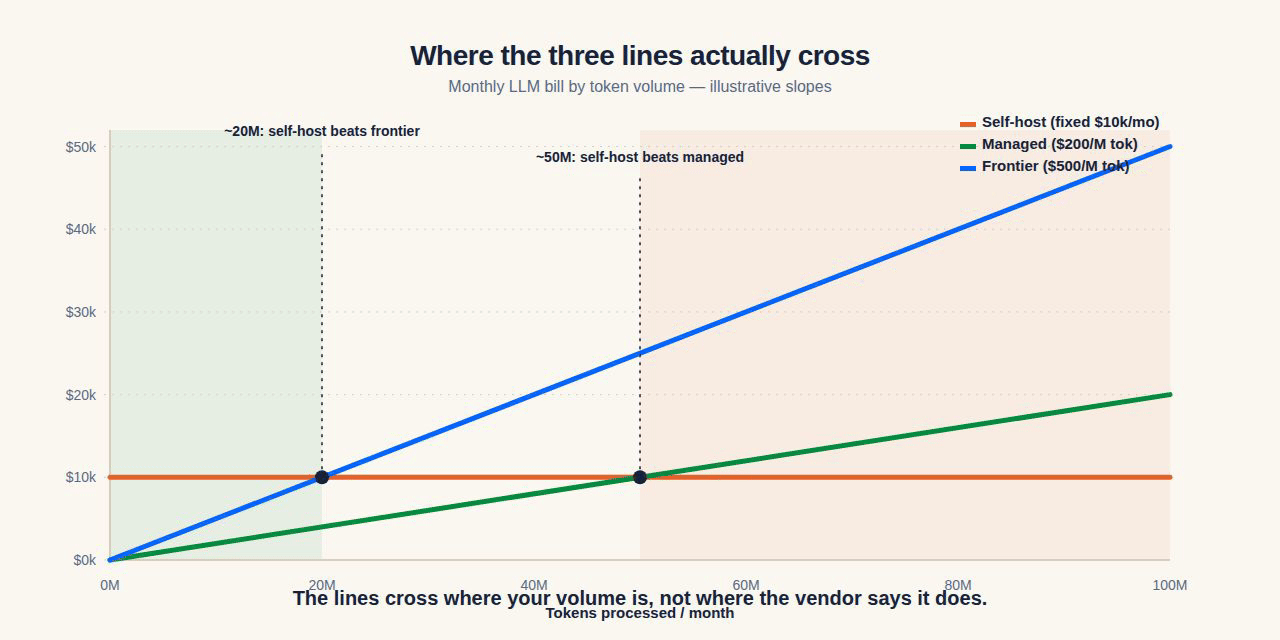
The mechanism is simple once you see it: breakeven volume is the fixed self-hosting cost divided by the per-token price gap. Compare against an expensive model and the gap is wide, so it takes fewer tokens to pay back the fixed cost. Compare against a model that's already cheap, and the gap nearly closes, so the fixed cost never gets paid back at any volume a normal product will reach. The self-host-versus-API decision was never really about self-hosting. It's a bet on how expensive the alternative stays.
And the fixed line only holds if you keep the GPUs busy
Every number above assumes the self-hosted fleet runs close to saturated. That assumption is doing a lot of work. A June 2026 paper found that identical H100 hardware costs anywhere from $0.21 to $15.25 per million output tokens purely as a function of GPU utilization, a 2.5 to 24x penalty at ordinary 1-10 requests-per-second business load and up to 36.3x near idle. A fleet sized for peak traffic runs underutilized most of every day it operates, which means the flat line in the chart above is really a floor, not a guarantee. Get the utilization wrong and the breakeven volume you calculated on paper is the volume you'd need at a fully saturated fleet, not the one you'll actually see.
A decision framework, not a rule of thumb
- Under roughly 20 to 50 million tokens a month: a managed API almost always wins once engineering time is counted, because there's no fixed cost to amortize and no utilization risk to carry.
- Well above that, against an expensive model: self-hosting can pay back its fixed cost quickly, sometimes within tens of millions of tokens a month, if the fleet stays busy.
- Against a cheap, already-efficient model: don't bother. The per-token gap is too thin to ever clear a GPU rental bill plus an engineer's time, and routing to that cheap model directly captures most of the same saving with none of the fixed cost.
- Managed open-weight APIs are the option most comparisons skip: they get you open-weight pricing and open-weight model choice without the fixed cost or the utilization bet, and they're very often the right first move before a self-hosting decision is even on the table.
- Data residency and compliance can override all of this. If classification or generation has to stay inside your network boundary, that's a real constraint self-hosting solves that no API pricing table changes.
Why this doesn't have to be a one-time bet
The uncomfortable part of the analysis above is that the right answer moves. DeepSeek V4 Flash and Gemini 2.5 Flash-Lite didn't exist at their current prices a year ago, and the next round of aggressive open-weight pricing will move the breakeven line again, probably in the same direction: further out of self-hosting's reach for anything but the highest, steadiest volumes. A team that built a GPU cluster to beat last year's frontier pricing is now competing against this year's cheap model, on infrastructure they already paid for.
Nadir sits underneath that decision instead of locking you into one side of it. Point your OpenAI-compatible calls at Nadir with model=auto and every request routes to whichever model, hosted frontier, hosted open-weight, or your own self-hosted fleet, is the cheapest one that can actually answer it right now. If your volume is large and steady enough that self-hosting some of the traffic makes sense, Nadir routes across your own infrastructure too, so the fixed capacity you already built gets the requests worth sending to it while the rest goes wherever the market has moved. You don't have to re-run this analysis every time a lab cuts a price.
Bottom line
Self-hosting isn't free, and it isn't a fixed win at scale either. Priced honestly, a small self-hosted deployment runs $5,000 to $15,000 a month once GPUs, redundancy, and engineering time are counted, and the volume where that fixed cost pays for itself depends entirely on which model you'd otherwise be calling, from 8.5 million tokens a day against a frontier flagship to a volume most products will never reach against the cheapest models on the market today. Run the math against your actual alternative, not the one that was true last year, and keep the utilization number honest. If you'd rather not re-run it every time pricing shifts, that's the layer routing is built to own.
Start free, or read the utilization math that decides whether your self-hosted fixed cost actually holds.
Data in the charts is illustrative, modeled from the cited research to show the shape of the tradeoff, not a live pricing feed. Sources: [IntuitionLabs, "H100 Rental Prices Compared: $1.49-$6.98/hr Across 15+ Cloud Providers," 2026](https://intuitionlabs.ai/articles/h100-rental-prices-cloud-comparison). [Spheron, "GPU Cloud Pricing Comparison 2026," 2026](https://www.spheron.network/blog/gpu-cloud-pricing-comparison-2026/). [DevTk.AI, "Self-Host LLM vs API: Real Cost Breakdown 2026"](https://devtk.ai/en/blog/self-hosting-llm-vs-api-cost-2026/). [Tensoria, "Self-Host LLMs or Use the API? Real $/1M Token Numbers in 2026"](https://tensoria.fr/en/blog/deploying-llms-to-production). [Patil, "Beyond Per-Token Pricing: A Concurrency-Aware Methodology for LLM Infrastructure Cost Estimation," arXiv:2606.11690, June 2026](https://arxiv.org/abs/2606.11690).