Abstract.
Every "tokens got cheaper" headline is describing one part of the market. A March 2026 economics paper, "Tiered Super-Moore's Law," tracked 318 models across OpenRouter and 3,237 Epoch AI pricing records from 2020 through 2026 and found the LLM inference market running on two clocks that don't average into one number. Economy-tier token prices halve roughly every 1.10 years and mid-tier every 1.55 years, both beating Moore's Law's 2-year benchmark for compute. Flagship, reasoning-capable models show almost no price trend at all against time, an R² of 0.031, because a persistent reasoning premium, priced at 31.5x the cost of a non-reasoning model, has held since 2020. The decomposition behind the fast curve is the part worth sitting with: total factor productivity, software and architecture, not chips, explains roughly 103.7% of the six-year price collapse, GPU hardware alone contributes -0.9%, and market concentration measured by the Herfindahl-Hirschman Index fell from 4,558 to 2,086 in three years as competition, not silicon, did the work. None of that reaches a workload nailed to a flagship model by default. It only reaches traffic that's actually routed down into the tier where the curve lives. This post pulls the two curves apart, then ships a script to check which one your own bill is riding.
Research question.
If flagship-tier pricing is structurally flat, not because providers refuse to compete but because a real reasoning premium has survived a 600-fold industry-wide price collapse everywhere else, what does that imply for a stack whose default is "send it to the frontier model, that's the safe choice," and how would a team actually measure whether its own spend sits on the falling curve or the flat one instead of assuming it from a vendor's press release?
Two curves, not one.
The paper's headline framing is "tiered Super-Moore's Law": each pricing tier decays on its own exponential, and only two of the three tiers decay fast enough to earn that name.
| Tier | Price half-life | vs. Moore's Law (2.0y) | Trend strength |
|---|---|---|---|
| Economy | 1.10 years | 45% faster | Strong, consistent decline |
| Mid-tier | 1.55 years | 23% faster | Strong, consistent decline |
| Flagship / reasoning | No reliable half-life | N/A | R² = 0.031 against time |
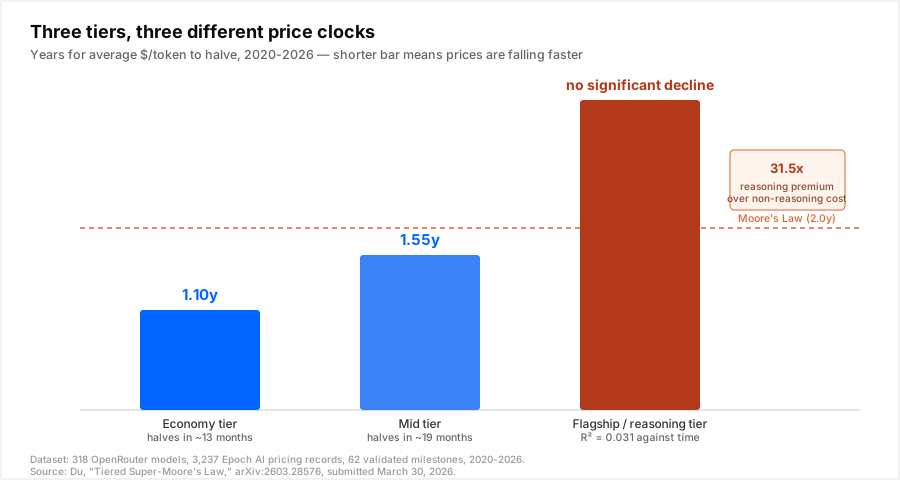
The reason the flagship row can't get a half-life isn't that its price never moves, it's that the movement doesn't correlate with time. A 31.5x reasoning premium, the extra a provider charges for a model built to run inference-time reasoning at all, sits on top of whatever the underlying compute would otherwise cost, and that premium has been remarkably durable since 2020 rather than eroding the way everything beneath it has. This blog covered the same asymmetry from a single-year angle in August, a 143-model, twelve-month snapshot that found frontier pricing rising 36.4% year over year while mid-tier and budget fell 35.8% over the same window. The six-year structural view doesn't contradict that snapshot, it explains the mechanism underneath it: a single year of frontier price movement is noise sitting on top of a premium that isn't decaying on any clock, while economy and mid-tier movement is signal riding an actual, measurable curve.
Where the collapse actually comes from.
The instinct is to credit falling prices to better GPUs. The paper's own total factor productivity decomposition says otherwise.
| Contribution to six-year price decline | Share |
|---|---|
| Total factor productivity (software, architecture, serving efficiency) | ~103.7% |
| GPU hardware improvement alone | -0.9% |
| Market concentration (HHI) | 4,558 → 2,086 over 3 years |
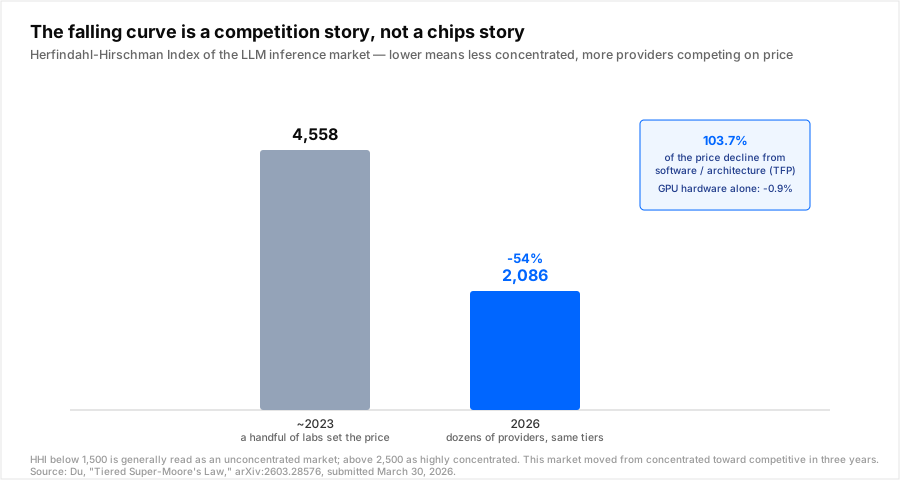
A TFP contribution north of 100% offset by a slightly negative hardware term means the paper is attributing essentially the entire decline, and then some, to serving-side software: better batching, quantization, KV-cache management, speculative decoding, and the dozens of providers that showed up to compete once open-weight models made switching cheap. The HHI drop from 4,558 (a handful of labs effectively setting the price) to 2,086 (an unconcentrated market by the standard antitrust threshold) is the market-structure fingerprint of that same shift. This blog's coverage of DeepSeek's pricing reversal in August is one instance of exactly this dynamic playing out in real time, a cost floor set by competition, not a fixed cost structure, which is also why it can move against you overnight if your routing table treats last quarter's price as a constant.
That matters for where you should expect the curve to keep working: a software-and-competition-driven decline keeps compounding as long as providers keep entering and competing at that tier. It does not require a hardware breakthrough to continue, and it does not automatically extend upward into the tier where a small number of labs, not dozens of competitors, still set the price.
Audit: which curve is your own bill actually on?
The paper fits a half-life across an entire market. The same regression, run against your own historical per-tier pricing (or better, your blended $/M tokens actually paid, not list price), tells you whether your stack has been capturing the fast curve or quietly paying the flat one because nothing ever re-routes traffic when a cheaper option appears.
import math

# Your own logged blended cost per million tokens, by tier, by year.
# Use *paid* cost, not list price — a stale routing table can leave you
# paying last year's rate on this year's traffic even if the market moved.
usage = {
    "economy": {2023: 1.80, 2024: 0.90, 2025: 0.55, 2026: 0.42},
    "mid":     {2023: 6.50, 2024: 4.70, 2025: 3.80, 2026: 3.10},
    "flagship":{2023: 15.0, 2024: 22.0, 2025: 18.0, 2026: 30.0},
}

# Industry benchmarks from the paper, for comparison.
BENCHMARKS = {"economy": 1.10, "mid": 1.55, "flagship": None}

def fitted_half_life(prices_by_year: dict[int, float]):
    """Log-linear regression of price against year, same statistic
    the paper reports per tier. Returns (half_life_years, r_squared)."""
    years = list(prices_by_year.keys())
    log_p = [math.log(p) for p in prices_by_year.values()]
    n = len(years)
    mean_x, mean_y = sum(years) / n, sum(log_p) / n
    cov = sum((x - mean_x) * (y - mean_y) for x, y in zip(years, log_p))
    var_x = sum((x - mean_x) ** 2 for x in years)
    slope = cov / var_x
    ss_res = sum((y - (mean_y + slope * (x - mean_x))) ** 2 for x, y in zip(years, log_p))
    ss_tot = sum((y - mean_y) ** 2 for y in log_p)
    r_squared = 1 - ss_res / ss_tot if ss_tot else 0.0
    half_life = math.log(2) / -slope if slope < 0 else None
    return half_life, r_squared

for tier, prices in usage.items():
    half_life, r_squared = fitted_half_life(prices)
    benchmark = BENCHMARKS.get(tier)
    if half_life is None or r_squared < 0.05:
        print(f"{tier}: no reliable decline (R²={r_squared:.2f}) — you're paying the flat curve")
    elif benchmark and half_life > benchmark * 1.5:
        print(f"{tier}: halving every {half_life:.2f}y vs. {benchmark}y industry pace — "
              f"capturing less than half the available curve")
    else:
        print(f"{tier}: halving every {half_life:.2f}y — tracking the industry curve")
Run against the placeholder numbers above, economy and mid-tier both come back tracking the fast curve, and flagship comes back with a rising trend and a low R², the same "no reliable decline" verdict the paper reaches at market scale. That third line is the one worth checking honestly against your own invoices: a rising flagship number isn't a bug in the fit, it's what a 31.5x premium sitting on top of a fast-moving base cost is supposed to produce once the base cost is small enough for the premium to dominate the total.
What this doesn't solve.
This is a single-author paper, not a replicated multi-team study, and 2020-2026 model-tier boundaries are the author's own classification, not a standard every provider agrees on, so a model near a tier boundary could land in a different bucket under a different scheme. A 31.5x reasoning premium measured across the market average doesn't mean every reasoning model prices that far above every non-reasoning peer, some gaps are narrower, some wider. And an R² of 0.031 means "no detectable linear trend over six years," not "this price will never fall," a single aggressive new entrant at the flagship tier could move that number the same way DeepSeek moved the floor at the bottom. The HHI and TFP figures describe the market in aggregate; they say nothing about whether your specific vendor contract is passing that competitive pressure through to you.
What to check before you assume you're on the falling curve.
- Fit the half-life on paid cost, not list price. A vendor's published rate card can fall while your actual blended cost stays flat, because a routing table or hardcoded model string never picked up the new number.
- Treat "we use the frontier model for safety" as a line item, not a default. The RouteLLM finding that 74% of GPT-4-class calls didn't need GPT-4-class quality is the other half of this argument: most of what's parked on the flat curve doesn't need to be there.
- Re-check your cheap-tier vendor at least quarterly, not annually. A cost floor set by competition can reverse with one earnings call, and a stale routing table is the single most common way a team pays 2024's premium on 2026's traffic.
- Separate "reasoning capability" from "reasoning by default." A verifier or cascade that only escalates to the reasoning tier when a cheaper model's confidence is actually low keeps the premium contained to the traffic that needs it, instead of applying it uniformly.
- **Nadir routes each request against current market pricing across dozens of providers**, which is the practical version of "capture the fast curve automatically": the model choice gets re-evaluated against this quarter's prices instead of whichever integration a team shipped before the last repricing, the same instinct behind pairing routing with compression instead of picking one lever.
Conclusion.
The market isn't getting cheaper. Two-thirds of it is, on a curve that beats Moore's Law and is driven almost entirely by software and competition rather than better chips, and the remaining third, the tier a "just use the best model" default lands on by construction, has shown no reliable price decline in six years because a 31.5x reasoning premium has proven more durable than the compute underneath it. A team that never checks which curve its own spend sits on is implicitly betting that six years of a 600-fold industry-wide price collapse will eventually reach the flagship tier on its own. The paper's own numbers say that bet hasn't paid off yet, and the fix isn't waiting for it to. It's routing the traffic that doesn't need the premium off the flat curve and onto the one that's actually falling.
Sources: [Du, "Tiered Super-Moore's Law: Price Evolution, Production Frontiers, and Market Competition in Large Language Model Inference Services," arXiv:2603.28576, submitted March 30, 2026](https://arxiv.org/abs/2603.28576). [The Two-Speed Market](/blog/frontier-pricing-up-mid-tier-down-2026). [The Floor Just Moved](/blog/deepseek-price-hike-cheap-tier-routing-risk). [RouteLLM: 74% of GPT-4 calls did not need GPT-4](/blog/routellm-74-percent-gpt4-calls-dont-need-gpt4). [Compression saves you once. Routing plus compression saves you twice.](/blog/compression-plus-routing-save-twice)