Abstract.
Every long-horizon agent hits the same wall eventually: the context window fills up with tool results, file contents, half-finished plans, and constraints the user stated four turns ago, and something has to give. Today's answer is usually one of two blunt instruments: drop the oldest messages, or ask the model to write a summary and hope nothing load-bearing got compressed away. A July 2026 paper from Xiaohongshu (arXiv:2607.00692) proposes a third option, borrowed from a discipline that solved a version of this problem decades ago: garbage collection. Self-GC turns an agent's accumulated context into indexed objects, has a planner decide per object whether to fold, mask, or prune it based on future dependency rather than age, and commits that decision through a harness step that keeps a recoverable sidecar and doesn't break the model provider's prompt cache. On an adversarial 33-session test set, it pruned 43.95% of prefix tokens while leaving 84.85% of future continuations unaffected, clearly ahead of heuristic baselines that pruned harder and still broke more. On a 332-session production-derived suite, three separate planner backbones held 91.27% to 94.58%. It's already running: an account-level production split cut daytime average input tokens 10 to 15%, with peak reductions near 20%.
Research question.
If an agent's context is treated as a set of objects with a lifecycle, indexed, scored for future dependency, and prunable through a recoverable, cache-aware commit path, rather than as a flat text log truncated by age, how much can be safely removed, and does the resulting system still hold up once it's carrying real production traffic instead of a benchmark set?
Why chronological pruning and self-summary both fail long-horizon agents.
Long-horizon agents don't accumulate context the way a chat transcript does. A single session can carry a file's full contents fetched three tool calls ago, a plan the agent committed to two turns back, a constraint the user stated once and never repeated, and a dozen intermediate tool results of wildly different relevance to whatever the agent is about to do next. That's structured state, not disposable text, and the paper's framing is blunt about why the common fixes don't treat it that way. Chronological pruning drops what's oldest, on the assumption that older roughly means less relevant, an assumption that breaks the moment a plan or constraint from early in the session is still exactly what a later step needs. Tool-output masking hides results using the same blind, age-based logic. A final self-summary near the context limit avoids that specific failure but introduces a different one: it compresses everything into prose, and prose is bad at preserving exact evidence, precise locators, or artifacts a later step needs to edit rather than just read about. The same failure mode this blog measured in Chroma's context-rot research: the tokens hurting accuracy and the tokens inflating the bill are usually the same tokens, and a fix that's blind to which tokens those are can't reliably target them.
Context as objects, not a text suffix.
Self-GC's mechanism, echoing the name on purpose, mirrors how a real garbage collector works: not "delete anything old," but "track every object, decide what's still reachable from where the program is headed, and reclaim the rest, recoverably." Three stages.
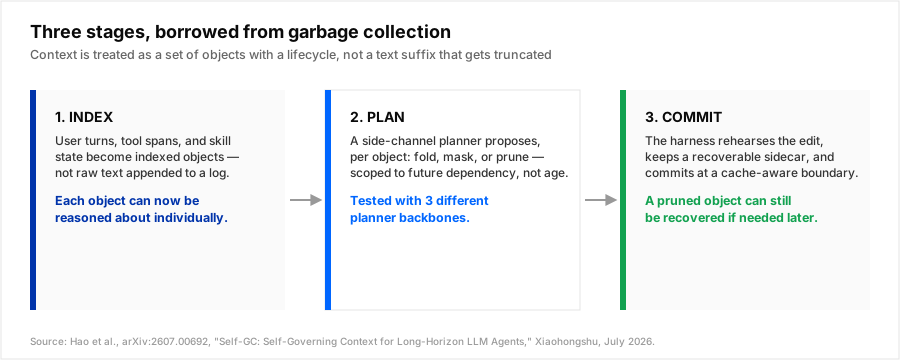
Index. User turns, tool spans, and skill state get turned into indexed objects instead of staying appended text. That's what makes the next two steps possible at all, you can't reason about "does anything downstream still need this" if the thing in question isn't addressable on its own.
Plan. A side-channel planner, a separate model call outside the main agent loop, looks at the indexed objects and proposes an action per object: fold it into a shorter form, mask it (hide it from the prompt but keep it retrievable), or prune it outright. The decision is scored against future dependency, not recency, which is the direct fix for what chronological pruning gets wrong.
Commit. This is the step that keeps the system honest. The harness rehearses the proposed edit rather than applying it blind, keeps a recoverable sidecar so a folded or pruned object isn't gone for good, and only commits at a boundary chosen to respect the model provider's prompt cache. That last part matters more than it might look: a compression or pruning step that rewrites the same prefix on every call breaks prefix caching outright, turning a token-saving move into a cache-invalidating one that can cost more than doing nothing. Self-GC's commit step is built around avoiding exactly that trap.
The numbers: pruning harder is not the same as pruning safely.
The paper reports two evaluation regimes, and the contrast between them is the paper's real argument.
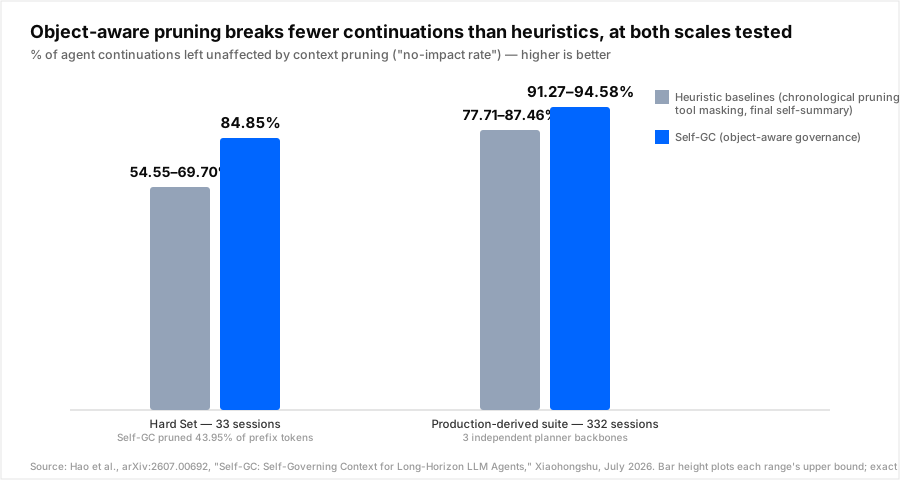
| Evaluation | Sessions | Self-GC no-impact rate | Baseline no-impact rate |
|---|---|---|---|
| Hard Set (adversarial) | 33 | 84.85% (43.95% of prefix tokens pruned) | 54.55–69.70% |
| Production-derived suite | 332 | 91.27–94.58% (3 planner backbones) | 77.71–87.46% |
Read the Hard Set row carefully, because the detail that matters isn't the headline percentage, it's what the paper says right next to it: the heuristic baselines pruned more aggressively than Self-GC's 43.95% and still landed a lower no-impact rate. More pruning did not mean better pruning. That's the whole case against age-based heuristics in one line: they have no way to tell the difference between a token that's safe to drop and one that isn't, so more aggressive pruning just means more of both.
It held at production scale, and it shipped.
A result that only survives on a 33-session hand-built set is a demo. The paper also ran the comparison on a 332-session production-derived suite, and tested it against three different planner backbones rather than one tuned model, both a check against the result being an artifact of one specific setup. The no-impact rate held in the 91 to 95% range across all three, comfortably ahead of every baseline tested. Then it went further than most systems papers do: an online account-level split in production measured daytime average input tokens down 10% to 15%, with peak reductions near 20%. That's a smaller number than the benchmark's headline pruning rate, which is exactly what you'd expect, real production traffic is messier and less uniformly prunable than a curated evaluation set, and it's a more trustworthy number for the same reason.
Where cache-aware commit fits next to compression and caching.
This isn't a replacement for the token-reduction techniques already in a typical stack, it's a layer aimed at a different failure mode.
| Compression (LLMLingua-style) | Prompt caching | Self-GC | |
|---|---|---|---|
| What it acts on | A single request's prompt text | A repeated, byte-identical prefix | Multi-turn agent state across a whole session |
| Decision basis | Token-level information score | Exact prefix match | Object-level future dependency |
| Reversible if wrong | No, tokens are gone | N/A, nothing is removed | Yes, recoverable sidecar |
| Breaks the prefix cache if applied naively | Yes, if compression output changes per call | N/A | Designed not to, via cache-aware commit |
| Best target | A single long prompt or retrieved document | Static system prompts, tool schemas | Long-horizon, multi-turn session state |
The three stack rather than compete: compression shrinks what's about to be sent, caching discounts what repeats unchanged, and object-level context governance decides what's still in the window at all by the time either of the other two gets a turn. This blog has already shown that these levers are multiplicative, not additive, when they interact well, and can actively cancel out when one breaks the other's assumptions; Self-GC's cache-aware commit step is a direct example of a system built to avoid the cancel-out case on purpose, rather than discovering it in a postmortem.
Build a simplified version against your own agent loop.
You don't need the paper's exact planner or its evaluation harness to test the underlying idea against your own agent. The shape of a minimal version:
from dataclasses import dataclass, field
from enum import Enum

class Action(Enum):
    KEEP = "keep"
    FOLD = "fold"
    MASK = "mask"
    PRUNE = "prune"

@dataclass
class ContextObject:
    id: str
    kind: str          # "user_turn" | "tool_span" | "skill_state"
    content: str
    # sidecar holds the full original content even after fold/mask/prune,
    # so a later step can still recover it if the planner guessed wrong.
    sidecar: str = field(default="")

def plan_actions(objects: list[ContextObject], upcoming_task: str, planner_lm) -> dict[str, Action]:
    """Side-channel call: ask a planner model which objects the
    upcoming step actually depends on, not which ones are oldest."""
    prompt = (
        f"Upcoming task: {upcoming_task}\n\n"
        f"Objects in context:\n" +
        "\n".join(f"[{o.id}] ({o.kind}) {o.content[:200]}" for o in objects) +
        "\n\nFor each object id, return keep, fold, mask, or prune, "
        "based on whether the upcoming task still depends on it."
    )
    return planner_lm.structured_complete(prompt, schema=dict[str, Action])

def commit(objects: list[ContextObject], actions: dict[str, Action], cache_boundary_id: str):
    """Harness step: apply only past the cache boundary, keep sidecars,
    never destroy content that was pruned or folded."""
    committed = []
    past_boundary = False
    for o in objects:
        past_boundary = past_boundary or o.id == cache_boundary_id
        action = actions.get(o.id, Action.KEEP)
        if not past_boundary or action == Action.KEEP:
            committed.append(o)
            continue
        o.sidecar = o.sidecar or o.content
        if action == Action.FOLD:
            o.content = summarize(o.content)  # short form, sidecar keeps the full original
        elif action == Action.MASK:
            o.content = f"[masked, recoverable: {o.id}]"
        elif action == Action.PRUNE:
            continue  # dropped from the live window, sidecar still holds it
        committed.append(o)
    return committed
The two details worth keeping even in a much simpler version: never overwrite sidecar once it's set, so a wrong prune is recoverable, and never apply an action ahead of cache_boundary_id, so the edit doesn't retroactively change a prefix a provider might have already cached. Nadir's context optimization already strips redundant tool schemas and repeated boilerplate before a request goes out, which is the single-request version of the same instinct; this is the same discipline applied across an entire multi-turn session instead of one call.
What this doesn't solve.
The planner step is an LLM call, or a call to a smaller model standing in as one, so it's a side-channel cost that has to stay smaller than the tokens it reclaims, plus whatever latency it adds to the loop. The published numbers come from one company's production traffic and a 33-session adversarial set built to stress-test the approach; both are real evidence, neither guarantees the same no-impact rate on a materially different agent workload with a different mix of tool calls and session lengths. And this is a systems paper describing one company's design, not a benchmark run against every existing long-horizon memory approach, so treat the specific percentages as evidence the design pattern works, not as a universal constant to plug into a different stack unmeasured.
Conclusion.
The insight Self-GC is built on isn't complicated: an agent's context is not one flat string that gets longer, it's a collection of distinct objects with different lifetimes, and pruning by age throws away exactly as much signal as it happens to catch by accident. Indexing objects, scoring them against what's actually coming next, and committing the result through a path that keeps things recoverable and doesn't quietly break the prompt cache, is closer to how any other long-running system manages memory than what most agent harnesses do today. The gap between "pruned 43.95% and broke 15% of continuations" and "pruned harder and broke 30 to 45% of them" is the whole argument for treating context governance as its own discipline, not a side effect of however truncation happens to be implemented this week.
Sources: [Hao, Meng, Yin, Zhu, and Cao, "Self-GC: Self-Governing Context for Long-Horizon LLM Agents," arXiv:2607.00692, Xiaohongshu, submitted July 1, 2026](https://arxiv.org/abs/2607.00692).