Every routing paper on this blog eventually runs into the same assumption: you know, for every request, whether the model got it right. Production doesn't work that way. Most users never rate a response. The ones who do are the ones who were unhappy. A router trained as if every request came back labeled "good" or "bad" is trained on data that doesn't exist. A June 2026 paper from TU Munich and the University of Exeter, SLARouter, builds a routing policy that assumes the opposite from the start: feedback arrives for maybe one request in five, it's one-sided (you mostly learn about failures, not successes), and the router still has to hold a formal quality guarantee, a Service Level Agreement, on every request in between. It reports up to 2.2x lower operating cost than existing routing baselines while doing it. This post is about the mechanism that makes that possible, and what a minimal version looks like if you wanted to prototype it yourself.
The feedback you don't have.
Most published cost-aware routing work trains offline, on a labeled dataset where every (query, model, outcome) triple is known. That's a reasonable way to build a benchmark. It's not how a production system sees the world. In production, a satisfaction signal, a thumbs-down, a regenerate click, a support ticket, shows up for a small slice of traffic, and it skews toward the requests that went badly. The requests that went fine mostly generate silence, not a labeled positive.
This blog has already covered why that same asymmetry breaks router calibration: a confidence score trained without knowing the true failure rate looks fine on paper and fails quietly in production. SLARouter's contribution is narrower and more useful than "route better": it's a way to keep a formal cost-quality guarantee standing on a feedback stream that's sparse and biased toward bad news, instead of assuming the labeled dataset a benchmark gives you for free.
How SLARouter closes the loop.
The mechanism has three moving parts, and none of them require retraining offline between deployments.
A satisfaction predictor. A lightweight multi-label classifier estimates, per request, how likely the response is to satisfy the user. It's trained continuously on whatever labels actually arrive, not on a fixed offline set.
A virtual queue. Instead of tracking SLA compliance as a single running average, SLARouter keeps a queue that accumulates when the guarantee is being violated and drains when it's being met. The queue, not a fixed threshold, is what the policy reacts to, which is what lets the guarantee hold even when the input signal is noisy.
Exploration that decays. Early on, the router samples across the model pool more freely to learn the predictor faster. As the predictor matures, exploration probability decays and the policy shifts toward the cost-optimal choice it now has evidence for.
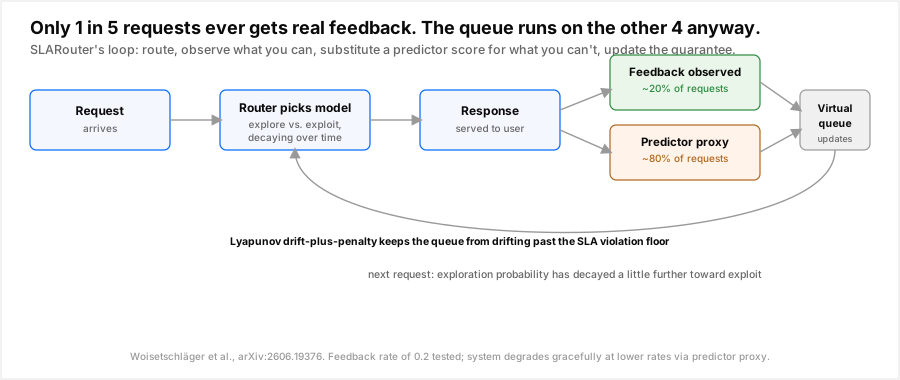
The detail worth sitting with is the middle branch. When real feedback doesn't arrive, the queue doesn't just skip the update, it substitutes the predictor's own score as a proxy. That's the one-sided-feedback problem solved directly rather than worked around: the system doesn't wait for ground truth to keep the guarantee moving, it uses its best current estimate and lets the theory (a Lyapunov drift-plus-penalty bound) say how much error that introduces.
The target moves with the task.
The paper doesn't test one SLA target across the board. Across 11 benchmarks, from GSM8K and MMLU to ARC, BoolQ, GPQA, and ACPBench, the satisfaction target SLARouter is asked to hold ranges from 45% to 96%, calibrated to what's actually achievable on that task with the Qwen 3.5 model pool (2B, 9B, 35B, 122B) it routes across.
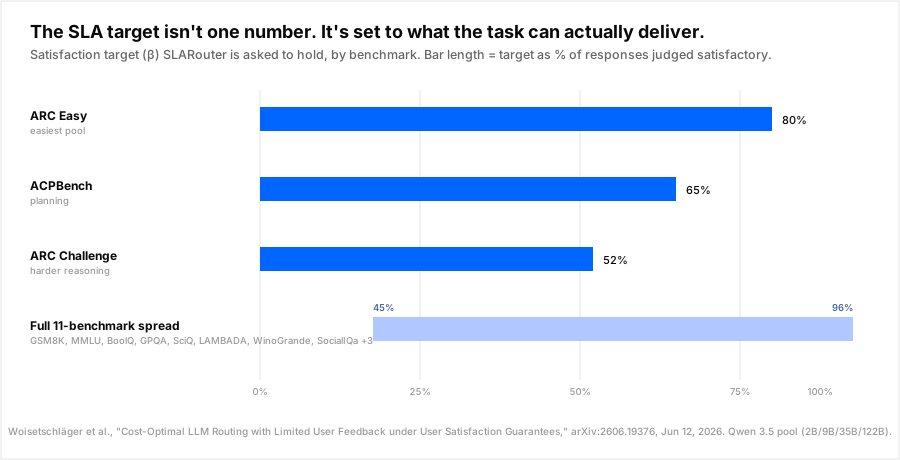
That's a design choice worth borrowing on its own, independent of the routing algorithm underneath it: a single global "95% satisfaction" SLA is meaningless if even the best available model can't clear it on the hardest slice of your traffic. Setting the guarantee per task, per difficulty band, is what makes the guarantee enforceable instead of aspirational.
The numbers.
| Measurement | Result |
|---|---|
| Cost reduction vs. existing routing baselines | Up to 2.2x, while holding SLA compliance |
| Feedback rate tested | 0.2 (one in five requests returns real feedback) |
| Model pool | Qwen 3.5 family: 2B, 9B, 35B, 122B |
| Benchmark suite | 11 datasets: MMLU, GSM8K, ARC Challenge, ARC Easy, BoolQ, GPQA, SciQ, LAMBADA, WinoGrande, SocialIQa, ACPBench |
| Tuning required per benchmark | None; theoretical guarantee holds without per-workload calibration |
The "no per-benchmark tuning" line is the part that separates this from a routing paper that just reports a good number on its own benchmark. RouterArena's oracle-gap finding and LLMRouterBench's result that most published routers lose to a static baseline off their home turf both make the same point from the failure side: a router that needs re-tuning per workload to hit its headline number isn't a router you can trust on traffic it hasn't seen. A formal guarantee that holds across 11 benchmarks without retuning is a different, stronger claim.
A minimal version to prototype.
The full system trains a classifier and solves a constrained optimization over the Lyapunov bound. The part worth prototyping first is smaller: a virtual queue, and exploration that decays as the queue tells you the predictor is trustworthy.
import random

class SLAQueue:
    """Tracks SLA violations as a virtual queue instead of a running
    average. Grows when the guarantee is missed, drains when it's met."""

    def __init__(self, target_satisfaction: float, drain_rate: float = 0.05):
        self.target = target_satisfaction   # e.g. 0.65 for a harder task
        self.queue = 0.0
        self.drain_rate = drain_rate

    def update(self, satisfied: float):
        """satisfied: 1.0/0.0 from real feedback, or the predictor's
        probability score when no feedback arrived this request."""
        violation = self.target - satisfied
        self.queue = max(0.0, self.queue + violation - self.drain_rate)
        return self.queue


class ExploreDecayRouter:
    """Routes across a cost-ordered model pool. Exploration probability
    decays as the queue confirms the predictor is holding the target."""

    def __init__(self, models: list[str], queue: SLAQueue, decay: float = 0.999):
        self.models = models  # cheapest first
        self.queue = queue
        self.explore_p = 0.3
        self.decay = decay

    def route(self, predict_satisfaction) -> str:
        self.explore_p *= self.decay
        if random.random() < self.explore_p or self.queue.queue > 1.0:
            # explore, or the queue says the cheap tier is under-delivering
            return random.choice(self.models)
        # exploit: cheapest model the predictor believes clears the target
        for model in self.models:
            if predict_satisfaction(model) >= self.queue.target:
                return model
        return self.models[-1]  # nothing cleared the bar, go to the top

    def observe(self, real_feedback: float | None, predicted_score: float):
        signal = real_feedback if real_feedback is not None else predicted_score
        self.queue.update(signal)
The mechanism that makes this different from a plain epsilon-greedy bandit is self.queue.queue > 1.0 forcing exploration back open. A bandit that's decayed its exploration to near zero and then starts silently missing its target has no way to notice; a queue that's allowed to grow when violations accumulate gives the policy a reason to look again, which is the practical form of the paper's theoretical guarantee.
What this doesn't solve.
The benchmark suite is public QA and reasoning tasks scored against a model pool the authors controlled end to end; production traffic is messier, and a satisfaction predictor trained on one model roster needs re-validation, not just re-weighting, when the roster changes. A 0.2 feedback rate is also a specific, tested point, not a floor; the paper notes the system degrades gracefully at lower rates by leaning more on the predictor, but a predictor with too little ground truth to correct against is a predictor that can drift confidently wrong, the exact failure mode this blog covered in router calibration work. And a virtual queue's whole guarantee is asymptotic: early in a cold start, before the predictor has enough signal, the theory doesn't promise the SLA holds turn by turn, only that the time-averaged violation converges toward the paper's stated error floor.
What to check before you build one.
- Calibrate the SLA target per task, not globally. A single "95% satisfied" number across a mixed workload is either unenforceable on your hardest traffic or wastes money over-serving your easiest traffic. Set it per task band, the way this paper sets it per benchmark.
- Instrument your real feedback rate before assuming a number. 20% is what the paper tested; if your product surfaces a rating UI, a regenerate button, or support tickets at a materially lower rate, the predictor is carrying more of the weight and needs more scrutiny, not less.
- Let the queue reopen exploration, don't just decay it to zero. A policy that stops looking is a policy that can't tell you when its own predictor has gone stale.
- Track predictor accuracy against the feedback you do get, continuously. The moment predicted and real satisfaction start diverging on the labeled slice, that's your early warning the proxy signal is drifting, before the SLA breach shows up downstream.
- **Nadir's cascade router already routes on a live cost-quality signal per request**, the same problem this paper is solving from a different angle, holding a quality bar while minimizing spend without requiring a labeled dataset for every workload before it can start saving money.
Conclusion.
Most routing research quietly assumes a dataset that production never hands you: complete, timely, symmetric feedback on every request. SLARouter's real contribution isn't the 2.2x number, it's building the guarantee around the feedback stream that actually exists, sparse, one-sided, and biased toward complaints, using a virtual queue and a decaying exploration policy instead of a fixed threshold that silently breaks when the input data doesn't match the paper it came from. The practical takeaway travels even if you never touch the Lyapunov math: calibrate your quality bar per task instead of globally, and build your monitoring around the assumption that most of your traffic will never tell you how it went.
Sources: [Woisetschläger, Mammadli, Zhang, Wang, "Cost-Optimal LLM Routing with Limited User Feedback under User Satisfaction Guarantees," arXiv:2606.19376, submitted June 12, 2026](https://arxiv.org/abs/2606.19376). [Confidently Wrong: LLM Router Calibration](/blog/confidently-wrong-llm-router-calibration). [The Oracle Gap: RouterArena](/blog/routerarena-llm-router-benchmark-oracle-gap). [LLMRouterBench: Most Routers Fail Baseline](/blog/llmrouterbench-acl-2026-most-routers-fail-baseline). [FrugalGPT Cascade Routing: Implementation Guide](/blog/frugalgpt-cascade-routing-implementation-tutorial).