Abstract.
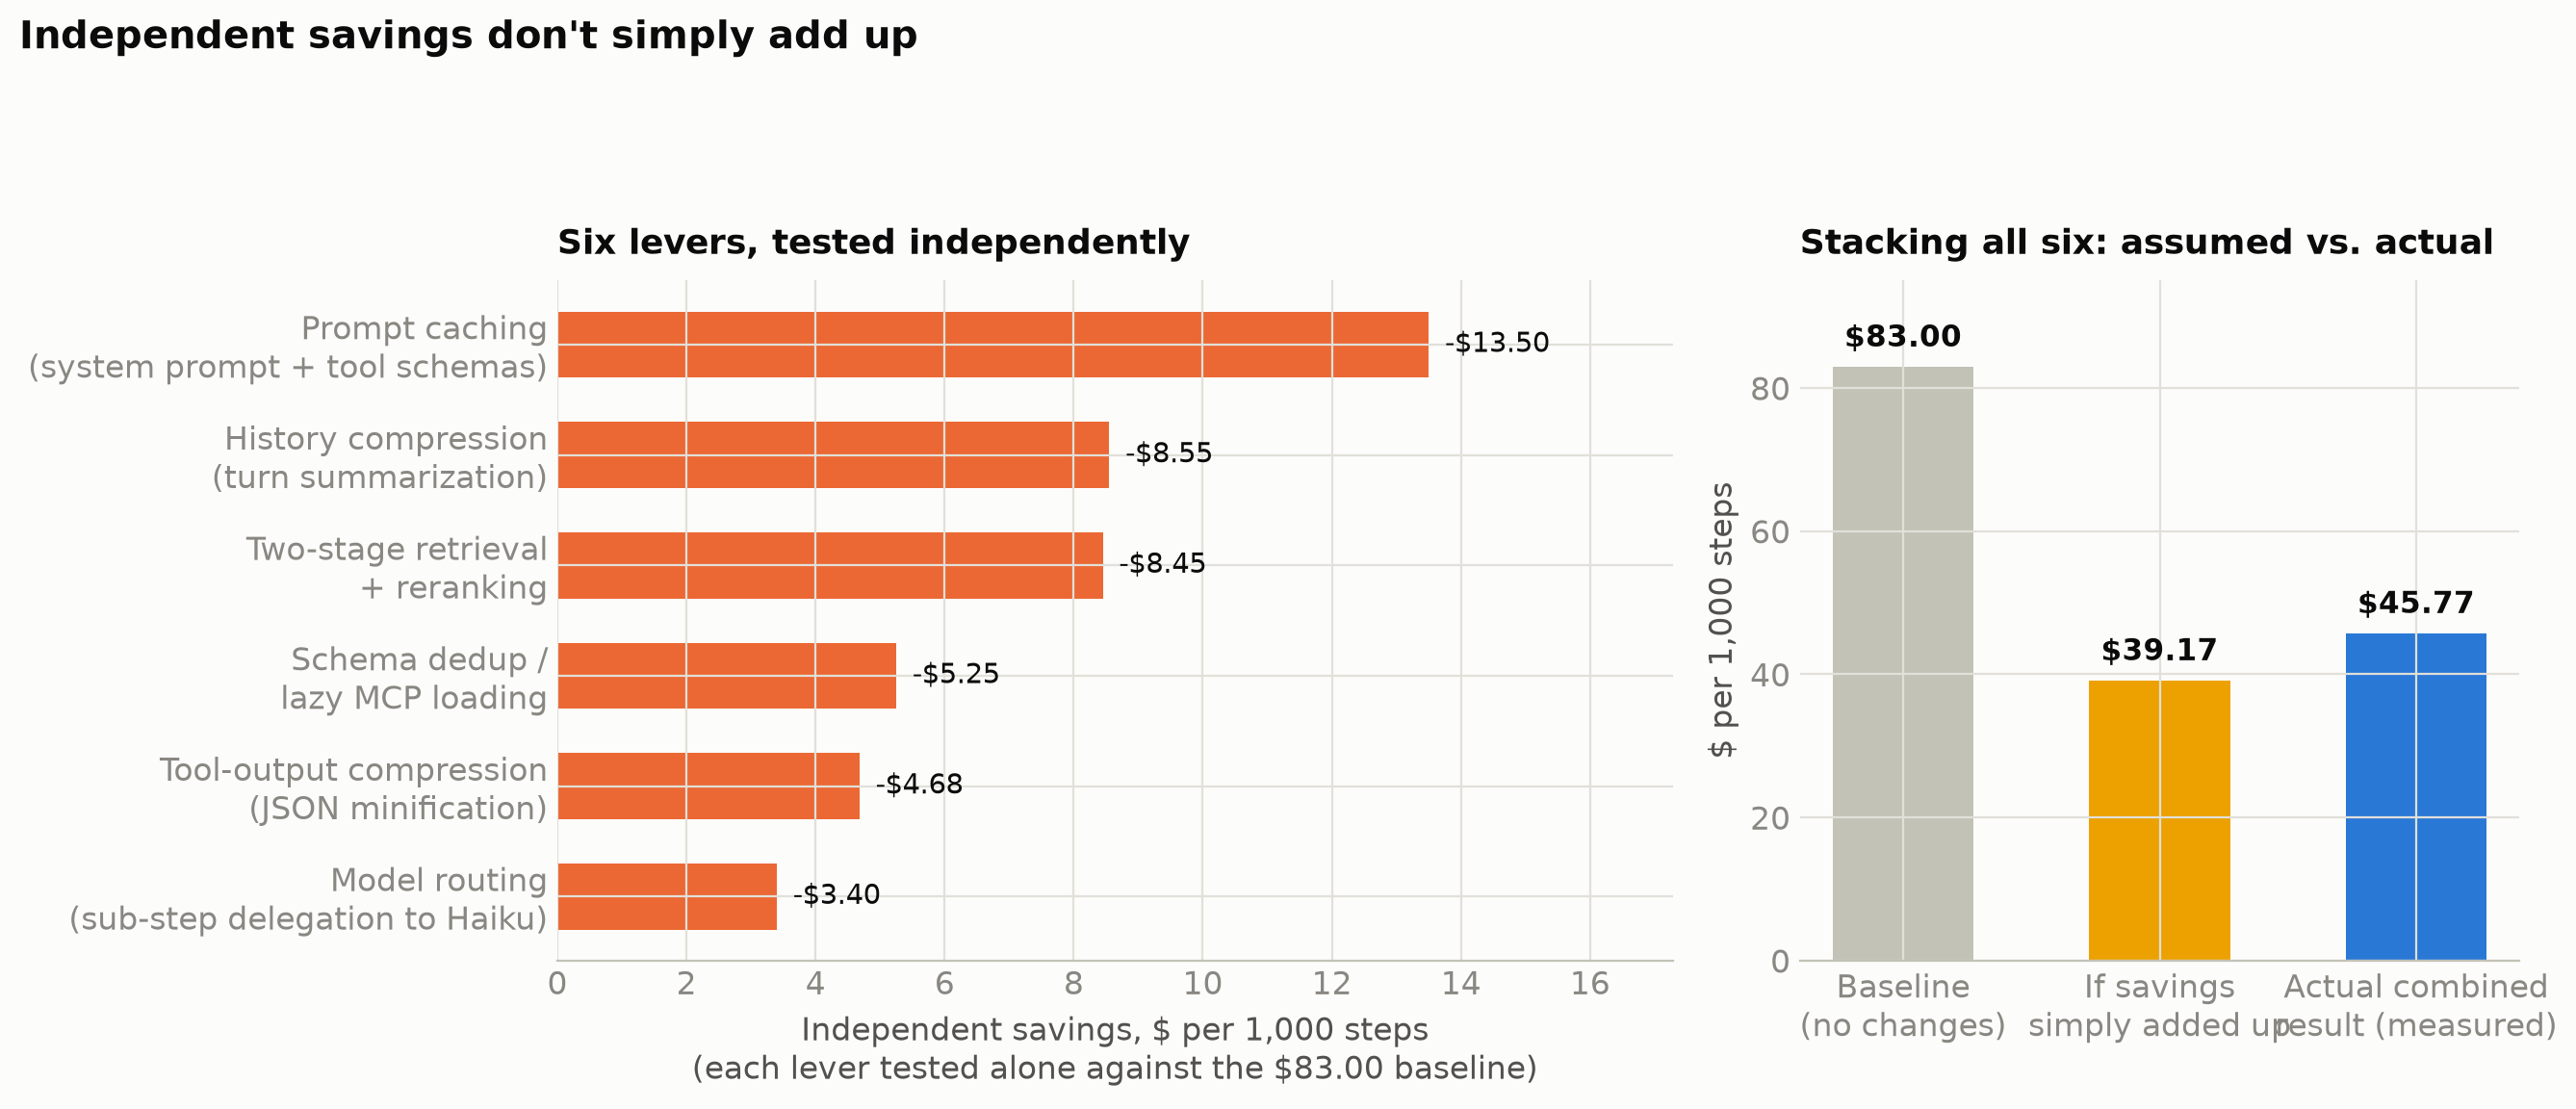
Most LLM cost-optimization advice reads as a list: cache your prompts, compress your context, route to cheaper models, retrieve fewer chunks. What is missing is a ranking. This post builds a step-level cost model of a ReAct research agent, then runs a sensitivity analysis: it tests six optimization levers independently against the same baseline to see which one actually moves the bill, and by how much. The ranked result (a tornado chart, borrowed from financial and engineering risk analysis, not something this blog has used before) shows prompt caching and history compression deliver more than half of all available savings, while the two levers most teams reach for first, model routing and output compression, deliver the least. It also finds something the independent tests hide: summing the six levers' savings overstates the real, measured combined reduction by about 18%, because several levers compete for the same overlapping tokens. The practical implication is that optimization order matters as much as optimization choice, and that measuring levers independently, without checking for overlap, produces a cost forecast that will not survive contact with a real stacked implementation.
All data and code in this post are illustrative, modeled from a synthetic step-level cost model built for this analysis. Not derived from proprietary production traces. Anthropic pricing as of June 2026. Methodology and full assumptions below.
Why elasticity, not just optimization.
Every team that inherits an agentic LLM bill eventually reaches for the same playbook: cache what repeats, compress what's verbose, route what's simple, retrieve less. This blog has covered each of those levers on its own, and each one, in isolation, works.
What none of that coverage answers is a question every engineering lead actually has when they're staring at a sprint board with six optimization tickets on it and time to ship two: which two? Teams tend to default to whichever lever is most talked about (usually model routing, because "just use a cheaper model" is the intuitive first move) rather than whichever lever actually returns the most savings for the effort.
Economists have a word for this kind of question: elasticity, how much an outcome moves in response to a change in one input, holding everything else constant. Engineering risk analysis has a chart for it: the tornado diagram, which ranks variables by how much they swing an outcome when flexed independently. This post borrows both, applies them to LLM agent cost, and checks whether the ranking survives when the levers are actually stacked together instead of tested one at a time.
Research question.
Given a fixed-baseline ReAct agent, which individual cost-optimization lever produces the largest marginal reduction in per-step cost, and does the sum of independently-measured lever savings predict the actual savings when all levers are combined?
Methodology.
The baseline is a 5-step ReAct research agent (reason, search, read, reason, synthesize) measured at step 3, the point where accumulated context is representative of steady-state production behavior. This is the same agent shape used in this blog's earlier token-anatomy analysis; the bucket values here are a fresh, self-contained model built for this sensitivity test, not a re-statement of that post's figures.
Model: Claude Opus 4.8, $5/M input tokens, $25/M output tokens (Anthropic pricing, June 2026). Baseline step-3 cost breakdown:
| Token bucket | Cost/step | % of baseline |
|---|---|---|
| System prompt | $0.0045 | 5.4% |
| Tool schemas | $0.0105 | 12.7% |
| Prior search results in context | $0.0085 | 10.2% |
| Retrieved document chunks | $0.0130 | 15.7% |
| Accumulated history | $0.0190 | 22.9% |
| Synthesis (output) | $0.0275 | 33.1% |
| Total | $0.0830 | 100% |
Baseline: $83.00 per 1,000 steps.
Six levers were defined, each targeting a specific bucket, with a reduction percentage chosen from the ranges reported in prior public work on the same mechanisms (see sources): prompt caching (90% discount on cached prefix tokens, per Anthropic's documented cache pricing), two-stage retrieval and reranking (65% cut to irrelevant chunk volume, consistent with the finding that models meaningfully use 2 to 4 of every 10 retrieved chunks regardless of how many are provided), history compression via turn summarization (45%), tool schema deduplication and lazy MCP registration (50%), tool-output compression via JSON minification (55%), and model routing of sub-step classification work (query generation, chunk scoring) to a cheaper model (40% effective reduction on that bucket).
Sensitivity test: each lever was applied alone, against the unmodified baseline, and the resulting $ savings recorded. This isolates each lever's individual effect, exactly as a tornado analysis requires.
Combination test: all six levers were then applied together, bucket by bucket, in the order a team would actually implement them (dedup before caching on the shared schema bucket, routing before output compression on the shared search-results bucket), to see whether the combined result matches the sum of the independent tests.
All figures are illustrative and computed from the model above, not measured from production traffic. The arithmetic is reproducible from the assumptions stated here.
Results.
1. Where the baseline cost actually sits.
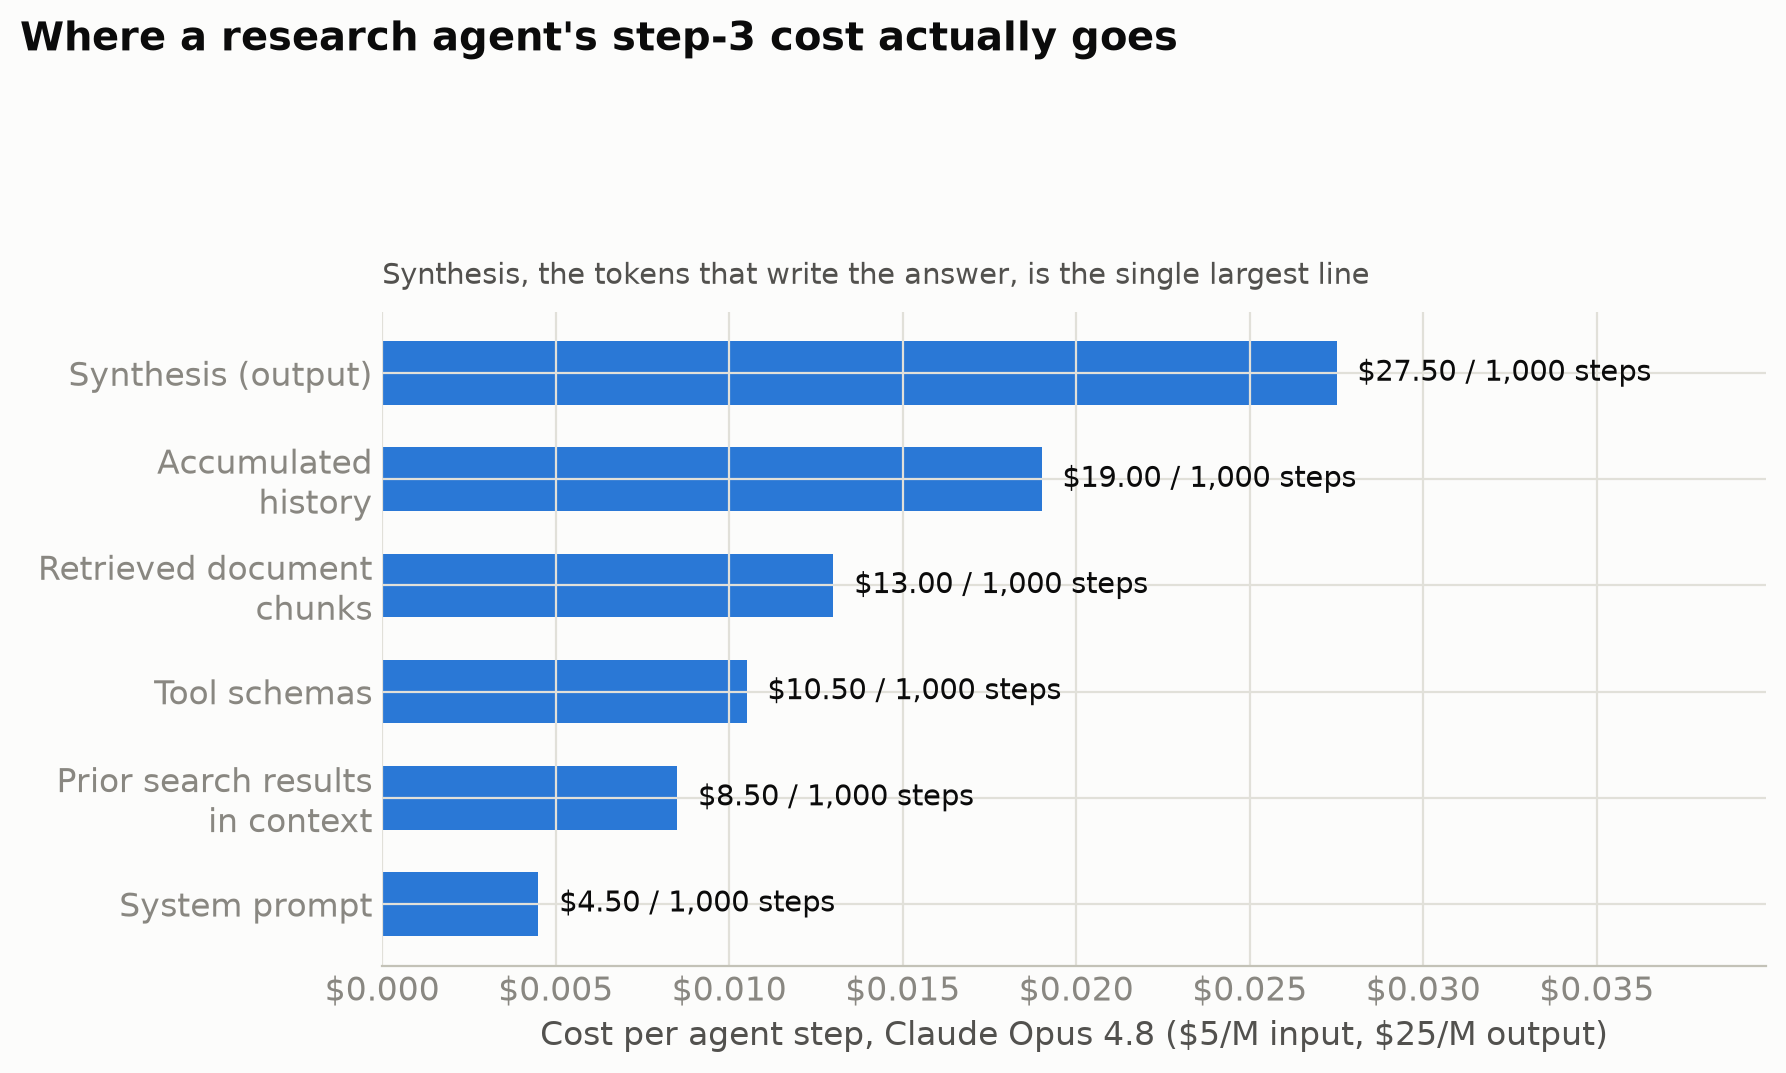
Synthesis, the tokens that produce the answer, is the single largest line item at 33% of cost. That is the correct place for spend to concentrate. The next four categories combined (history, chunks, schemas, prior search results) account for 61.5% of cost and touch zero words of the final answer.
2. The tornado: which lever actually moves the bill.
| Lever | Independent savings/1,000 steps | % of baseline |
|---|---|---|
| Prompt caching (system prompt + tool schemas) | $13.50 | 16.3% |
| History compression (turn summarization) | $8.55 | 10.3% |
| Two-stage retrieval + reranking | $8.45 | 10.2% |
| Schema dedup / lazy MCP loading | $5.25 | 6.3% |
| Tool-output compression (JSON minification) | $4.68 | 5.6% |
| Model routing (sub-step delegation) | $3.40 | 4.1% |
The ranking does not match the order most teams implement these in. Model routing, the lever with the most engineering attention in this space, ranks last in this model. Prompt caching, a configuration flag with no architecture change, ranks first. This matches this blog's earlier finding that caching alone delivers roughly a third of available savings on agentic workloads, for the same underlying reason: it requires no accuracy tradeoff and no retry risk, so its savings are close to free.
3. Independent savings do not add up.
Summing the six independent results predicts $43.83 in savings, implying a combined cost of $39.17 per 1,000 steps, a 52.8% reduction. Measuring the levers stacked together (in implementation order, respecting which buckets overlap) gives a combined cost of $45.77, a 44.9% reduction.
The gap is 7.9 percentage points, or the naive sum overstating real savings by about 18% in relative terms. The reason is structural, not statistical noise: two pairs of levers compete for the same tokens. Caching and schema dedup both act on the tool-schema bucket (dedup shrinks it, then caching discounts what's left, so their savings cannot simply add). Model routing and output compression both act on the prior-search-results bucket for the same reason.
This is the single most actionable finding in this analysis: a savings estimate built by summing vendor-quoted or blog-quoted percentages for each technique in isolation will overstate what a real, stacked implementation delivers. Overlap between levers is the norm, not the exception, whenever more than one technique touches the same context region.
4. Latency follows overhead reduction, not model choice.
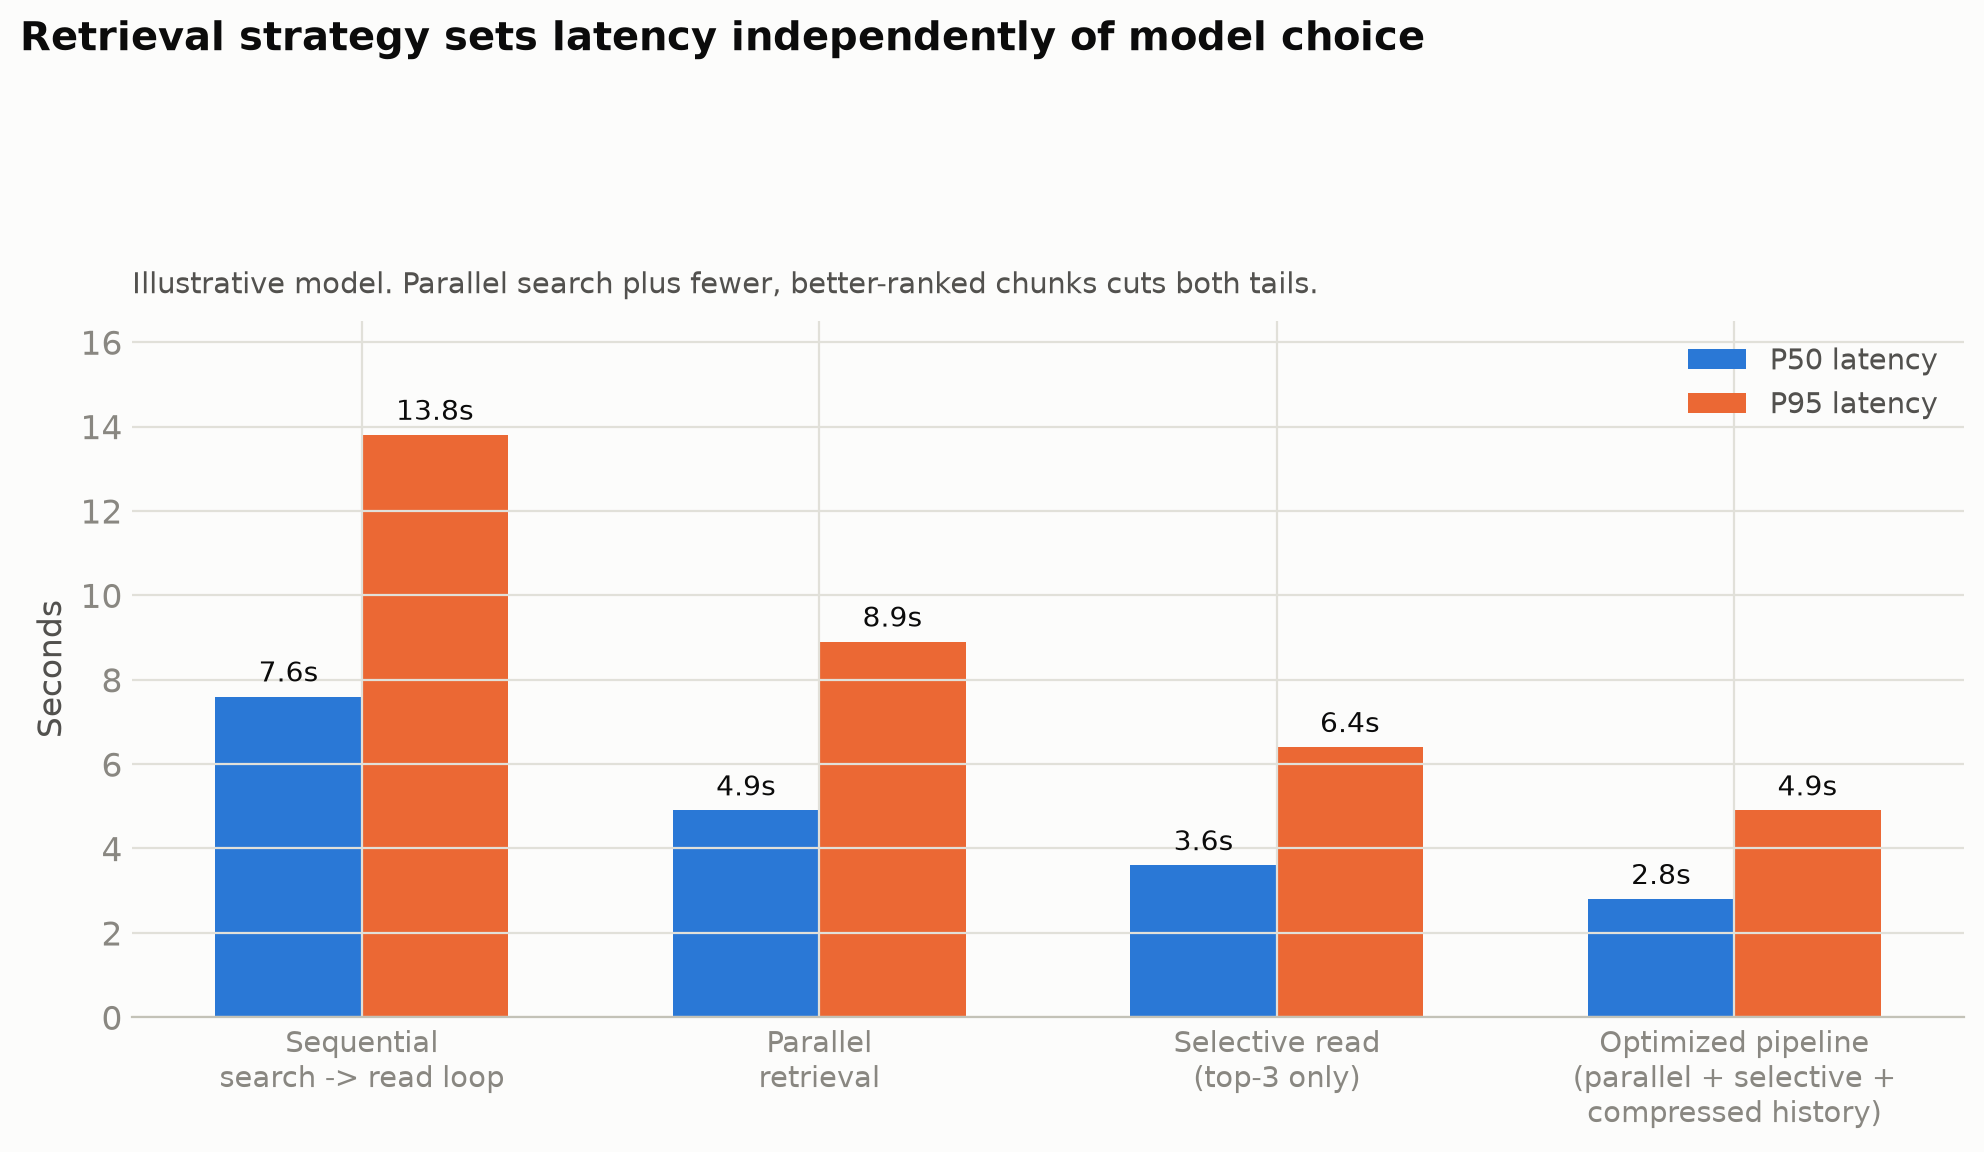
None of the four latency configurations change which model answers the request. The improvement comes entirely from how retrieval is scheduled and how much of it is read. Parallelizing search calls alone cuts P50 by 36%; adding selective reading (fetching only the top-ranked chunks in full) and compressed history on top cuts it 63% against the sequential baseline. Cost and latency move together here, not in opposite directions, because both are driven by the same overhead tokens.
5. The dangerous zone is model choice, not overhead reduction.
| Strategy | Cost/1,000 steps | Quality vs. always-Opus |
|---|---|---|
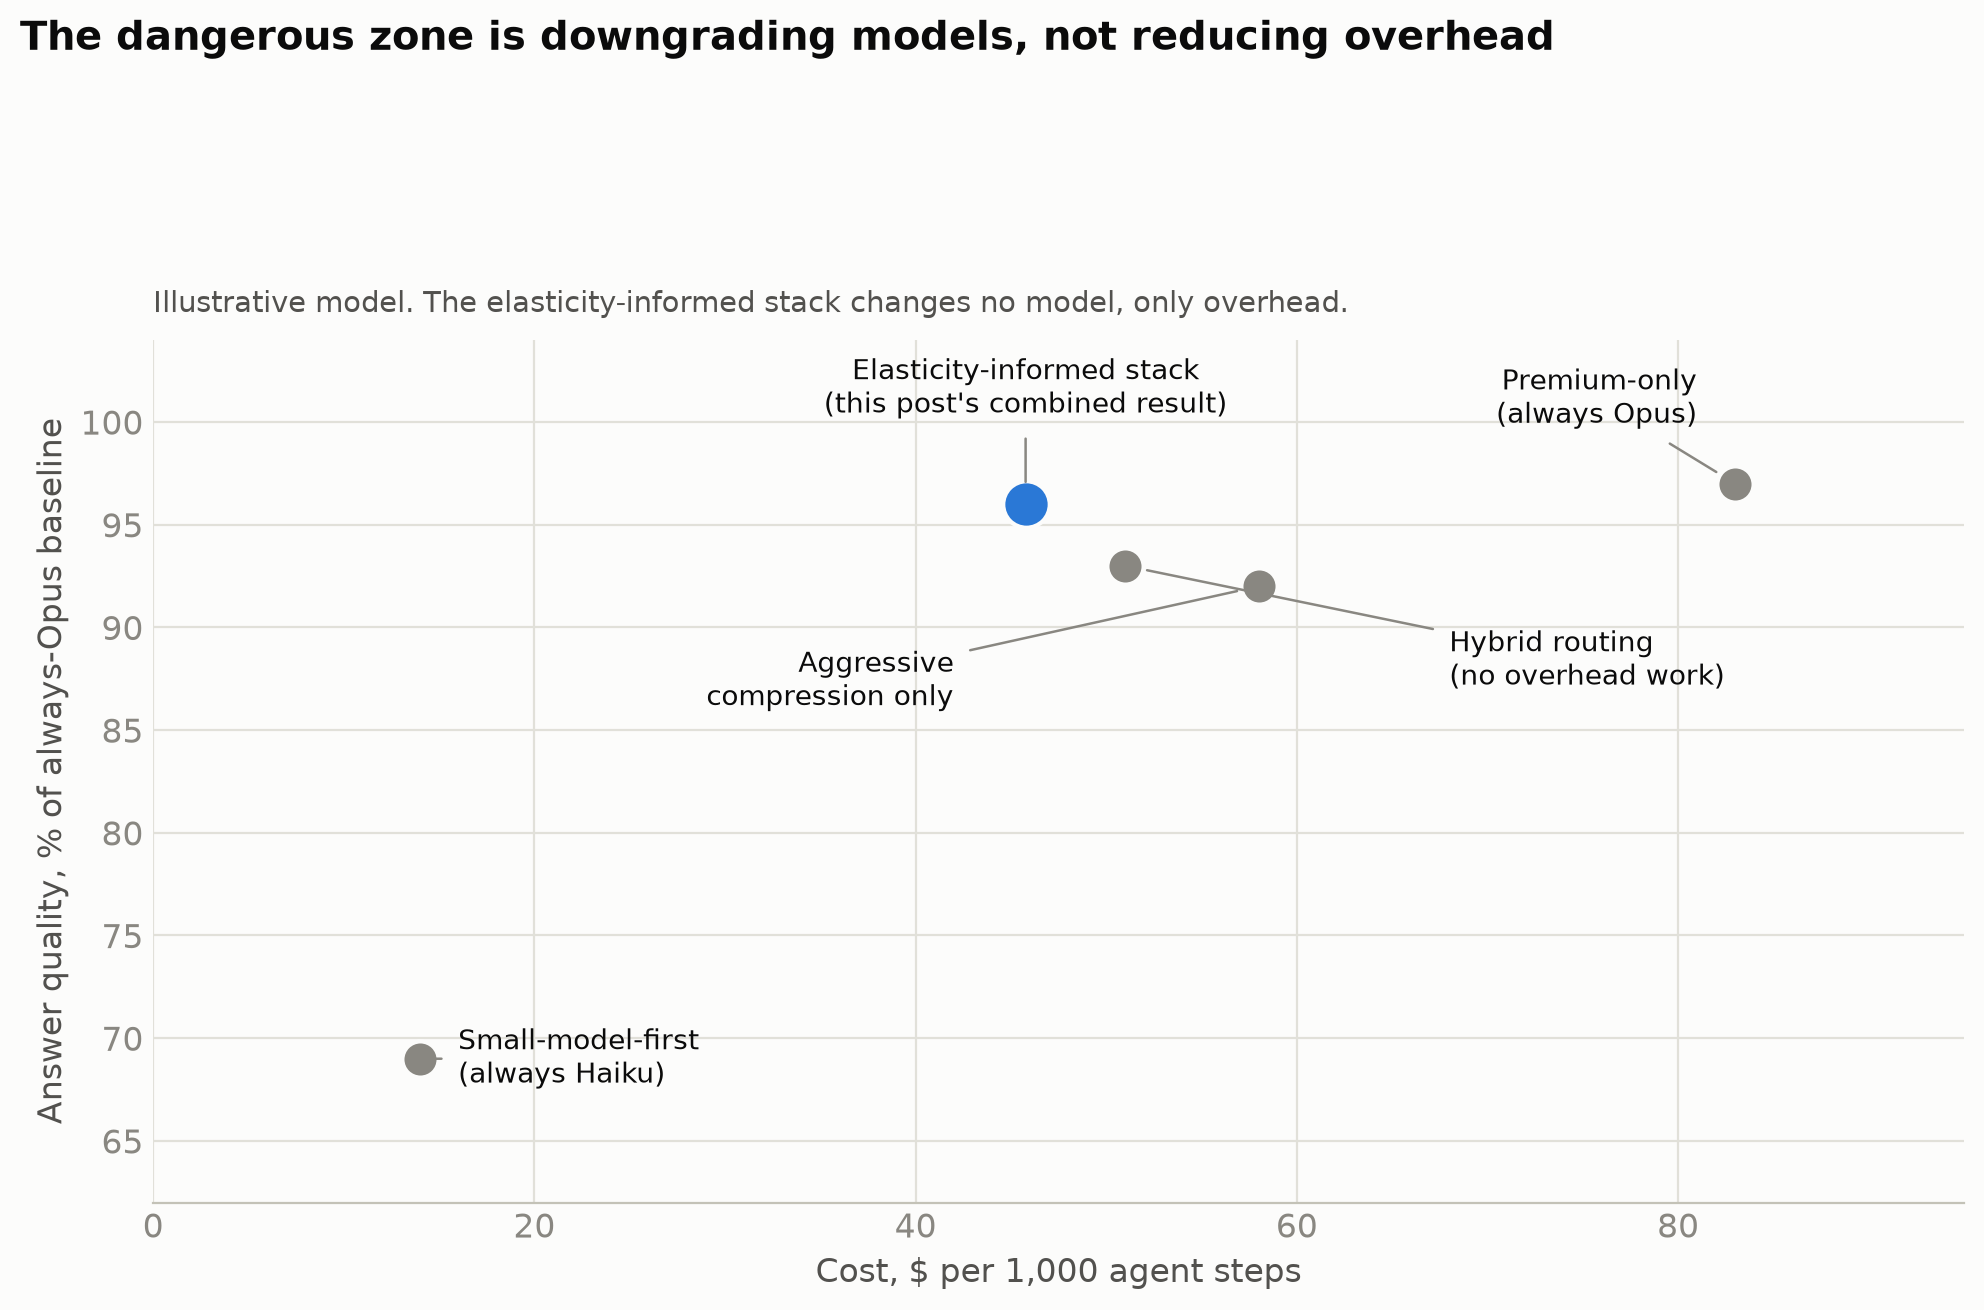
| Premium-only (always Opus) | $83.00 | 97% |
| Small-model-first (always Haiku) | $14.00 | 69% |
| Hybrid routing (no overhead work) | $51.00 | 93% |
| Aggressive compression only | $58.00 | 92% |
| Elasticity-informed stack (this post's combined result) | $45.77 | 96% |
The elasticity-informed stack, built entirely from the tornado ranking's top overhead-reduction levers and no model downgrade, lands at 96% quality for 44.9% less cost. It beats both hybrid routing and compression-only on cost and on quality simultaneously, because it never touches the model doing the reasoning. The only strategy in this set with a serious quality cliff is the one that changes the model.
6. Where the overhead tokens actually are.
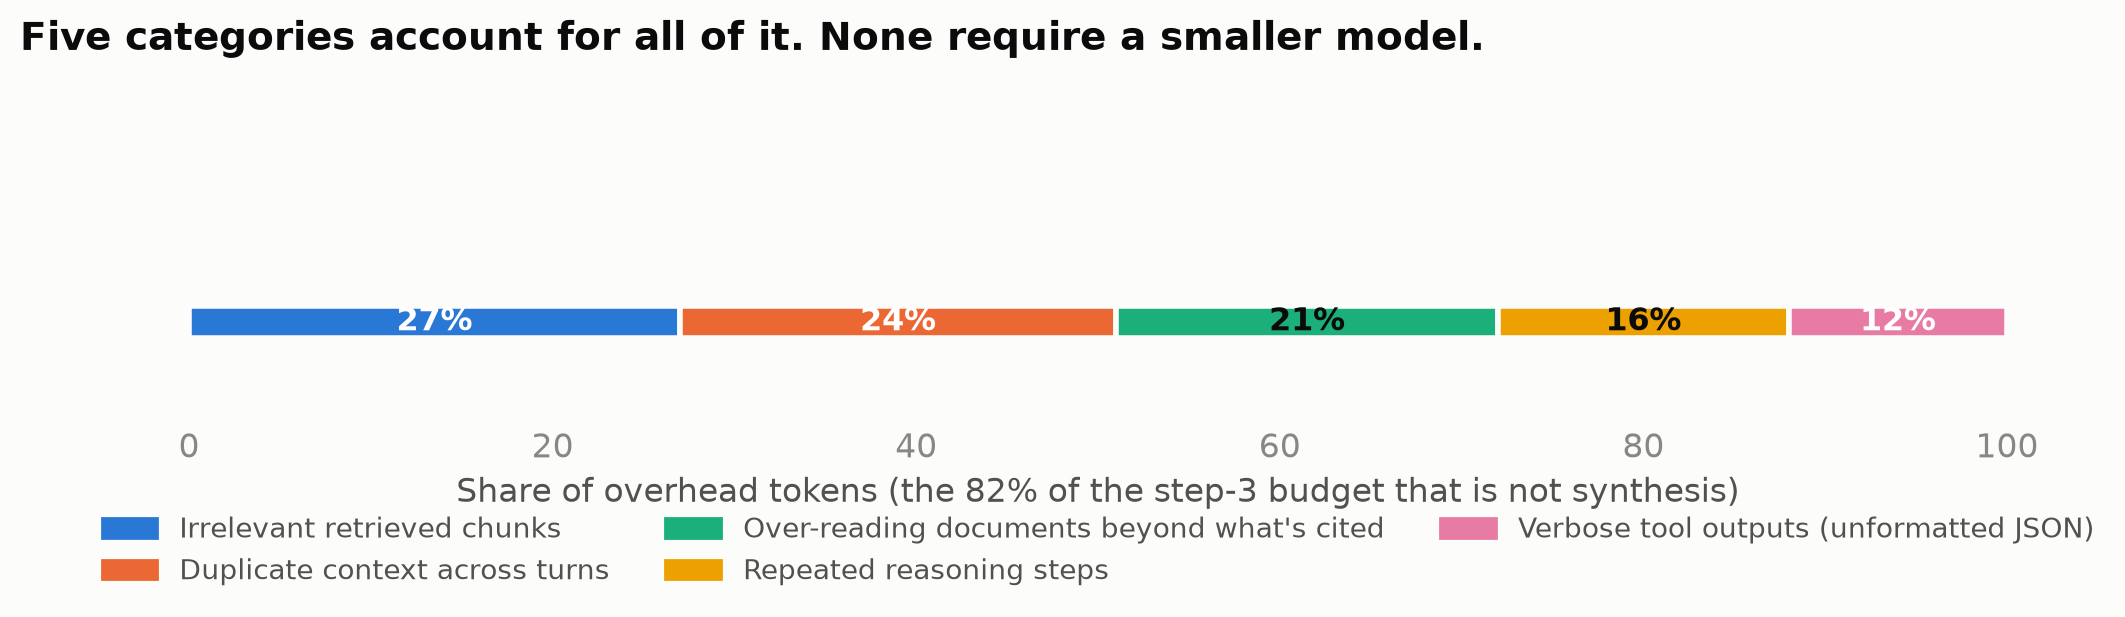
- Irrelevant retrieved chunks (27%): fetched, billed, rarely cited in the answer.
- Duplicate context across turns (24%): the same tool result or search snippet re-appearing in raw form and in a later summary.
- Over-reading documents beyond what's cited (21%): full-document reads where the model draws on a fraction of the retrieved text.
- Repeated reasoning steps (16%): re-deriving a conclusion the agent already reached earlier in the same session, because it was never carried forward as a fact.
- Verbose tool outputs (12%): unformatted JSON from search or API tools sent to the model unmodified.
None of these five categories requires a smaller model to fix. Every one of them is an overhead-management problem, which is exactly why the elasticity-informed stack in section 5 can hold quality nearly flat while cutting cost.
Discussion.
The ranking is not universal, but the method is. This blog's specific percentages come from a synthetic model with stated assumptions; a team's own workload will rank these six levers differently depending on how much of their context is genuinely repeated (which determines caching's return) versus genuinely noisy (which determines compression's return). The finding that generalizes is the method: test levers independently before committing engineering time, because intuition about which lever matters most is frequently wrong, and the sub-step routing lever that gets the most attention in vendor pitches ranked last here.
Overlap is the rule, not the edge case. Any two techniques that touch the same context region (schema handling, retrieved content, tool output) will show diminishing combined returns. Before committing to a full stack, check which buckets each lever actually modifies. Two levers on the same bucket are not additive; they are sequential, and only the second one's marginal effect on what's left is real.
Reducing overhead is safer than reducing quality. Every lever in this analysis targets overhead tokens, not the model doing the reasoning. That is why the combined result holds 96% quality. Small-model-first, the strategy that changes the model instead of the overhead, is the only one with a serious quality cliff (69%), and it is also not reliably cheaper in practice once retries are counted: a model that fails and re-tries at a higher tier costs more than the tier it should have used the first time.
Caching only pays off when the prefix repeats. The 90% discount modeled here assumes a cache hit, which requires the system prompt and tool schemas to be genuinely stable across steps and sessions. A team that regenerates its system prompt per request, or rotates tool definitions frequently, will not see this lever's ranked position hold. Elasticity analysis has to be re-run against a team's actual traffic pattern, not copied from a blog post.
Parallel retrieval can raise token load even as it cuts latency. This analysis modeled latency and token cost as if they moved together, and for the selective-read case they do. But naive parallelization, firing every possible search query at once instead of only the ones the reasoning step actually needs, can add tokens even as it cuts wall-clock time. Selective reading, not parallelism alone, is what did the cost work in section 4.
Implementation framework.
Step 1: Build the baseline bucket model. Instrument token counts (not just totals) by stage: system prompt, tool schemas, retrieved content, history, output. Anthropic's token counting API makes this a same-day change.
import anthropic
client = anthropic.Anthropic()

def bucket_costs(system: str, messages: list, tools: list,
                  model: str = "claude-opus-4-8") -> dict:
    base = client.messages.count_tokens(model=model, system=system, messages=[]).input_tokens
    with_tools = client.messages.count_tokens(model=model, system=system, messages=[], tools=tools).input_tokens
    full = client.messages.count_tokens(model=model, system=system, messages=messages, tools=tools).input_tokens
    return {
        "system_tokens": base,
        "tool_schema_tokens": with_tools - base,
        "history_and_context_tokens": full - with_tools,
        "total_input": full,
    }
Step 2: List every candidate lever and the bucket it targets. Do not skip this. A lever with no clearly-named target bucket usually means the intervention is not well understood yet.
Step 3: Test each lever independently against the unmodified baseline. Change one thing, measure the delta, revert, repeat. This produces the tornado ranking, not intuition about which lever "feels" biggest.
Step 4: Identify overlapping buckets before combining levers. Two levers on the same bucket are not additive. Order them (which one runs first) and measure the combined effect directly rather than summing.
Step 5: Implement in ranked order, re-measuring after each step. The first lever implemented should be the top of the tornado, not the one with the most existing tooling support. Re-measure the actual bucket cost after each change; do not trust the pre-computed independent estimate once two or more levers are live.
Step 6: Hold the model constant while working through overhead levers. Section 5's finding is directional: reduce overhead to its floor before touching which model answers the request. Model changes are the one lever category with a real quality cliff.
Step 7: Re-run the sensitivity test quarterly. Traffic patterns shift, cache hit rates drift, and a lever that ranked first on the day it shipped can decay as usage patterns change. Elasticity is a property of a specific workload at a specific point in time, not a fixed constant.
The product angle.
Most of what this analysis found (which lever ranks highest, where two levers overlap, when a stack stops paying off) is invisible without per-stage instrumentation. Teams without that visibility default to the lever that is easiest to talk about in a planning meeting, usually "switch to a cheaper model," which this analysis ranked last and which carries the only real quality risk in the set.
This is the kind of measurement problem a routing and observability layer is built to solve. Instead of guessing which optimization to ship first, or discovering after the fact that two levers were fighting over the same tokens, Nadir logs cost by stage on every request, so the tornado ranking above is something a team can compute from its own traffic instead of borrowing from a blog post. The routing decision itself, sending simple sub-steps to a smaller model, was the lowest-ranked lever in this analysis; it still matters, but it should not be the first ticket on the board.
Conclusion.
The future of LLM cost optimization is not a longer list of techniques. It is knowing which technique on the list to ship first, and knowing when two techniques on the list are quietly competing for the same tokens. A tornado analysis run against a team's own baseline, before a single line of optimization code ships, turns six plausible-sounding tickets into a ranked backlog. In this model, that ranking put a caching configuration flag ahead of a routing architecture, and it caught an 18% overstatement that a simple sum of vendor claims would have missed entirely.
Measure the elasticity before committing the sprint.
[See where your own agent's cost actually concentrates →](/auth?mode=signup)
All figures in this post are illustrative, computed from a synthetic step-level cost model built for this analysis, not measured from proprietary production traffic. Pricing: Claude Opus 4.8 at $5/M input, $25/M output (Anthropic, June 2026). Sources: [Anthropic Prompt Caching Documentation](https://docs.anthropic.com/en/docs/build-with-claude/prompt-caching). [Anthropic Token Counting API](https://docs.anthropic.com/en/docs/build-with-claude/token-counting). [Liu et al., "Lost in the Middle: How Language Models Use Long Contexts," arXiv:2307.03172, 2023](https://arxiv.org/abs/2307.03172). [Anthropic Claude Pricing, June 2026](https://www.anthropic.com/pricing).