The extra runway disappears tonight
On May 13, 2026, Anthropic quietly gave Claude Code users 50% more weekly usage. The stated reason was "infrastructure capacity." The real driver, by most accounts, was Codex: Claude Code reportedly consumes three to four times more tokens than OpenAI's Codex to produce comparable output, and users on identical subscription tiers were hitting Claude's rate limits while Codex users weren't. One commenter summed up the migration pressure bluntly: "I cancelled my Max plan twice over rate limits." Source: Pasquale Pillitteri, "Claude Code Weekly Limits +50%: Anthropic's Anti-Codex Move," May 2026.
The boost was supposed to expire July 13. Anthropic extended it once, to July 19, 2026 at 11:59 PM PT. Source: Help Net Security, "Claude Code weekly limits promotion extended," Jul 13, 2026. That's tonight. When it lapses, weekly limits for Pro, Max, Team, and seat-based Enterprise users drop back to their standard levels. Nothing changes about your plan or your bill, only how much room you have before the wall.
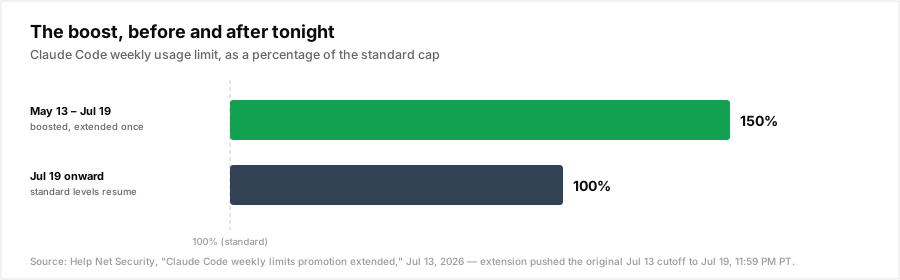
Two months of extra headroom, gone in one reset. For a lot of teams, that headroom quietly became the baseline: sessions got longer, context got sloppier, and Opus became the default model for everything because there was room to spare. Tonight there isn't.
The wall isn't one number, it's two
Here's the part that doesn't show up in Anthropic's own usage docs, which describe the limit only in general terms as a function of "conversation length and complexity, features used, and which model you're chatting with." Source: Claude Help Center, "How do usage and length limits work?". Community measurement fills in the specifics: the weekly cap is tracked as two separate meters, one for Sonnet-class usage and one for Opus-class usage, reset on the same clock but drawn down independently.
| Plan | Sonnet-hours / week | Opus-hours / week | Approx. ratio |
|---|---|---|---|
| Pro | ~40–80h | not included | — |
| Max 5x | ~140–240h | ~15–35h | ~7.6x |
| Max 20x | ~240–480h | ~24–40h | ~11x |
Source: TrueFoundry, "Claude Code Rate Limits & Usage Quotas Explained (2026)".
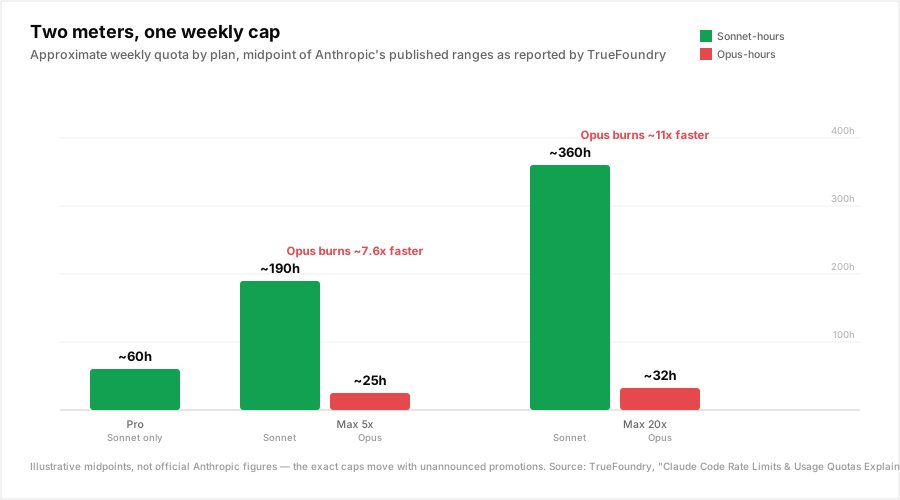
Take the midpoints and the picture is stark. On a Max 5x plan, an hour of active Opus use drains its bucket at roughly 7.6 times the rate an hour of active Sonnet use drains its own bucket. On Max 20x, the gap widens to roughly 11x. Both buckets share one weekly reset clock, but they are not fungible: running out of Opus-hours doesn't let you borrow from a fat Sonnet-hours balance sitting unused. Context size compounds this. Referencing five medium-sized files in a single turn can burn 30,000-plus tokens, "equivalent to dozens of plain prompts," and extended thinking modes multiply consumption roughly 5x on top of that. Source: TrueFoundry, "Claude Code Rate Limits & Usage Quotas Explained (2026)".
The lever nobody points at the harness
Claude Code doesn't route per call. You pick a model for the session (or manually flip it with /model), and every request in that session, whether it's "read this file" or "redesign this module's concurrency model," draws against the same bucket at the same rate. If the session default is Opus, every trivial call is billed against the smaller, faster-draining meter for a task that needed none of its reasoning depth.
This isn't a new observation about coding-agent traffic, just a new place it costs you. Datadog measured that 69% of all LLM input tokens across production traffic are repeated system prompts, tool schemas, and policy definitions, not the task-specific reasoning the expensive model was chosen for. Augment Code's routing guide for coding agents puts a number on the split directly: Sonnet-tier models match Opus-tier quality on 80-90% of coding tasks, and the remaining 10-20%, genuine multi-file architecture decisions with subtle dependencies, is where Opus-level reasoning actually earns its keep. A session that defaults everything to Opus is spending the scarce, fast-draining bucket on the 80-90% that never needed it.
The fix costs nothing and takes one keystroke: start sessions on Sonnet, and reach for /model opus only on the turns that are actually architecture-level. That single habit change makes the Opus-hours bucket, the one with no room to spare even at 150%, last through the parts of the week that actually need it.
When the wall doesn't move, it changes shape
Two different Anthropic changes get conflated here, and they're not the same wall. The weekly Sonnet-hours/Opus-hours caps in this post govern interactive Claude Code, the CLI, IDE extension, desktop, and web sessions a person is actively driving. Separately, on June 15, 2026, Anthropic moved headless and Agent SDK usage, `claude -p`, CI pipelines, scheduled agents, onto its own monthly credit pool billed at full API rates: $20 for Pro, $100 for Max 5x, $200 for Max 20x, no rollover. A team can run out of interactive weekly hours and headless credits on completely independent schedules, and both walls end the same way: once you're past either one, you're either waiting for a reset or paying per token.
That's the point where the subscription model stops mattering and the API bill starts. Configure Claude Code with an API key instead of subscription login (claude config set --global apiBaseUrl <endpoint>) and the weekly cap disappears entirely. So does the floor: every token, on every call, now has an explicit price at whatever model's rate answered it. The same imbalance that quietly drained a fixed number of Opus-hours for free now drains a real, itemized number of dollars for exactly the same trivial calls, at Opus's $5/$25 per million tokens instead of Sonnet's $3/$15, or a cheap tier's fraction of that.
The fix that survives the move to API billing
This is the seam a router sits in, and it's the same seam whether the currency is hours or dollars: match the model to the call, not to the session.
import openai

client = openai.OpenAI(
    base_url="https://api.getnadir.com/v1",   # was: https://api.anthropic.com/v1
    api_key="YOUR_NADIR_KEY",
)

response = client.chat.completions.create(
    model="auto",  # Nadir routes per call; the harness doesn't have to pick one model for the whole session
    messages=[
        {"role": "user", "content": task_prompt},
    ],
)
The integration is two lines: change the base URL, set model="auto". Complete non-streaming responses report the served model and actual cost; a configured, priced benchmark adds the avoided-spend comparison. That is the API-side equivalent of a Sonnet-hours-vs-Opus-hours breakdown, denominated in dollars.
What to actually do before the reset finishes tonight
- Check `/usage` now. It's the only source of truth for your current numbers and reset time; any specific figure in a news post, including this one, can be stale by the time you read it.
- Default new sessions to Sonnet, not Opus. Reserve the expensive bucket for turns that are genuinely architecture-level, using
/model opusdeliberately rather than leaving it as the session default. - Trim what you hand the agent. Five files pasted in full costs the same bucket as dozens of scoped prompts; a targeted diff or grep result does the job of the reasoning without the context tax.
- If the standard limit still isn't enough, that's a signal to measure, not to upgrade blindly. A bigger plan tier is a fixed cost whether or not you use the Opus-hours it grants. Moving to API billing removes the cap but turns every token into a line item, which is exactly the traffic pattern, mostly trivial calls, a few genuinely hard ones, that a router is built to cut down to size. Read the complete guide to cutting LLM API costs for the rest of the playbook, or see what happens when nobody applies it in Uber's four-month AI budget burn.
Anthropic's boost was a subsidy, not a fix, and subsidies expire. The underlying ratio, most calls in a coding-agent session don't need the model that made you buy the plan in the first place, doesn't. Start free and let Nadir apply that ratio automatically, on the traffic that's about to start costing you by the token instead of by the hour.