The cheapest model in your routing table just sent a warning shot.
On August 6, 2026, Bloomberg reported that DeepSeek plans a "significant" price increase across its AI services. The company did not publish a number. It published a warning: plan accordingly. DeepSeek V4 Flash currently prices at $0.14 per million input tokens and $0.28 per million output tokens, against $3.00 and $15.00 for Moonshot's Kimi K3, and $10.00 and $50.00 for Anthropic's Fable 5. For two years, that gap was the whole pitch. DeepSeek was not a budget alternative to frontier models. It was the floor the rest of the market got measured against.
In May 2026, when DeepSeek V4 shipped, the standard cost-optimization advice, including a piece we wrote ourselves, was to route simple traffic to it and bank roughly 85% off output tokens compared to Opus-class pricing. Teams did exactly that. Cascade thresholds got written. Rule-based routers got a new if cheap: use deepseek-v4-flash branch. Cost dashboards got rebuilt around the new baseline.
Three months later, that baseline moved, and most of those systems have no way to know it happened until the invoice arrives.
Why the floor moved
DeepSeek has not said why, beyond calling the increase substantial. The likeliest driver reported alongside the announcement is infrastructure: DeepSeek has plans for a large data center buildout in Inner Mongolia, and subsidized inference at $0.14 per million input tokens does not fund that on its own. Whatever the reason, the mechanism is the one every provider eventually reaches. A price that undercuts the market by 10 to 100x is either temporary, subsidized by someone else's capital, or both. DeepSeek's pricing was never a law of physics. It was a competitive strategy with a shelf life, and the shelf life just got shorter.
This is not a DeepSeek problem specifically. It is what "the cheapest model that can handle it" actually means: a moving target, re-evaluated against whatever every provider charges today, not what they charged when you last read their pricing page.
The routing table nobody revisits
Here is the pattern that breaks. A team benchmarks providers once, picks a cheap-tier model, and encodes the decision directly into application code or a config file that ships once and gets forgotten:
# routing_config.py, last touched May 2026
PRICE_PER_MILLION = {
    "deepseek-v4-flash": {"input": 0.14, "output": 0.28},
    "claude-sonnet-5": {"input": 3.00, "output": 15.00},
    "claude-opus-5": {"input": 10.00, "output": 50.00},
}

def pick_model(complexity_score):
    if complexity_score < 0.3:
        return "deepseek-v4-flash"
    elif complexity_score < 0.7:
        return "claude-sonnet-5"
    return "claude-opus-5"
Nothing about this code is unreasonable on the day it is written. The problem is what happens on day 92, when DeepSeek reprices and PRICE_PER_MILLION["deepseek-v4-flash"] silently stops matching reality. The routing logic keeps running. The classifier keeps sending 60% of traffic to the cheap tier, exactly as designed. The savings dashboard, if it exists, keeps reporting last quarter's math. Nobody's code broke. The assumption baked into the code broke, and nothing in this system is built to notice.
Three places that assumption usually hides:
- A hardcoded price table, like the one above, that gets written once during a cost audit and referenced by routing logic indefinitely.
- A cascade confidence threshold tuned against a specific cost ratio between tiers. When the ratio changes, the threshold optimizes for the wrong tradeoff without anyone changing a line of code.
- A savings dashboard or ROI claim built on a snapshot of provider pricing, quietly wrong the moment any one input in that snapshot moves.
None of these fail loudly. They fail as a gap between what the system reports and what the invoice says, discovered whenever someone happens to compare the two.
The gap that made this the story
The reason a DeepSeek price change is newsworthy at all is the size of the gap it is closing. Here is where the budget tier sits on output pricing as of this week:
| Model | Output ($/M tokens) | vs. DeepSeek V4 Flash |
|---|---|---|
| DeepSeek V4 Flash | $0.28 | baseline |
| Grok 4.1 Fast | $0.50 | 1.8x |
| Mistral Small 4 | $0.60 | 2.1x |
| Gemini 3 Flash | $3.00 | 10.7x |
| Moonshot Kimi K3 | $15.00 | 53.6x |
| Anthropic Fable 5 | $10.00 / $50.00 | 35.7 - 178.6x |
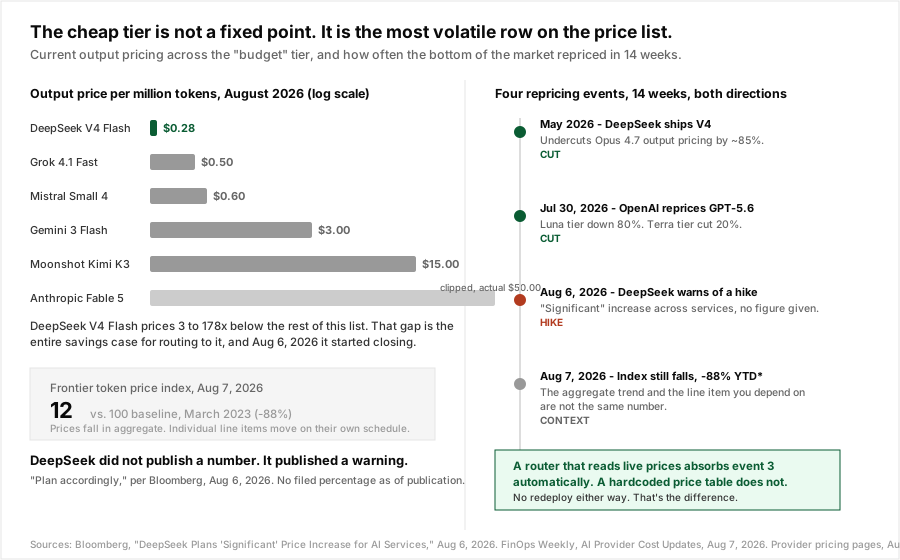
A router that treats this table as static has been quietly overstating its own value since the day it was written. A gap of 178x between the cheapest and most expensive model on this list is exactly the kind of number that makes routing look obviously worth doing. It is also exactly the kind of number that changes the moment one row on the list reprices, which is precisely what just happened.
Volatility runs in both directions
It would be a simpler story if provider pricing only moved down. It does not. In the same 14-week window, three separate repricing events hit the budget and mid tiers, two cuts and one hike:
- May 2026: DeepSeek ships V4, undercutting frontier output pricing by roughly 85%.
- July 30, 2026: OpenAI cuts GPT-5.6 Luna-tier pricing 80% and Terra-tier pricing 20%.
- August 6, 2026: DeepSeek warns of a significant increase, with no figure attached.
Zoom out and the frontier token price index sat at 12 on August 7, 2026, down 88% from its March 2023 baseline of 100. That aggregate trend is real and it is the reason routing keeps paying off in general. But an aggregate index falling does not mean every line item in your routing table is falling with it. The model you picked as your cheap tier in May can be the model that gets more expensive in August, in the same market where the average is still getting cheaper. Betting your architecture on any single provider staying cheap is a bet on that provider's competitive strategy, not on a trend in your favor.
Three questions for your routing setup
If you have not looked at this in a while, three questions surface whether your system would catch the next DeepSeek-shaped event before your invoice does:
- Is your model-to-price mapping hardcoded, or does it read from something live? If updating a price means a pull request and a deploy, you have a lag between when a provider reprices and when your system knows it. That lag is where the silent overspend lives.
- Would you find out about a price change from an alert, or from the bill? Most teams do not monitor provider pricing pages. The invoice becomes the monitoring system by default, which means the earliest possible detection is 30 days after the fact.
- Does the cheap tier changing require a redeploy, or does the system reroute on its own? A router that re-evaluates cost against current provider rates on every request, rather than against a snapshot taken during a cost audit, absorbs a repricing event as a routing shift instead of a production incident.
None of these require abandoning DeepSeek, or any other provider that reprices. They require not treating today's cheapest option as a permanent architectural decision.
Where Nadir fits
Nadir's classifier evaluates each prompt against current provider pricing and a quality floor you set per API key, not against a table someone wrote down during last quarter's cost review. When a provider reprices, whether that is DeepSeek raising rates or OpenAI cutting them, the routing decision shifts on the next request. No pull request, no redeploy, no gap between the announcement and the fix.
The integration is two lines: change the base URL, set model="auto". When a priced benchmark comparison is available, the response includes the nadir_metadata.benchmark_comparison.savings_usd field, so when a provider's pricing moves, you see it in your own metrics before you see it on the invoice.
Conclusion
DeepSeek has not said what the new prices will be. That is beside the point. The lesson is not "stop using DeepSeek." The lesson is that whichever model sits at the bottom of your routing table today got there through a competitive strategy that has a shelf life, exactly like every other line on that table. A cost architecture built on a snapshot of today's cheapest option is already stale. One built on live pricing just absorbs the next announcement, from any provider, without becoming a fire drill.
Related reading
- DeepSeek V4 just widened the frontier price gap to 7x
- Your router is fighting your prompt cache
- Three providers, same 72 hours
- The real monthly bill: self-host vs. managed vs. frontier
Sources: [Bloomberg, "DeepSeek Plans 'Significant' Price Increase for AI Services"](https://www.bloomberg.com/news/articles/2026-08-06/deepseek-plans-significant-price-increase-for-its-ai-services) (Aug 6, 2026). [Bloomberg, "DeepSeek's Plan to Raise Prices Have a Whole Industry Watching"](https://www.bloomberg.com/news/newsletters/2026-08-07/deepseek-s-plan-to-raise-prices-have-a-whole-industry-watching) (Aug 7, 2026). [Dataconomy, "DeepSeek Warns Developers Of Significant API Price Increases"](https://dataconomy.com/2026/08/06/deepseek-significant-api-price-increase-2026/) (Aug 6, 2026). FinOps Weekly, "AI Provider Cost Updates," Aug 7, 2026. Provider pricing pages for DeepSeek, xAI, Mistral, Google, Moonshot, and Anthropic, accessed August 2026.