A model that can't write a sentence
On September 15, TypeSafe AI opened early access to Jev, and the most interesting thing about it is what it can't do. Jev doesn't generate text. You send it some state (a ticket, a tool call, a document) and a set of questions, and it returns typed answers: a probability that a statement is true, a pick from a fixed list of options, or a score on a defined scale, each with a confidence number. TypeSafe calls this a "System One" model, after Daniel Kahneman's fast, intuitive System 1, and calls the category decision models. Source: Wikipedia, Jev (AI model))
The name is a nod to William Stanley Jevons, the economist behind the Jevons paradox this blog has written about: make a resource cheaper and people use more of it in total. It fits. Jev's pitch is that many LLM calls aren't requests for text at all. They're decisions wearing a chat interface, billed at chat prices.
TypeSafe claims Jev is 40-400x cheaper and 40-200x faster than frontier LLMs on comparable tasks, with peaks of 444.6x and 193.6x on its own workflows. It also says, to its credit, that its own team wrote those workflows, that the results may be biased, and that real-world gains are "likely to sit at the high end". This post checks the cost claim against September 2026 list prices and then looks at the more useful question: which of your LLM calls are decisions, and what should answer them?
What Jev actually is
| Released | September 15, 2026, limited early access (waitlist) |
| Company | TypeSafe AI, San Francisco. CEO Diogo Almeida, previously at OpenAI on RLHF, InstructGPT and ChatGPT. $40M seed led by DCVC |
| Input | A state (text, arrays or name-value pairs) plus one or more questions, evaluated in parallel |
| Output | Typed values only: noul (yes/no probability), choice (option + per-option probabilities + confidence), score (level + per-level probabilities + confidence) |
| Price | $0.042 per million input tokens. Output is not billed |
| Latency | 70-500 ms end to end, per TypeSafe |
| Training | Reinforcement learning for calibrated decisions, on synthetic data. Weights, architecture and paper unpublished |
Sources: Wikipedia), Simon Willison, DataCamp.
A request, following TypeSafe's early-access API as shown in DataCamp's guide:
import requests

resp = requests.post(
    "https://api.typesafe.ai/v1/systemone",
    headers={"Authorization": "Bearer YOUR_KEY"},
    json={
        "model": "jev-latest",
        "state": "Customer emailed twice this week about a failed refund...",
        "questions": {
            "category": {"type": "choice", "options": ["billing", "technical", "sales"]},
            "urgency": {"type": "score", "min": 0, "max": 100},
        },
    },
)
print(resp.json())
A yes/no question comes back as a bare probability, for example {"is_urgent": {"type": "noul", "noul": 0.999}} in LangChain's harness walkthrough. No prose to parse and no JSON to repair. Every answer is a valid value by construction.
Checking the cost claim against this week's prices
Take one decision: a 2,000-token input (a support ticket plus a short instruction) and one yes/no answer. The comparison depends on how the LLM answers:
- With reasoning switched off, it answers in about 10 output tokens.
- With reasoning on, which is the default on most current models, it spends a few hundred hidden reasoning tokens first. Those are billed as output. This post assumes 400.
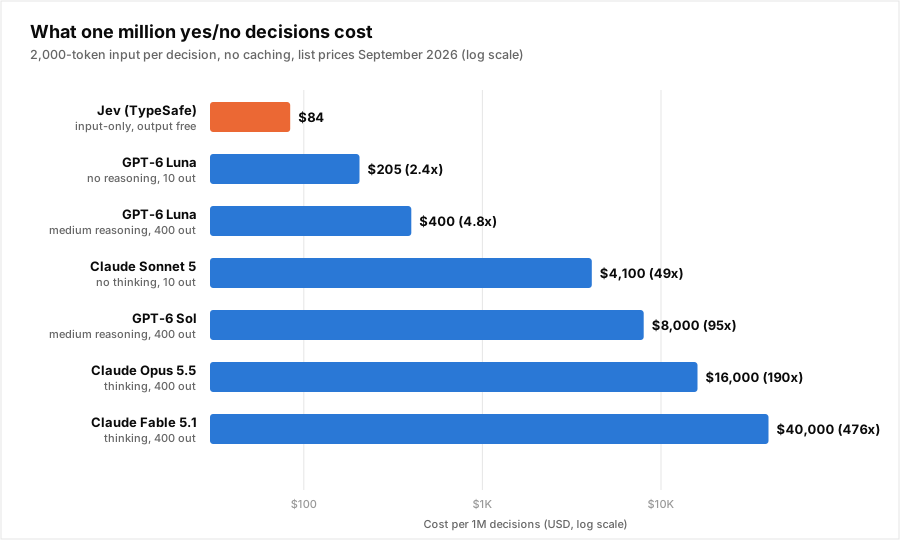
| Model and mode | Cost per 1M decisions | vs Jev |
|---|---|---|
| Jev | $84 | 1x |
| GPT-6 Luna, no reasoning | $205 | 2.4x |
| GPT-6 Luna, medium reasoning | $400 | 4.8x |
| Claude Sonnet 5, no thinking | $4,100 | 49x |
| GPT-6 Sol, medium reasoning | $8,000 | 95x |
| Claude Opus 5.5, thinking | $16,000 | 190x |
| Claude Fable 5.1, thinking | $40,000 | 476x |
List prices, no caching, 2,000 input tokens, 10 output tokens without reasoning and 400 with. GPT-6 Luna's price is from OpenAI's model page, Anthropic's from its pricing page.
Two readings, both true:
- Against a frontier model with thinking on, TypeSafe's headline holds up. Fable 5.1 at 476x is in the same range as the claimed 444.6x peak. If your pipeline sends yes/no questions to a flagship model with reasoning on, and plenty do by default, the claim describes your bill.
- Against the cheapest current LLM with reasoning off, the gap is 2.4x. GPT-6 Luna launched on September 22 at $0.10 per million input tokens. Anyone reading "400x cheaper" as the saving against a well-configured small model will be disappointed.
So the price argument for Jev is mostly a price argument against bad defaults: a frontier model and a thinking budget on a question with three possible answers. You can fix a lot of that today with the models you already use.
What it buys besides price
If Jev were only 2.4x cheaper than Luna, it wouldn't be worth a new vendor. The case rests on three other things:
- Latency. 70-500 ms against seconds for a reasoning model. In DataCamp's summary of TypeSafe's benchmark, GPT-5.6 Terra averaged 10.1 s and Claude Opus 5 37.8 s. For a check that runs before every tool call, that's the difference between invisible and a noticeably slower agent.
- Probabilities you can threshold. An LLM answers "yes". Jev answers 0.93. A decision with a number attached can be gated: act above a threshold, escalate below it. Whether those numbers are calibrated, so that 0.9 really means right 90% of the time, is the claim that needs independent checking. Confident but wrong is the failure mode that sinks routers.
- No format errors. TypeSafe reports a 0% structured-output error rate by construction, against 0.58% for GPT-5.6 Luna and 5.73% for Opus 5 on its own evaluation. At a million calls a day, 0.58% is 5,800 retries or silent failures. Structured output has its own token cost, and a decision model doesn't pay it.
And the fine print that matters most: on TypeSafe's four-workflow benchmark (security, observability, invoicing, customer service), Jev agreed with the reference answers 67.8% of the time. GPT-5.6 Terra scored 67.9% and Claude Opus 5 73.1%. Source: DataCamp So Jev roughly matches a mid-tier LLM, trails a frontier one by about 5 points, and does it in a fraction of the time and cost. That's a useful result, and it's also the result that argues for a cascade rather than a replacement.
The pattern: decide cheaply, escalate the uncertain tail
The architecture that makes sense of these numbers isn't "replace the LLM". It's "put a decision layer in front of it":
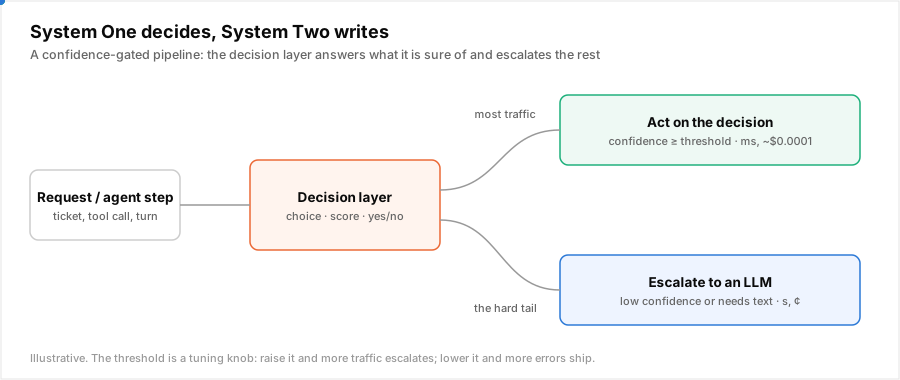
The gate is only a few lines. Here's the idea with any decision backend that returns a probability, whether Jev, a classifier you trained, or a small LLM asked for logprobs:
def gated_decision(state: str, question: str, decide, escalate,
                   hi: float = 0.9, lo: float = 0.1):
    """Act on confident answers, escalate the uncertain middle to an LLM.

    decide(state, question)   -> P(yes), fast and cheap
    escalate(state, question) -> bool, slow and expensive (an LLM)
    """
    p = decide(state, question)
    if p >= hi:
        return True, "decided", p
    if p <= lo:
        return False, "decided", p
    return escalate(state, question), "escalated", p
Two numbers decide whether this pays off: the escalation rate (the share of traffic landing between lo and hi) and the error rate among confident answers. Sweep the thresholds on a labeled sample before you ship. We've walked through that sweep for a router's confidence cutoff, and it carries over unchanged. With a 15% escalation rate to Sonnet 5 without thinking, the blended cost in the example above is about $84 + 0.15 × $4,100 ≈ $700 per million decisions. That's 83% below sending everything to Sonnet 5, and quality on the escalated tail matches Sonnet's, because Sonnet answers it.
Audit your pipeline for decisions in disguise
Most production LLM stacks contain more decision calls than their owners realize. Look through your logs for prompts that end in one of these shapes:
| Call | Shape | Usually sent to |
|---|---|---|
| Ticket or intent triage | choice | the app's main model |
| Guardrail or policy check | yes/no | a second full LLM call |
| Tool-call approval ("is this command risky?") | yes/no | the agent's own model |
| "Is the task done?" loop check | yes/no | the agent's own model, every turn |
| Search reranking | score per candidate | a mid-tier model |
| Which model should answer this? | choice | a router |
A quick test: if the output would fit in an enum and your code throws away everything except that enum, it's a decision call. Tag them, count them, and multiply by what they cost today. On agent loops, where "is it done?" and "is this safe?" fire every turn, it's common for decision calls to be a large share of requests while being a small share of tokens. They're cheap individually and add up in aggregate.
The decision we make on every request
The last row of that table is our business. A model router is a System One model in exactly TypeSafe's sense: text in, a typed decision out, needing to be fast and cheap enough to sit in front of every request without changing the bill it's meant to cut. We've priced that overhead before: the classifier hop is the cheapest part of routing.
Nadir's /v1/bucket endpoint has the same shape as a Jev choice question. You send a prompt and get back a tier with the full probability distribution and a confidence score, so you can act on it or escalate it:
curl https://api.getnadir.com/v1/bucket \
  -H "X-API-Key: $NADIR_API_KEY" \
  -d '{"prompt": "Is this email a refund request? Answer yes or no."}'
An illustrative response, trimmed to the decision fields:
{
  "bucket": "simple",
  "bucket_index": 1,
  "confidence": 0.94,
  "probabilities": {"simple": 0.94, "medium": 0.05, "complex": 0.01}
}
A yes/no question like that one should land in the simple tier, and that's the point: the router's job is to stop sending decision-shaped prompts to generation-priced models. Whether the simple tier is served by a small LLM with reasoning off or by a decision model like Jev is a choice about which model sits behind the tier. The routing decision in front of it is the same.
Caveats before you rebuild anything
- Early access only. Waitlist-gated, proprietary, with no published weights, architecture or paper. No large-scale independent reproduction of the benchmark has appeared yet.
- Bounded answers only. Jev needs the space of valid answers defined up front. It can't write the refund email, only decide that one is needed.
- No explanation. You get a probability, not a reason. That can fail an audit that requires written justification, and as Simon Willison points out, a bare number can hide systematic bias. The upside of cheap calls is that bias testing is cheap too.
- Known weak spots. TypeSafe's own guidance flags numbers, dates and adversarial content.
- Benchmarks from the vendor. The four workflows were written by TypeSafe, with reference answers from OpenAI and Anthropic models.
Checklist
- Find your decision calls. Anything whose useful output fits in an enum.
- Turn reasoning off on the easy ones today. On the table above, dropping from a thinking flagship to GPT-6 Luna with reasoning off captures most of the saving before any new vendor is involved.
- Pick a decision backend that returns probabilities. Jev, a trained classifier, or an LLM with logprobs. You need a number to gate on.
- Sweep the thresholds on labeled data. Choose
hiandlofrom the cost/quality curve, not from intuition. - Escalate the middle, and log it. The escalated share is the number to watch as traffic drifts.
The most expensive yes in production is the one a frontier model thought about for 400 tokens. Route decisions to something built for decisions and keep the LLMs for the tasks that need text. Start free to put a routing decision in front of every request, or read the complete guide to cutting LLM API costs.