Abstract.
It's budget season. Finance teams are building 2027 plans right now, and for a lot of companies the AI line is the first one nobody can break down. Salesforce's CEO said on the All-In podcast in May that the company is on track to spend $300 million on Anthropic tokens this year, mostly on coding. Most companies are nowhere near that number, but they share the same problem at a smaller scale: the provider invoice says which model spent the money, not which team, feature, or customer did. This post is a hands-on tutorial for fixing that. It models a $240,000-a-month LLM bill across five teams, shows how much of it one-key-per-team attribution leaves unexplained (37%), shows how badly a headcount split misprices it (a customer-facing feature's cost of goods understated 5.2x), and walks through a five-rung path from request tags to real chargeback. It covers the three traps that make LLM chargeback harder than cloud chargeback: shared prompt-cache prefixes, the "requested vs. served" cost question, and tag cardinality. Code included for OpenAI-compatible clients, coding agents, and the SQL rollup.
All company figures in this post are illustrative, modeled for this tutorial, not taken from a customer. Survey and news figures are cited inline. Methodology below.
Why this is the week to do it.
Three things landed in 2026 that turn LLM cost allocation from a nice-to-have into a planning requirement.
- The bills got big enough to argue about. The 2025 State of AI Cost Governance report from Mavvrik and Benchmarkit surveyed 372 companies: 84% reported more than 6 points of gross margin erosion from AI costs, and 80% missed their AI infrastructure forecasts by more than 25%. You can't forecast a line you can't decompose.
- FinOps made it official. At FinOps X in June, the FinOps Foundation launched FOCUS 1.4 with AI token economics on the agenda, and its own data engineering lead named the hard part: per-user, per-session, per-request token data has far higher cardinality than anything cloud billing ever had to group by. The spec is moving; your provider's invoice isn't, yet.
- 98% of FinOps teams now own AI spend. We covered the State of FinOps visibility gap earlier this year. Owning a number you can't attribute is the worst of both worlds: accountable, but blind.
The good news is that attribution for LLM traffic is easier than for cloud infrastructure, not harder, as long as you do it at the request, not the invoice.
Showback vs. chargeback, in one table.
| Showback | Chargeback | |
|---|---|---|
| What happens | Each team sees what it spent | Each team's budget is debited |
| Money moves? | No | Yes |
| Needs | Tags on every request | Tags you'd defend in a budget dispute |
| Failure mode | Report nobody reads | Teams game the allocation rule |
| When to start | Now | After two clean months of showback |
The mistake we see most often is jumping straight from "we have a total" to "we have a cap." That's how you get a spending cap that nobody can explain: it throttles the whole company because it can't tell which team caused the overage.
Methodology.
We model a 400-person software company with a $240,000 monthly LLM bill across two providers and five spending teams. Every number below comes from this model.
| Parameter | Value |
|---|---|
| Monthly LLM bill | $240,000 |
| Headcount | Engineering 240, Support 80, Sales 40, Product 20, Data 20 |
| Consumers | Coding agents, evals and CI (Engineering); customer-facing AI search (Product); agent copilot (Support); batch enrichment (Data); email drafting (Sales) |
| API keys | One per team, plus a shared "prod" key used by three services and a shared CI key |
| Tagged actuals | Engineering $108,000, Product $62,400, Support $38,400, Data $21,600, Sales $9,600 |
Step zero: see how much you can't explain.
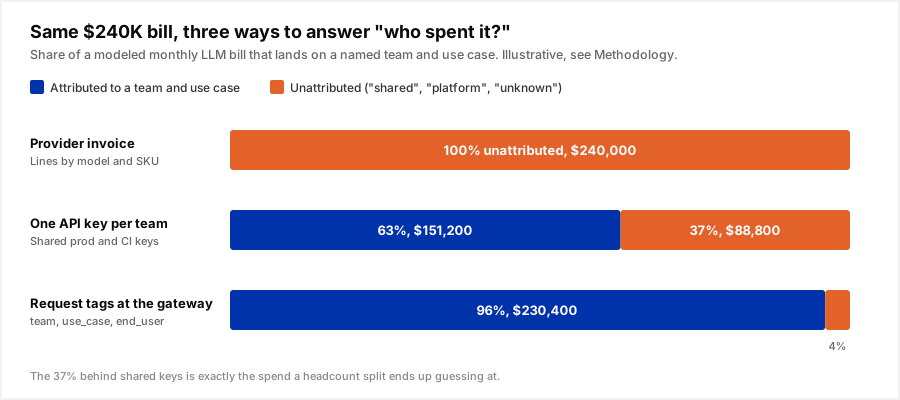
The invoice answers "which model," which is the least useful question for a budget owner. One key per team gets you most of the way, and it's where most companies stop. The problem is the last 37%. Shared keys exist for good reasons: a production service that fronts three features, a CI pipeline that runs every team's evals, a platform agent that everyone calls. That shared spend is also the fastest-growing part of the bill in most companies, because it's where agents live.
Tagging at the request level closes the gap to a residual that's small enough to amortize honestly. In our model, 4% stays untagged: legacy scripts and a notebook or two.
Why a headcount split is worse than no split.
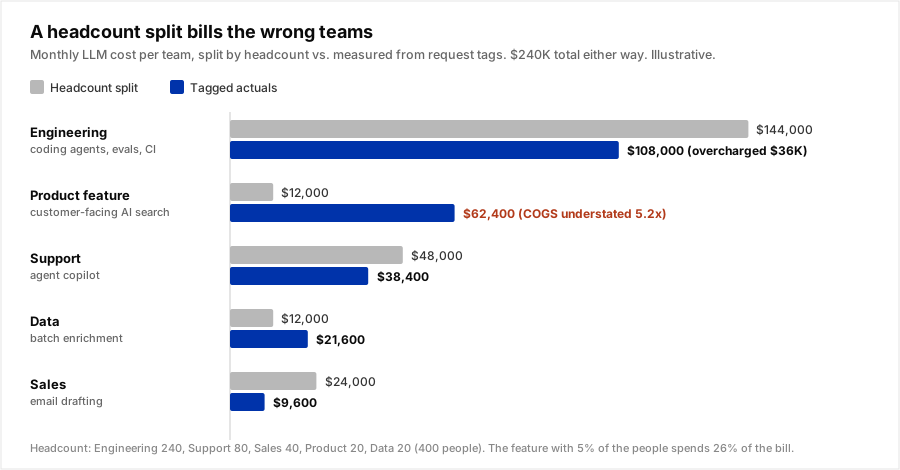
When the unexplained share is large, finance falls back on a proxy, usually headcount. It feels fair. It's badly wrong for LLM spend, because the biggest consumers are often not people at all.
In our model, the Product team has 5% of the headcount and spends 26% of the bill, because its spend is a customer-facing feature, not employee productivity. A headcount split charges it $12,000. The real number is $62,400. That's not an internal accounting quibble: that $50,400 a month is cost of goods sold that's sitting in R&D opex, which means the feature's gross margin looks better than it is, and pricing decisions get made on the wrong number. This is exactly the margin erosion the Mavvrik survey is counting.
Meanwhile Sales gets billed 2.5x what it spent and starts asking whether its email drafting tool is worth keeping. The allocation rule is creating the wrong incentives on both ends.
The five rungs.
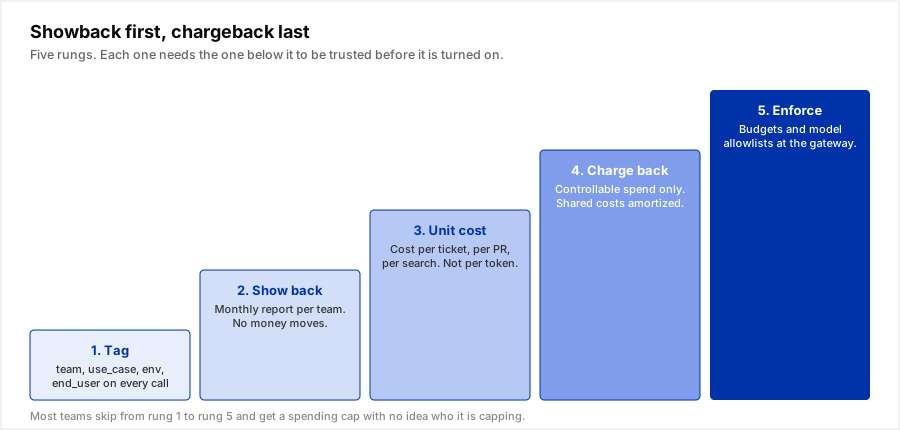
Rung 1: tag every request, at the gateway.
Pick a small taxonomy and make it mandatory. Four keys cover almost every allocation question:
team: who owns the budgetuse_case: what the call is for (support-copilot,ai-search,pr-review)env:prod,staging,ciend_user: a pseudonymous id for the customer or employee the call serves. Never an email.
Keep the value space small. Tags end up in a GROUP BY, so the cost of a sloppy taxonomy isn't bytes, it's cardinality: a use_case that sometimes holds a free-text prompt summary will blow up every dashboard that touches it. Nadir bounds tracking tags to 10 labels of 200 characters per request for exactly this reason, and drops extras rather than failing the call. An attribution label should never be able to break the request it labels.
Tag at the client you control, or at a gateway if you don't. For an OpenAI-compatible service, set the headers once on the client, not per call:
from openai import OpenAI

# One client per service. The tags ride on every request it makes.
client = OpenAI(
    base_url="https://api.getnadir.com/v1",
    api_key=NADIR_API_KEY,
    default_headers={
        "X-Nadir-Use-Case": "ai-search",
        "X-Nadir-Tags": "team:product,env:prod",
    },
)

def answer(query: str, customer_id: str) -> str:
    resp = client.chat.completions.create(
        model="auto",
        messages=[{"role": "user", "content": query}],
        # Per-request: which customer this call served. Pseudonymous id only.
        extra_headers={"X-Nadir-End-User": customer_id},
    )
    return resp.choices[0].message.content
Coding agents are the hard case, because you don't own the request body they send. Headers are the only carrier. Claude Code reads extra headers from an environment variable, so a team can tag every call its agents make without touching code:
# In the team's shared shell profile or devcontainer
export ANTHROPIC_BASE_URL="https://api.getnadir.com"
export ANTHROPIC_CUSTOM_HEADERS="X-Nadir-Use-Case: coding-agent
X-Nadir-Tags: team:platform,env:dev"
If you already emit OpenTelemetry, the GenAI semantic conventions give you gen_ai.request.model, gen_ai.usage.input_tokens, and gen_ai.usage.output_tokens on each span. Put your team and use-case tags on the same span and your traces become a second, independent source for the reconciliation in rung 2.
Rung 2: show back, and reconcile to the invoice.
Run showback for two full billing cycles before any money moves. The report is simple. The discipline is the reconciliation: tagged spend plus the untagged bucket must equal the provider invoice to within a rounding error. If it doesn't, you have a leak (a key nobody tagged, a batch job billed on a different SKU, a provider fee) and the report isn't ready to charge anyone.
-- Monthly showback over your own request log (one row per LLM call):
-- tagged spend by team and use case, plus an explicit untagged row
-- so the total ties to the invoice.
select
  coalesce(tags->>'team', 'UNTAGGED')      as team,
  coalesce(use_case, 'UNTAGGED')           as use_case,
  count(*)                                 as requests,
  round(sum(cost_usd)::numeric, 2)         as served_cost_usd,
  round(sum(requested_cost_usd)::numeric, 2) as requested_model_cost_usd
from llm_requests
where created_at >= date_trunc('month', now() - interval '1 month')
  and created_at <  date_trunc('month', now())
group by 1, 2
order by served_cost_usd desc;
Make the UNTAGGED row a first-class line with an owner, usually the platform team, and a target. If it's above 5%, fix tagging before you do anything else.
Rung 3: turn tokens into units the business understands.
Per-token cost tells you nothing about whether a team is efficient. Per-outcome cost does. In our model:
| Use case | Monthly cost | Units | Unit cost |
|---|---|---|---|
| Support copilot | $38,400 | 64,000 resolved tickets | $0.60 per ticket |
| AI search | $62,400 | 5.2M searches | $0.012 per search |
| PR review agent (part of Engineering) | $41,000 | 9,800 merged PRs | $4.18 per PR |
A team that doubles its token spend while halving its cost per resolved ticket is doing great. A team whose token spend is flat while its cost per ticket creeps up is not. You only see the difference at this rung, which is why we'd argue it matters more than chargeback itself. It's also what measuring token output instead of outcomes gets wrong.
Rung 4: charge back, carefully.
Now money moves. Three traps are specific to LLM traffic, and each one will cause a budget dispute if you don't decide it in advance.
Trap 1: the cache writer pays for everyone. Prompt caching makes a shared prefix cheap for everyone except whoever writes it. On Anthropic-style pricing, a cache write costs 1.25x the base input rate and a cache read costs 0.1x. Model a 12,000-token shared system prompt and tool catalog on a $3-per-million-token input rate, used by three teams:
| Calls/day | Naive "caller pays" | Per call | Amortized | Per call | |
|---|---|---|---|---|---|
| Support (warms the cache each morning) | 1,000 writes | $45.00 | $0.0450 | $4.61 | $0.0046 |
| Product + Data (read it all day) | 40,000 reads | $144.00 | $0.0036 | $184.39 | $0.0046 |
| Total | 41,000 | $189.00 | $189.00 |
Naive attribution charges the team that warms the cache 12.5x more per call than the teams riding on it. Its cheapest local fix is to turn caching off, which pushes the writes onto the other teams and raises the company's bill by about a fifth. Treat shared prefixes as a platform cost and amortize them per call. We wrote about the underlying economics in the cache write tax.
Trap 2: requested cost vs. served cost. If a platform team routes, caches, or compresses on everyone's behalf, what do you charge a team for: the model it asked for, or the model that actually served the request? Some internal rate cards charge the requested model at list price, so the platform keeps the difference. It's tidy, and it kills the incentive: the team never sees its bill go down, so it never cooperates with the optimizations. Our recommendation is the opposite. Charge served cost, show requested cost. In our model, the support copilot's requested-model cost is $61,000 a month and its served cost is $38,400. Put both on the report. The $22,600 gap is the platform team's contribution, visible to the people it's saving money for.
Trap 3: charge only what a team controls. Evals, CI, and shared agents are real costs, but no single product team can change them. Charge those back as a flat platform fee, and keep the variable chargeback to spend the team can influence through model choice, prompt size, and call volume.
Rung 5: enforce at the gateway, not in a policy doc.
Only now do caps make sense, because now you know whose cap it is. A per-team budget with alerts at 50%, 80%, and 100% of forecast, and a model allowlist per key, enforced on the request path. A denied model should never leave the building. This is where runaway agent loops get stopped without throttling the teams that did nothing wrong.
What this doesn't solve.
Attribution tells you who spent the money. It doesn't make anyone spend less. A perfectly tagged bill that's 40% wasted is still 40% wasted, and a chargeback program with no optimization lever just moves the complaint from finance to the team leads. The five rungs are the accounting layer. The savings still come from the usual places: routing easy prompts off frontier models, caching, and trimming context before it's billed.
It also doesn't solve seat-based tools. A ChatGPT Enterprise or Copilot seat is a per-user subscription, allocated like any other SaaS license. This post is about metered API spend, which is where the variance lives.
Where Nadir fits.
We built the attribution layer into the gateway because the request path is the only place every call passes through. Tag a request with an opaque end_user id, in the body, the X-Nadir-End-User header, or OpenAI's user field, and add X-Nadir-Use-Case and X-Nadir-Tags for the rest of your taxonomy. The dashboard rolls spend up by org, team, and member. Every routed request is also scored against the model you'd otherwise have used, so the "requested vs. served" split in Trap 2 is a column you already have, not a project.
If you're at rung 1, start in observe mode: set layers.observe on a key and Nadir serves exactly the model the caller asked for, untouched, while recording what routing would have picked next to it. A month of that gives you a tagged showback report and a measured savings estimate before you change a single model string. Per-key model allowlists cover rung 5.
Start with a free key and have your first tagged showback report before the 2027 budget is locked.
Conclusion.
The invoice will keep telling you which model spent the money. Your CFO wants to know which feature did, what it earned, and whether next year's number is a forecast or a guess. Tag at the request, show back before you charge back, measure units instead of tokens, amortize what's shared, and charge teams for what was served rather than what they asked for. Do those five things this quarter and the AI line in your 2027 plan will be the one line you can actually defend.
Company figures in this post are illustrative, modeled for this tutorial, and are not derived from customer data. Sources: [The Next Web, "Salesforce expects to spend $300 million on Anthropic tokens this year," May 2026](https://thenextweb.com/news/salesforce-benioff-300-million-anthropic-tokens-slack-coding). [Mavvrik and Benchmarkit, "2025 State of AI Cost Governance Report"](https://www.mavvrik.ai/state-of-ai-cost-governance-report/). [SiliconANGLE, "AI token economics drives FOCUS specification updates," June 8, 2026](https://siliconangle.com/2026/06/08/ai-token-economics-focus-specification-updates-finopsx/). [OpenTelemetry, Semantic conventions for generative AI systems](https://opentelemetry.io/docs/specs/semconv/gen-ai/). [Anthropic, Prompt caching pricing](https://docs.anthropic.com/en/docs/build-with-claude/prompt-caching).