Abstract.
Prompt caching is usually pitched as the closest thing to free money in LLM cost optimization: cache a repeated prefix, pay roughly 10% of the base rate on every hit, no code change beyond a marker. A January 2026 paper (arXiv:2601.06007) ran that promise through 500-plus real agent sessions on DeepResearch Bench's 100 PhD-level research tasks, comparing three ways to draw the cache boundary across four models. Cost held up everywhere, 27.8% to 81.4% lower depending on model and strategy. Latency did not. Caching everything, including every tool call and tool result, cut GPT-4o's cost by 47.8% and made it 8.8% slower to first token than sending nothing to cache at all, because a dynamic tool result triggers a cache write with no future read to pay it back. Cache only the system prompt instead, and the same model gets 45.9% off and 30.9% faster, a strictly better trade on both axes except the two points of cost it leaves on the table. Gemini 2.5 Pro fails a different way, on a different strategy entirely. Here's the exact per-provider numbers, why the failure isn't the same model twice, and the cache-boundary code that keeps the win.
Research question.
If prompt caching's discount is real but where you draw the cache boundary can turn a savings mechanism into an added cost, where does that boundary actually sit for long-horizon, tool-calling agents, and does the answer differ enough by provider that a single fixed caching policy is the wrong thing to ship?
Caching was sold as free money. Agents are the workload that tests that promise.
The pitch for prompt caching has always been almost too simple: send the same prefix twice, and the second time costs roughly a tenth of the first. No model swap, no accuracy tradeoff, just a marker on a request. That pitch was built around chat, where the repeated prefix is a system prompt and a few turns of history. An agent is a different shape of workload. A single tool-calling loop can resend an entire, still-growing context on every step, and DeepResearch Bench, the benchmark this paper runs on, is built from exactly that shape: 100 PhD-level research tasks across 22 fields, the same class of long-horizon, multi-tool workload this blog measured burning a premium on its own. The paper's question is blunt: does the free-money pitch survive contact with an agent loop, where most of what grows the prefix on any given step is a tool result that will never appear byte-identical in another session again?
Three ways to draw the boundary, and 500 sessions to test them.
The authors, Lumer, Nizar, Jangiti, Frank, Gulati, Phadate, and Subbiah, tested four models, GPT-5.2, GPT-4o, Claude Sonnet 4.5, and Gemini 2.5 Pro, each running 40 independent agent sessions per cache condition against DeepResearch Bench, more than 500 sessions in total, each carrying a 10,000-token system prompt of research instructions, tool guidance, and synthesis procedures. Three cache-boundary strategies, defined by where the cache breakpoint sits:
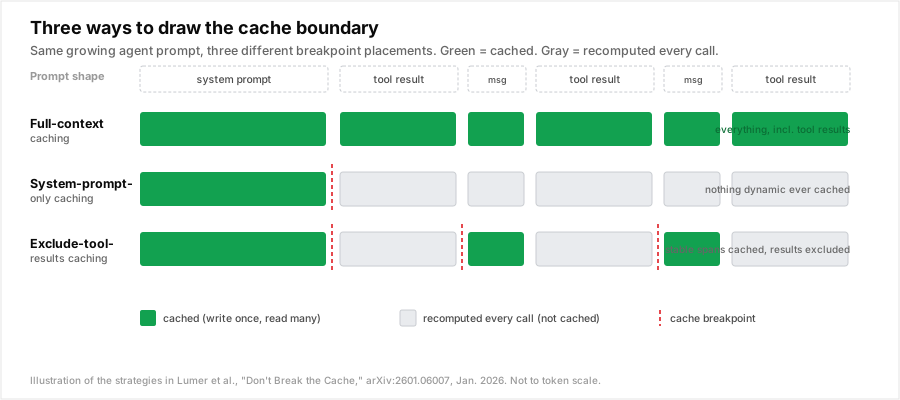
- Full-context caching. No cache breakpoints. The provider's default behavior caches the entire prompt prefix as it grows, system prompt, messages, tool calls, and tool results, all of it.
- System-prompt-only caching. One breakpoint placed right after the system prompt. Only that stable block is cached; every dynamic turn after it, human messages, tool calls, tool results, gets recomputed on every request.
- Exclude-tool-results caching. Breakpoints placed after the system prompt and after every tool result specifically, so the stable message content between tool calls accumulates in the cache while each tool result, "dynamic and session-specific" in the paper's own words, is deliberately kept out of it.
All three save money. Only one is safe on latency, and it isn't the same one everywhere.
Cost dropped across the board, from Gemini's worst combination to GPT-5.2's best:
| Model | Full-context caching | System-prompt-only caching | Exclude-tool-results caching |
|---|---|---|---|
| GPT-5.2 | 79.3% | 81.4% | 79.6% |
| Claude Sonnet 4.5 | 77.8% | 78.5% | 78.1% |
| Gemini 2.5 Pro | 38.3% | 41.4% | 27.8% |
| GPT-4o | 47.8% | 45.9% | 46.8% |
Read that table on its own and every strategy looks safe, the worst case is still a 27.8% discount. Time-to-first-token is where the strategies stop agreeing with each other:
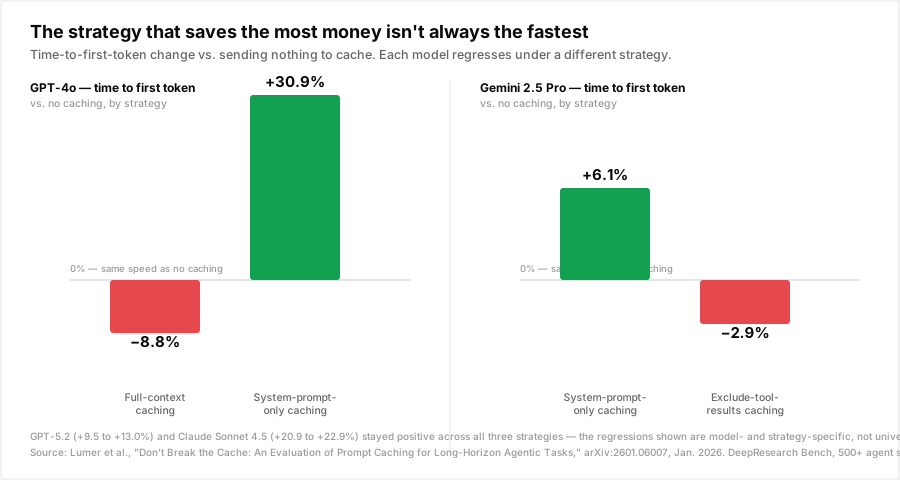
| Model | Full-context caching | System-prompt-only caching | Exclude-tool-results caching |
|---|---|---|---|
| GPT-4o | −8.8% (regression) | +30.9% (best) | not isolated in the paper |
| Gemini 2.5 Pro | ~+6.0% | ~+6.1% (best) | −2.9% (regression) |
GPT-5.2 and Claude Sonnet 4.5 didn't fail this way on any strategy tested: time-to-first-token stayed positive across the board, 9.5% to 13.0% for GPT-5.2 and 20.9% to 22.9% for Claude Sonnet 4.5. The paper doesn't break those two down strategy-by-strategy the way it does GPT-4o and Gemini, so the honest reading is narrower than "caching everything is dangerous": the regression is real, it is model- and strategy-specific, and two of the four models tested never hit it at all.
Look closely at GPT-4o's row and there's a second, quieter finding underneath the headline one. Full-context caching isn't a strictly worse choice there, it actually wins on cost, 47.8% against system-prompt-only's 45.9%. It loses on speed, badly, turning a caching setup into something slower than caching nothing. Whether that trade is worth two points of savings depends entirely on whether the workload is latency-sensitive, which for most agent loops it is. Gemini's failure is the less ambiguous kind: exclude-tool-results loses on both axes at once, 27.8% against system-prompt-only's 41.4% on cost and a straight regression on latency, with no offsetting win to weigh against it.
Why a cache write on a tool result is usually a bet you lose.
The mechanism is specific to what a cache write actually costs. The paper's own explanation: "full context caching triggers cache writes for dynamic tool calls and results, introducing overhead that offsets the benefits of cache reads." A cache write isn't free, several providers price it as a premium over a plain miss, and that premium is a bet that a matching cache read will happen later to pay it back. For a system prompt repeated across a thousand calls, that bet is close to a sure thing. For a tool result that's unique to one session, built from whatever a search query or a file read happened to return at that exact moment, the read essentially never comes. Full-context caching pays the write premium on every single tool result in every session, for a read that mathematically can't materialize, and GPT-4o's 8.8% regression is that unpaid bet showing up as latency instead of as a separate line item.
Where this sits among the other ways a cache quietly costs more than doing nothing.
This is the third distinct caching failure mode this blog has measured, and each one breaks a different assumption about what's safe to cache:
| Failure mode | What breaks | The fix |
|---|---|---|
| Premium cache-write rate | A provider prices writing to cache above a plain miss, so writing content that's never re-read is a pure loss | Write to cache only content you'll actually re-read many times |
| Query-aware compression breaking the prefix | Compression that rewrites the prefix differently per question changes it on every call, so the cache never gets a chance to hit | Compress only the stable, question-independent span; cap how far it can shrink |
| Full-context caching on tool results (this paper) | Every tool result is session-unique, so its cache write never earns a matching read | Breakpoint the cache right after the system prompt, or right before/after each tool result |
| Blind model switch mid-session | Switching to a cheaper model discards a warm, already-paid-for cache and eats a fresh write | Price a switch against the lost cache discount before recommending it |
Three different papers, three different mechanisms, the same underlying lesson: a cache is a bet on reuse, and the moment something enters it that won't be reused, the discount stops being a discount.
The fix, in code.
None of the three strategies require a new library, just deliberate placement of a cache breakpoint. The shape of system-prompt-only caching, the strategy that held up best across three of the four models tested:
def build_messages(system_prompt: str, turns: list[dict]) -> list[dict]:
    """Cache breakpoint right after the system prompt. Everything
    after it, tool calls, tool results, human turns, is recomputed
    on every request, on purpose: none of it is safe to cache."""
    return [
        {
            "role": "system",
            "content": [
                {
                    "type": "text",
                    "text": system_prompt,
                    "cache_control": {"type": "ephemeral"},
                }
            ],
        },
        *turns,
    ]


def build_messages_exclude_tool_results(system_prompt: str, turns: list[dict]) -> list[dict]:
    """Second breakpoint after every tool result, so the stable
    message content between tool calls keeps accumulating in the
    cache while each dynamic, session-unique result stays out of it.
    Measure this against system-prompt-only on your own traffic
    before defaulting to it: it wins on Gemini's cost axis but not
    its latency axis in the paper's own numbers."""
    messages = [
        {
            "role": "system",
            "content": [
                {
                    "type": "text",
                    "text": system_prompt,
                    "cache_control": {"type": "ephemeral"},
                }
            ],
        }
    ]
    for turn in turns:
        messages.append(turn)
        if turn.get("role") == "tool":
            messages[-1] = {**turn, "cache_control": {"type": "ephemeral"}}
    return messages
Three details from the paper matter more than the snippet above:
- Never let a dynamic value leak into the system prompt. A timestamp, a session ID, a request ID sitting inside the cached block busts the cache on every single call, regardless of which strategy you picked. The same discipline applies to tool schemas: the paper recommends implementing dynamic capabilities through code generation rather than editing a tool's function definition per request, since a changed schema is a changed prefix.
- Minimum cache size varies by provider, and it's a hard floor. OpenAI and Anthropic require at least 1,024 tokens of prefix before caching activates at all; Gemini 2.5 Pro requires 4,096. A short system prompt on Gemini gets none of this, no matter which strategy is chosen.
- Cache TTL varies from 5 minutes to 24 hours across providers, and the paper waited more than 24 hours between test conditions specifically to let every cache expire cleanly before measuring the next one. A session gap longer than the provider's TTL means the "cached" prefix is a fresh write again, which changes which strategy is worth the code.
What this doesn't solve.
DeepResearch Bench is one benchmark, built around long-horizon research agents with heavy tool use; a customer-support bot or a short-lived coding assistant has a different ratio of stable-to-dynamic content and might not reproduce the same regression at all. The four models tested are four specific model versions at one point in time, and both the cost percentages and which strategy regresses on which model are a function of each provider's current cache pricing and cache implementation, not a law of caching itself, a pricing change or a cache-architecture change on any provider's side could move these numbers without anyone updating this paper. And the paper attributes latency by strategy for GPT-4o and Gemini specifically; GPT-5.2 and Claude Sonnet 4.5 are reported as ranges across all three strategies, so treat "these two didn't regress" as accurate to what was published, not as evidence that no strategy could ever regress on them.
What to actually ship this week.
- Default to system-prompt-only caching, the one strategy that held up across three of the four models tested, and measure exclude-tool-results against it on your own traffic before switching, rather than assuming a paper's ranking transfers unchanged.
- Track time-to-first-token per request next to cost per request. A caching change that lowers the bill and slows the loop at the same time is a real possibility, not a hypothetical, GPT-4o's full-context row is exactly that.
- Keep timestamps, session IDs, and per-request identifiers out of anything you intend to cache. That one habit determines whether any strategy has a chance to work at all.
- Re-measure after a provider changes cache pricing, TTL, or minimum size. These numbers are a snapshot of four specific APIs in January 2026, not a permanent ranking.
Conclusion.
The paper's title says the quiet part directly: caching, done carelessly, is something you can break rather than something that only ever helps. Cost held up in every single condition tested here, 27.8% to 81.4% cheaper depending on model and strategy, which is the part that makes "cache everything" feel like a safe default. Latency is where that default stops being safe, and not in the same place twice: GPT-4o pays for full-context caching in seconds, Gemini pays for over-excluding in seconds, and two of the four models tested never pay for either. The same instinct that keeps a compressed prompt from silently invalidating its own cache applies here at the boundary-placement layer instead of the compression layer: measure the strategy against your own traffic, on your own provider, before it becomes the thing quietly adding a second to every request. Nadir's Context Optimize already treats a stable prefix as a contract rather than a suggestion, its /v1/optimize call reproduces a previously optimized conversation byte-identically as it grows, specifically so a cache keyed on that prefix keeps hitting instead of getting invalidated by the very tool meant to shrink it, and cache-hit status comes back on every request in the response metadata and the savings dashboard, so which strategy is actually paying off is a number you can watch, not a guess you inherit from someone else's benchmark.
Sources: [Lumer, Nizar, Jangiti, Frank, Gulati, Phadate, and Subbiah, "Don't Break the Cache: An Evaluation of Prompt Caching for Long-Horizon Agentic Tasks," arXiv:2601.06007, submitted January 9, 2026, revised January 31, 2026](https://arxiv.org/abs/2601.06007).