Two headlines, eight days apart.
On July 9, 2026, Meta opened its first paid model API and priced Muse Spark 1.1 at $1.25 per million input tokens and $4.25 per million output tokens, roughly a quarter of what Claude Opus 4.8 and GPT-5.5 charge. This blog covered the qualification question that raised at the time: is a fourth lab undercutting frontier pricing safe to route traffic to. Four days later, on July 13, Forbes ran a different question entirely. In "Cheaper AI Tokens Do Not Guarantee Cheaper Enterprise Agents," Janakiram MSV argued that agentic systems turn a single user request into repeated rounds of planning, retrieval, tool calls, validation, and retries, so the price per token can fall while the cost of a completed task, and the organization's total AI spend, keeps rising. Source: Forbes, "Cheaper AI Tokens Do Not Guarantee Cheaper Enterprise Agents," July 13, 2026
A week after that, Fortune ran a piece from Sumeet Agrawal, Salesforce's VP of Product Management for Data, AI Governance & Context Engineering, making the same argument from the buyer's side: "Every company can buy more tokens. Very few know how to extract more value from fewer of them." His number for where that value leaks: inefficient data handling and context bloat routinely burn 5 to 10x more tokens than a task actually needs, before any list-price cut gets a chance to matter. Source: Fortune, "The leaky AI pipeline: why cheaper tokens won't fix enterprise AI," July 20, 2026 Two outlets, two authors, one week apart, converging on the same uncomfortable fact: this blog has already documented model prices getting cut roughly every six to eight weeks in 2026, and enterprise AI bills are not falling on the same schedule.
Where the money in a session actually sits.
The reason isn't mysterious once you look at an actual trajectory instead of a rate card. Augment Code published a breakdown of one measured Claude Sonnet coding session: 996,500 total tokens, $0.55 billed. The split: cache reads made up about 94.5% of that spend, cache writes about 5.0%, output tokens about 0.5%, and fresh uncached input about 0.1%. Source: Augment Code, "AI Coding Cost Analysis: Where Token Spend Really Goes in an Agent Loop," 2026
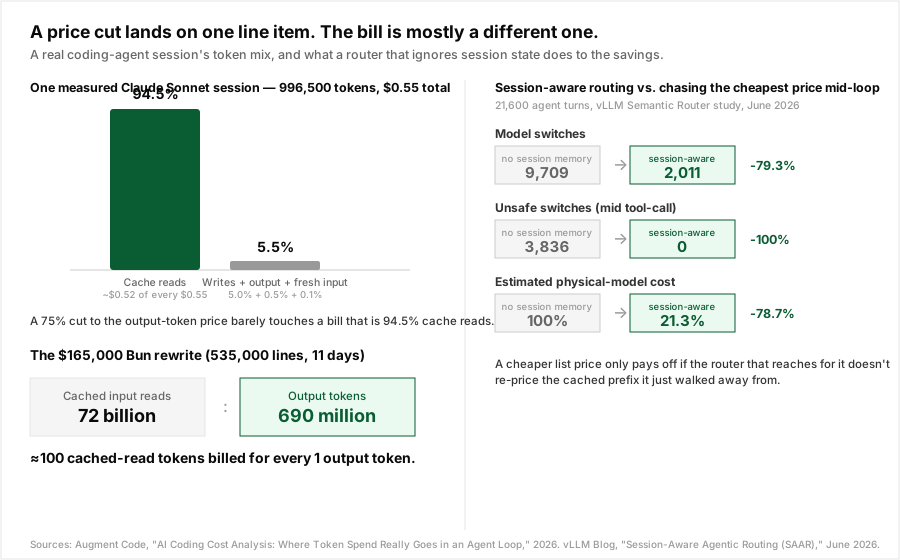
The same guide traces a production example at scale: a $165,000 migration that rewrote 535,000 lines of code in 11 days logged 5.9 billion uncached input tokens, 690 million output tokens, and 72 billion cached input reads, roughly 100 cached-read tokens billed for every output token the model actually wrote. The guide's own conclusion: "input tokens dominate agentic coding spend, often exceeding 99% of trajectory volume," which makes loop design and context management a bigger lever on the bill than which model you picked.
That's the same shape of finding this blog measured directly in a separate 2,848-run study of Claude Code trajectories: cache creation and cache reads dominate the real invoice, and the tokens most optimization advice targets, prompt size, tool-output size, aren't where most of the money is.
A price cut only touches one line item.
Sit that trajectory data next to Muse Spark 1.1's pricing and the disconnect gets concrete. A 75% cut to output-token price is a real, meaningful number on a rate card. Applied to a session that's 94.5% cache reads and 0.5% output, it moves the total bill by a fraction of a percent. The marketing headline is "up to 75% cheaper." The invoice moves by less than one part in a hundred, because the price that got cut was never the price driving the cost.
This is not a reason to ignore cheaper models, cheaper output tokens genuinely help on output-heavy workloads, long-form generation, structured extraction, code synthesis without deep repo context. It is a reason to stop treating "a lab cut prices" as a proxy for "my bill will drop," the same way fewer tokens in a prompt turned out to be a weak, unstable predictor of a lower bill once cache mechanics were accounted for. Both are versions of the same mistake: optimizing the number that's easy to see instead of the one the invoice is actually built from.
The second way sticker-price chasing backfires: it breaks the cache you already paid for.
There's a sharper failure mode than a price cut doing nothing. If a router reaches for whichever model just got cheaper in the middle of a session, it can make the bill worse, not neutral. Provider prompt caches are keyed to a specific model plus a byte-stable prefix; a cached prefix warm on one model is invisible to another. Switch models mid-session to chase a lower list price and the entire prefix re-processes on the new model, at that model's fresh or cache-write rate, forfeiting whatever discount the old model had already earned.
A June 2026 study from the vLLM Semantic Router project measured exactly this across 21,600 deterministic agent turns. A router with no session memory, one that reselects the best-looking model on every turn, produced 9,709 model switches, of which 3,836 landed mid-tool-call: a tool result routed to a model that never made the tool call, or continuation state sent to a backend that couldn't use it. Adding router-owned session memory, which tracks the last physical model, switch history, cache evidence, and applies hard locks around active tool loops and non-portable provider state, cut switches to 2,011 (down 79.29%), eliminated every one of the 3,836 unsafe switches, and cut estimated physical-model cost by 78.71% against the same workload. Source: vLLM Blog, "Session-Aware Agentic Routing (SAAR)," June 2026
Read that against the trajectory data above and the mechanism is obvious: 94.5% of a session's cost lives in reads of a cache that only stays cheap if you stay on the model that wrote it. A router that switches models every time a cheaper rate card shows up is optimizing exactly the 5.5% of the bill that a price cut can touch, while repeatedly re-triggering the expense that makes up the other 94.5%.
What actually correlates with a lower cost per completed task.
| Lever | Touches | What the data above shows |
|---|---|---|
| Wait for a cheaper list price | Output and fresh-input tokens (~0.6% of a typical session) | Barely moves a bill that's 94.5% cache reads |
| Switch models mid-session for a better rate | Whichever model currently looks cheapest | Re-prices the cached prefix; added back 78.71% of cost in the SAAR study when done without session state |
| Cut prompt or tool-output size | Prompt and tool-output tokens | Weak, unstable predictor of billed cost once cache mechanics dominate (Pearson r = 0.154 in a separate 2,848-run study) |
| Session-aware, evidence-gated routing | The decision of which model handles a turn, made once per turn and honoring cache locality | Cut cost 78.71% in the SAAR study; a separate reference-assisted RouterBench cascade projected 98% retained quality, a research ceiling rather than deployed performance |
What to ship this week.
- Pull your own trajectory breakdown before reacting to a price cut. Providers report token usage by category; if reads dominate your bill the way they dominated Augment's example, a cheaper output rate is not the lever, and you should say so before a stakeholder asks why the "75% cheaper" model didn't move the invoice.
- Treat mid-session model switching as a cost decision, not just a routing decision. A switch that ignores the warm cache can cost 2.4x more than staying put, even when the destination model is nominally cheaper per token.
- Measure cost per completed task, not cost per token. A cheaper model that fails more often, or that gets re-selected every turn and keeps re-paying the cache-write tax, can lose to a pricier model that finishes the job once and stays put.
- Route the decision, not the sticker price. Nadir can recommend a governed model-and-effort plan beside the gateway, keep the caller's model in shadow mode, and attach measured outcomes before enforcement. Complete non-streaming proxy responses can optionally enter the reference-free verifier cascade; streaming bypasses it.
Conclusion.
Two publications made the same argument from opposite sides of the negotiating table within a week of each other in July 2026, and the trajectory data explains why they were both right: a rate card and an invoice are not the same document. Muse Spark 1.1's launch price is real, and so is every other price cut on the roughly six-to-eight-week cadence this blog has tracked through 2026. None of them touch the 94.5% of a session that's spent re-reading a cache, and a router that chases each new cut by switching models mid-session can turn a savings pitch into a cost increase, exactly what happened to 78.71% of cost in a study that measured it directly. The fix was never "wait for a cheaper model." It's a routing decision that's made once per turn, that knows what's already warm, and that only pays the cache-write tax when the task actually needs a different model, not whenever a press release says one got cheaper.
Related reading.
- Meta priced Muse Spark 1.1 at a quarter of frontier rates on July 9. Here is the five-step protocol for qualifying a new cheap model before it touches production traffic.
- Provider prompt caches are keyed to a specific model. Here is the break-even math for when a mid-session switch to a cheaper model still pays off.
- Every compression pitch assumes fewer tokens means a smaller bill. A 2,848-run study found the correlation is nearly zero.
- A reference-assisted RouterBench research cascade projected 60% lower cost at 98% retained quality; it is not the live deployed path.
- Uber burned its entire 2026 AI budget in four months. Here is what the per-developer numbers looked like.
Sources: [Forbes, "Cheaper AI Tokens Do Not Guarantee Cheaper Enterprise Agents," July 13, 2026](https://www.forbes.com/sites/janakirammsv/2026/07/13/cheaper-ai-tokens-do-not-guarantee-cheaper-enterprise-agents/). [Fortune, "The leaky AI pipeline: why cheaper tokens won't fix enterprise AI," July 20, 2026](https://fortune.com/2026/07/20/leaky-ai-pipeline-cheaper-tokens-salesforce-vp/). [Augment Code, "AI Coding Cost Analysis: Where Token Spend Really Goes in an Agent Loop," 2026](https://www.augmentcode.com/guides/ai-coding-cost-analysis-agent-token-spend). [vLLM Blog, "Session-Aware Agentic Routing (SAAR)," June 2026](https://vllm.ai/blog/2026-06-02-session-aware-agentic-routing). [vLLM Semantic Router Docs, "Session Aware"](https://vllm-semantic-router.com/docs/v0.3/tutorials/algorithm/selection/session-aware/).