Abstract.
Every compression pitch rests on the same silent assumption: fewer tokens in the prompt means a smaller bill. A July 2026 paper (arXiv:2607.12161) tested that assumption against 2,848 real Claude Code runs across 103 tasks, 7 repositories, and 3 models, and it doesn't hold. Reconstructing the actual invoice into four billing components, the authors found cache creation and cache reads alone account for roughly 80% of the real bill, dwarfing the tool-output and prompt tokens most compression tools are built to shrink. Per-task token reduction turned out to be a weak, unstable predictor of cost change, Pearson r = 0.154. One compressor removed 38% of tool-output tokens and still cost 6.8% more. A heavier one, an API-boundary proxy, cost 48.4% more. Only the most conservative, deterministic compressor actually saved money, and even that was a modest 2.7%. Here's the four-component cost model the paper reconstructs, why aggressive compression corrupted the exact edit anchors a coding agent needs to apply its own patches, and what to measure instead of a token count.
Research question.
If reducing the tokens sent to a model is supposed to reduce the bill, does that hold once caching, trajectory length, and task success are accounted for, or can a context-reduction system remove real tokens while the paired, billed dollar cost goes up?
The instinct everyone building a compression tool shares.
Prompt compression's pitch has always been arithmetic: strip the low-information tokens, keep the meaning, pay for less. It's intuitive enough that it barely gets questioned, fewer tokens sent, fewer tokens billed. Sarel Weinberger and Amir Hozez's paper, "Token Reduction Is Not Cost Reduction" (arXiv:2607.12161), tests that intuition the way it should be tested: not by counting tokens before and after a compression pass, but by pulling the actual dollar amount an API invoice charges for each run and asking whether it moved the way the token count says it should have.
Four buckets, one bill.
The authors instrumented 2,848 analyzed Claude Code runs, drawn from a larger program of roughly 5,500 billed executions, spanning 103 tasks across 7 repositories and 3 Claude model tiers (the correlation study specifically used Haiku). Every run's cost was reconstructed into four components: uncached input tokens, cache-creation tokens, cache-read tokens, and generated output tokens, then checked against the actual invoiced amount to see how much was left unaccounted for.
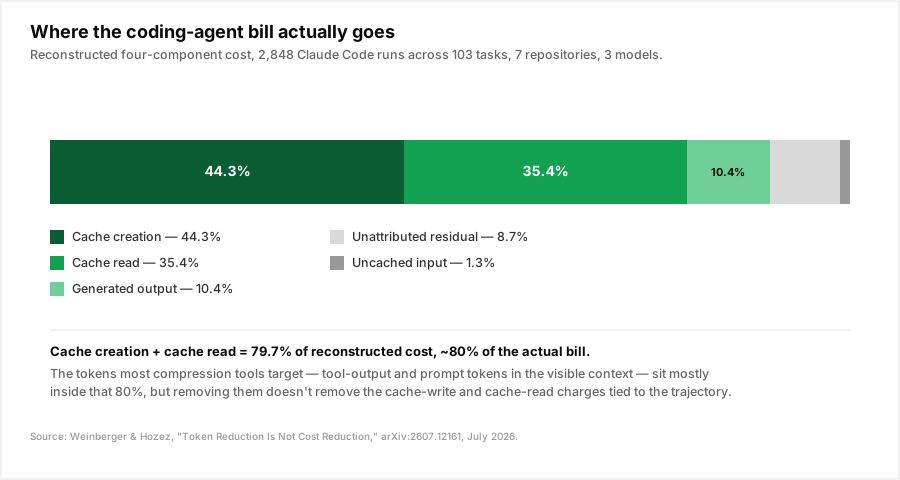
| Cost component | Share of reconstructed cost | 95% CI |
|---|---|---|
| Cache creation | 44.3% | [43.2%, 45.3%] |
| Cache read | 35.4% | [34.5%, 36.3%] |
| Generated output | 10.4% | [10.0%, 10.9%] |
| Unattributed residual | 8.7% | [7.2%, 10.1%] |
| Uncached input | 1.3% | [1.1%, 1.5%] |
Source: Weinberger and Hozez, "Token Reduction Is Not Cost Reduction," arXiv:2607.12161, July 2026
"Cache creation and cache reads accounted for approximately 87% of the reconstructed four-component cost," the paper states, "about 80% of the actual bill." That's the number that reframes everything downstream: the tokens a typical compressor targets, verbose tool output, repeated context, pretty-printed JSON, mostly live in the 11.7% left over between uncached input and generated output. Shrinking that slice can look dramatic in a token count and still be a rounding error against the trajectory-length charges that dominate the invoice.
Three systems, one paired test, and three different stories.
The paper ran a paired comparison, same tasks, same model, against a plain baseline Claude Code session and three context-reduction systems of increasing scope:
- RTK, a hook-based deterministic compressor that trims tool output through fixed rules, no model call involved.
- RTK-ML, the same hook wired to nine flag-gated machine-learning-based compression capabilities layered on top.
- Headroom v0.27.0, an API-boundary proxy that intervenes on the request itself rather than inside the agent's own tool-call loop.
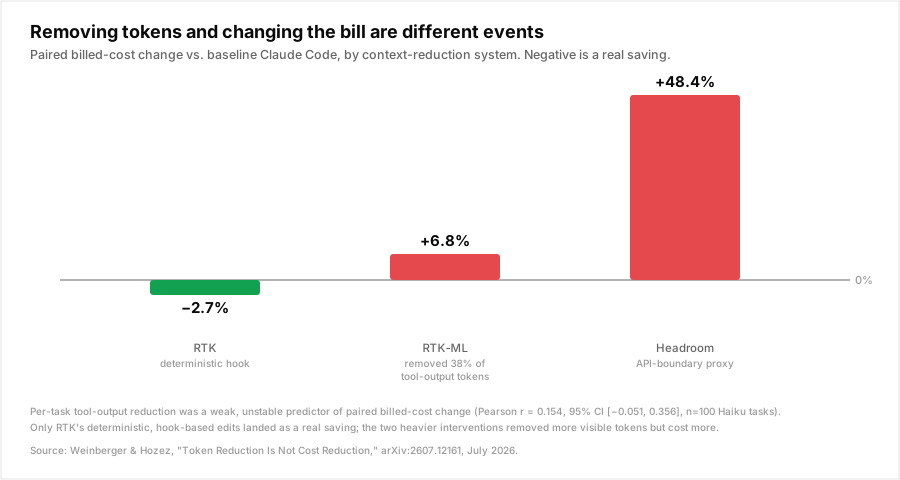
| System | Paired cost change vs. baseline | 95% CI |
|---|---|---|
| RTK | −2.7% | [−5.6%, −0.1%] |
| RTK-ML | +6.8% | [+2.8%, +11.3%] |
| Headroom v0.27.0 | +48.4% | [+42.3%, +55.0%] |
Only the smallest, most conservative intervention landed in the black, and only barely. The two systems built to remove more, RTK-ML's ML-driven capabilities and Headroom's proxy rewrite, both cost more than doing nothing.
The 38% paradox.
RTK-ML is the finding worth sitting with. It "removed 38% of estimated raw tool-output tokens," a real, measurable, aggressive cut, and its paired cost still came in 6.8% higher than the uncompressed baseline. That's not noise; the 95% confidence interval, +2.8% to +11.3%, never crosses zero.
The mechanism traces straight back to the cost breakdown above. Tool-output tokens are a small slice of a much larger trajectory-cost stack dominated by cache creation and cache read charges tied to how long and how many turns a session runs, not to the byte size of any one tool result. Cutting a tool-output token doesn't automatically shrink the cache writes and reads billed against the surrounding trajectory, and if a heavier compression pass adds its own model calls, extra turns, or retries to do the cutting, it can add more to the dominant 80% than it saves from the 11.7% it's actually targeting. Headroom's +48.4% is the same failure at a larger scale: intervening at the API boundary touches more of the request lifecycle than a hook-based rule, and more surface area for extra cost is more surface area for extra cost, whether or not the visible token count went down.
Correlation, not causation: r = 0.154.
Across 100 Haiku tasks, the paper measured how well per-task tool-output token reduction predicted the paired billed-cost change for that same task. The result: Pearson r = 0.154, 95% CI [−0.051, 0.356]. That interval crosses zero. A task where a compressor cut a large fraction of its tool-output tokens was not reliably a task where the bill went down, and a task with a small token cut was not reliably cheap either. If token reduction were a decent proxy for cost reduction, this correlation would be strong and positive. It isn't, and the paper's own words are direct about what that means: "a system may remove a large fraction of a particular tool output while changing only a small fraction of total billed cost, because the removable output may represent a small part of the complete prompt-cache and trajectory cost stack."
When compression breaks the thing it's compressing.
The paper's second experiment is a narrower, sharper test: single-shot SEARCH/REPLACE patch application on 40 SWE-bench-derived Go tasks, comparing raw context against compressed context.
| Condition | Patches applied | Resolved (tests passing) |
|---|---|---|
| Raw context | 27/40 | 2/40 |
| Compressed context | 15/40 | 1/40 |
Compression cost 12 rows of patch applicability net, by corrupting the exact verbatim edit anchors, the specific lines a SEARCH/REPLACE patch has to match character-for-character, that a coding agent depends on to apply its own output. This is a different failure from the cost paradox above: it's not that compression failed to save money, it's that on a meaningful fraction of tasks it broke the mechanism the agent needed to finish the task at all, which is its own, more expensive kind of cost. This is the same shape of failure this blog measured in prompt caching's own boundary-placement problem: a token-saving move that looks safe in isolation can quietly break something specific to the workload it's applied to, and the only way to know is to measure the workload, not the technique.
CPS: the metric that actually matters.
Raw cost change alone still understates the problem, because it doesn't account for whether the task succeeded. The paper's preferred metric is cost per successful execution, CPS, which folds the success rate into the cost comparison directly:
| System | CPS ratio vs. baseline | 95% CI |
|---|---|---|
| RTK | 0.968 | [0.937, 1.004] |
| RTK-ML | 1.051 | [1.006, 1.100] |
| Headroom v0.27.0 | 1.464 | [1.397, 1.531] |
Headroom's CPS ratio, 1.464, is worse than its already-bad raw cost change, 48.4%, because it isn't just costing more per run, it's also failing more often, so each successful run absorbs the cost of the failed ones around it. RTK-ML's CPS ratio, 1.051, confirms its raw cost increase wasn't offset by a success-rate improvement either. RTK is the only system whose CPS confidence interval, [0.937, 1.004], comes close to touching parity with baseline, and even there it doesn't clearly beat it once uncertainty is accounted for.
Where this sits among the other ways a token-saving move quietly costs more.
This is the fourth distinct cost-mechanism failure this blog has covered, and each one breaks a different assumption about what "optimizing tokens" actually means:
| Failure mode | What breaks | The fix |
|---|---|---|
| Premium cache-write rate | Writing to cache costs more than a plain miss, so writing content that's never re-read is a pure loss | Write to cache only content you'll actually re-read many times |
| Query-aware compression breaking the prefix | Compression that rewrites the prefix per question changes it on every call, so the cache never hits | Compress only the stable, question-independent span |
| Full-context caching on tool results | Every tool result is session-unique, so its cache write never earns a matching read | Breakpoint the cache right after the system prompt |
| Token reduction vs. billed cost (this paper) | The tokens compression targets are a small slice of a bill dominated by cache creation and cache read charges | Measure paired, success-adjusted billed cost, not tokens removed |
Four different papers, four different mechanisms, the same underlying lesson: a token count is a proxy, and the moment the thing it's a proxy for, a cache hit, a prefix match, a trajectory length, moves independently of it, the proxy stops being useful.
Measure this yourself: success-adjusted billed cost, in code.
The paper's recommendation is a measurement discipline, not a specific tool: evaluate any context-reduction system on paired, success-adjusted billed cost, never on tokens removed alone. A minimal harness for that comparison:
from dataclasses import dataclass

@dataclass
class RunResult:
    task_id: str
    succeeded: bool
    uncached_input_tokens: int
    cache_creation_tokens: int
    cache_read_tokens: int
    output_tokens: int
    billed_cost_usd: float  # from the actual invoice, not a token-price estimate

def cost_per_success(runs: list[RunResult]) -> float:
    total_cost = sum(r.billed_cost_usd for r in runs)
    successes = sum(1 for r in runs if r.succeeded)
    if successes == 0:
        return float("inf")
    return total_cost / successes

def cps_ratio(baseline: list[RunResult], variant: list[RunResult]) -> float:
    """>1.0 means the variant costs more per successful run than baseline,
    even if it used fewer tokens on average. This is the number that
    decides whether a compressor is actually worth shipping."""
    return cost_per_success(variant) / cost_per_success(baseline)
Two details from the paper matter more than the snippet: pair the comparison per task, same task run under baseline and under the variant, rather than averaging two unrelated populations, since that's what makes a correlation like r = 0.154 measurable at all. And pull billed_cost_usd from the actual invoice or the API's own usage response, not a token-count-times-list-price estimate, since that estimate is exactly the number this paper shows can diverge from the real charge once cache creation and cache read are involved.
What this doesn't solve.
This is a study of Claude Code specifically, three compression systems specifically (RTK, RTK-ML, Headroom v0.27.0), and Anthropic's current cache-pricing structure specifically; a different agent harness with a different ratio of tool-output tokens to trajectory length, or a provider that prices cache creation differently, could reproduce a smaller version of this gap or a larger one. The 100-task correlation study used Haiku, one tier of one model family, so treat r = 0.154 as evidence that the relationship is weak on that workload, not as a universal constant across every model and task type. And the Go patch-corruption result is specific to SEARCH/REPLACE-style patching, a workload where verbatim character matches carry unusual weight; a coding agent that edits by line number or by AST node might not see the same 27/40-to-15/40 drop from the same compression pass.
What to actually ship this week.
- Pull the actual billed cost per run from your provider's usage response, not a token-count estimate, before evaluating any compression or context-reduction change. This paper's whole argument is that the two diverge often enough to matter.
- Pair every comparison by task. An aggregate "average tokens down 20%, average cost down 5%" hides exactly the paradox this paper found at the per-task level; measure the same task under both conditions.
- Track cost per successful execution, not cost per run. A compressor that fails more often looks cheaper per call and more expensive per completed task, and the second number is the one your bill actually reflects.
- Test compression against the exact mechanism your agent depends on to finish a task, patch application, tool-call formatting, whatever it is, before shipping it broadly. A 38% token cut that corrupts an edit anchor on a meaningful fraction of tasks isn't a savings, it's a retry tax.
Conclusion.
The paper's title is the whole argument in five words: token reduction is not cost reduction. Every number in it points the same direction. Cache creation and cache reads make up roughly 80% of a real Claude Code bill, the slice most compression tools never touch. Per-task token cuts predicted cost change only weakly, r = 0.154, an interval that crosses zero. The system that removed the most tokens, RTK-ML at 38% of tool output, cost more, not less. And the heaviest intervention, an API-boundary proxy, cost 48.4% more while also failing more often, a combination its own CPS ratio, 1.464, makes explicit. Nadir's cascade routing and cost dashboard are built around the same discipline this paper argues for: the savings shown are the real, paired dollar delta against an always-premium baseline on your own traffic, per request, in the response metadata and the dashboard, not a token count run through a price sheet. A compression pass, a routing decision, a cache-boundary change, none of them are savings until the invoice says so.
Sources: Sarel Weinberger and Amir Hozez, "Token Reduction Is Not Cost Reduction," [arXiv:2607.12161](https://arxiv.org/abs/2607.12161), submitted July 13, 2026, revised July 15, 2026.