A format tax nobody put on the invoice
Open the payload your agent gets back from a tool call, a RAG lookup, or a database query mid-loop, and it is almost always JSON: a brace to open the object, a quote around every key, a colon, a quote around every string value, a comma, repeated identically on every single row of the array. None of that punctuation carries information the model needs to understand the data. All of it gets tokenized and billed at the same input rate as the data itself.
TOON, short for Token-Oriented Object Notation, is a small, MIT-licensed, JSON-compatible format built specifically to strip that repetition out. Source: GitHub, toon-format/toon It shipped in 2025, and within months five independent language ports appeared: TypeScript, Python, Go, Rust, and .NET, each aiming for spec compliance with the original. Source: Analytics Vidhya, "TOON: Save 60% on Tokens," November 2025 That pace of independent adoption, for a plain-text format with no vendor behind it, is the tell that it is solving a cost every team already has, not a problem someone invented to sell a library.
What TOON actually does to a JSON payload
TOON keeps JSON's full data model, objects, arrays, strings, numbers, booleans, null, so it round-trips losslessly back to identical JSON. What changes is the encoding. A uniform array of objects, the shape a paginated API response, a RAG chunk list, or a SQL query result almost always takes, gets a field header declared once, followed by CSV-style rows:
orders[50]{order_id,customer,status,carrier,total_usd,items,created_at}:
  ORD-10000,customer_0@example.com,shipped,UPS,19.99,1,"2026-07-01T14:00:00Z"
  ORD-10001,customer_1@example.com,processing,FedEx,23.36,2,"2026-07-02T14:01:00Z"
  ORD-10002,customer_2@example.com,delayed,USPS,26.73,3,"2026-07-03T14:02:00Z"
Compare that to the equivalent JSON, which repeats "order_id":, "customer":, "status": and every other key on every one of the 50 rows, plus a brace and a comma per row:
{"orders": [{"order_id": "ORD-10000", "customer": "customer_0@example.com", "status": "shipped", "carrier": "UPS", "total_usd": 19.99, "items": 1, "created_at": "2026-07-01T14:00:00Z"}, {"order_id": "ORD-10001", "customer": "customer_1@example.com", ...The array length in orders[50] and the declared field list also give the model an explicit row count and schema up front, which the format's authors report helps rather than hurts retrieval accuracy on long arrays, not just a smaller byte count. For data that is not uniform, deeply nested objects, mixed types, optional fields that vary row to row, TOON falls back to YAML-style indentation. That fallback is honest rather than a stretch goal: nested data is exactly where the savings mostly disappear, covered below.
The concrete number
The format's own published benchmark, run across Claude Haiku, Gemini, and Grok on 244 questions, reports TOON holding retrieval accuracy at 72.2% against JSON's 71.4%, essentially even, while using 42.6% fewer tokens to encode the same data. Source: GitHub, toon-format/toon, benchmark results Reported savings range from about 30% on mixed-structure datasets up to nearly 59% on flat, fully uniform ones.
We ran an independent test rather than take the headline number on faith: a 50-row order-lookup result, the kind of payload a tool call returns mid-agent-loop, encoded three ways and counted with tiktoken's o200k_base tokenizer.
| Encoding | Tokens | vs. typical JSON |
|---|---|---|
| JSON, as typically sent (indented, spaced) | 3,431 | baseline |
| JSON, minified (no whitespace) | 2,732 | -20% |
| TOON | 1,886 | -45% |
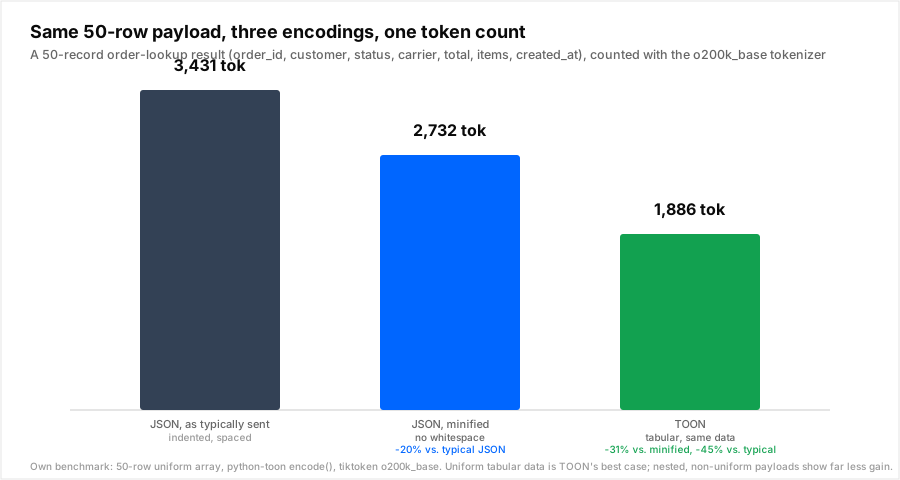
That last row is a 31% cut against minified JSON specifically, the fair comparison, since most teams that care about tokens are already minifying. It lines up with the format's own reported 30-59% range for exactly the uniform-array case this test used.
Where the savings disappear
The honest version of this post also runs the case where TOON is not the right tool. We encoded a small, deeply nested config object, feature flags with mixed sub-fields, an array of incident records with a free-text note field, a list of owner emails, no two branches of the object shaped alike. Minified JSON: 124 tokens. TOON: 125 tokens. A wash, and technically TOON came out a hair worse.
That is not a bug in our test; it matches the format's own numbers. Its published benchmark shows only a 1.6% edge over compact JSON on non-tabular, mixed data, because the entire mechanic TOON relies on, declare the field header once, skip repeating it per row, requires a uniform array to declare a header for. A one-off nested object has nothing to tabularize. It is also worth being precise that raw CSV, with zero structural markup at all, still beats TOON by about 6% on purely flat, single-level tables; TOON's overhead there buys back the explicit row count, nesting support, and typed values CSV cannot represent, which matters once a model has to reason about the data rather than just echo it back. The honest read: reach for TOON specifically when a payload is a list of same-shaped records, and don't expect it to rescue a bill dominated by irregular JSON blobs.
A different lever than the ones already on this bill
Most of what inflates a token bill is a question of what gets sent: RAG pipelines that fetch 20 chunks and use 3, structured-output schemas repeated on every call, tool-call schemas resent on every turn, MCP servers loading their full tool catalog before any work happens. We already tested the obvious character-level compression tricks for prose, dropping letters, gzip, base64, and every one of them made text more expensive, not less, because a mangled word usually costs the tokenizer more sub-word tokens than the intact one did. TOON is not that. It is not compressing text, and it is not deciding what data survives; it is changing how whatever data you've already decided to send gets serialized once it's structured and uniform, which is a genuinely different axis from all of the above and stacks with each of them rather than competing.
It also stacks with what Nadir already does automatically. Context Optimize measured a 61% cut in input tokens on Claude Opus by deduplicating repeated tool schemas and boilerplate before a request goes out; that's a context-level trim. TOON is a serialization-level change you make in your own code, to your own payloads, before they ever reach a router. Trim what you send, encode what survives efficiently, then route the request to the cheapest model that can still handle it. Three independent levers, three separate savings, none of which requires touching the others.
Five lines to try it
The reference implementation is TypeScript; a community-maintained Python port exists and is explicitly labeled beta, working toward full spec compliance:
# pip install git+https://github.com/toon-format/toon-python.git
from toon_format import encode

def tool_result_for_prompt(rows: list[dict]) -> str:
    # rows is whatever your tool call, RAG retriever, or DB query already
    # returns as a list of same-shaped dicts. Nothing upstream changes.
    return encode({"results": rows})

messages = [
    {"role": "system", "content": "Answer using only the data below."},
    {"role": "user", "content": tool_result_for_prompt(order_rows)},
]
Nothing about the application's data layer changes. The only new step is the encode() call immediately before the payload becomes prompt text, and decode() on the way back in if the model returns TOON itself.
That request still goes wherever it was going to go. Routing it through Nadir prices whatever the request actually costs after the format change, not a number computed against JSON:
import openai

client = openai.OpenAI(
    base_url="https://api.getnadir.com/v1",
    api_key="YOUR_NADIR_KEY",
)

response = client.chat.completions.create(
    model="auto",  # Nadir routes and prices the request as it actually
                    # arrives; a TOON-encoded tool result is fewer input
                    # tokens than the JSON version, and the cost header
                    # reflects that immediately, no separate config
    messages=messages,
)

print(response.model)
print(response.model_extra["nadir_metadata"]["cost"]["total_cost_usd"])
What to actually do this week
- Audit your largest recurring tool-call and RAG payloads for uniformity first. TOON's win is proportional to how tabular the data already is; a list of same-shaped records is the target, not every JSON blob in the codebase.
- Minify before you compare, or you'll overstate the win. The honest comparison is TOON versus minified JSON, not TOON versus indented JSON; the gap is still real, just smaller than the flashiest headline number.
- Pin a specific version of whichever language port you adopt. The Python implementation is explicitly beta; the format spec and TypeScript reference are the stable ground truth to test a port's output against.
- Don't expect it to fix an irregular-data bill. Deeply nested, non-uniform payloads saw close to zero benefit in both our test and the format's own published numbers; look at context trimming or over-retrieval for that class of cost instead.
- Measure the actual token count on your own payloads, not the vendor average. A 31% cut on a 50-row order lookup and a 59% cut on a fully flat dataset are both real, reported numbers for different shapes of data; where your traffic lands depends on your own schema, not the benchmark's.
Conclusion
The format savings here are real and independently reproducible, we measured 31% on our own payload against minified JSON, close to the format's own reported range, and the cost is close to zero: one encode call before the prompt goes out, one decode call if the model hands data back. What makes it worth a specific mention rather than a footnote is how narrow and honest its actual scope is. It does nothing for prose, nothing for irregular nested objects, and it loses to raw CSV on purely flat data with no type or nesting needs. It wins, specifically and considerably, on the exact shape of payload that tool calls, RAG lookups, and database results return dozens of times inside a single agent session. That's a common enough shape that a 30-45% cut on it is worth the five lines, and small enough a scope that it earns a place alongside context trimming and routing rather than a claim to replace either.
Sources: [GitHub, toon-format/toon, format spec and benchmark results](https://github.com/toon-format/toon). [GitHub, toon-format/toon-python](https://github.com/toon-format/toon-python). [Analytics Vidhya, "TOON: Save 60% on Tokens," November 2025](https://www.analyticsvidhya.com/blog/2025/11/toon-token-oriented-object-notation/).