Claude Code, Cursor, and nearly every coding agent harness now auto-compact context when a session nears its window limit: they summarize the conversation, discard the raw history, and keep going instead of dying at the wall. It reads as pure upside, shorter context, longer sessions, no configuration required. A closer look at the economics says otherwise. Summarizing rewrites the prefix the provider would otherwise serve from a cache at a 50 to 90 percent discount, so the very next turn re-pays full price for tokens that were already paid for once. One analysis puts the break-even at roughly $0.55 per million cached tokens, below which keeping the full, uncompacted history is the cheaper choice, not the more expensive one. A June 2026 paper measured the other half of the problem directly: compacting on a fixed token threshold, the default in most agent scaffolds, costs 30 to 70 percent more per question than letting the model decide when to compact itself, while scoring lower on the benchmarks that matter. This post breaks down when compaction saves money, when it quietly adds a second bill on top of the first, and what a decision-based trigger looks like to prototype.
The feature that looks free.
Claude Code's auto-compact is a good example because the trigger is public and precise: it fires when a session's token count crosses the context window minus roughly 33,000 tokens of reserved headroom, which works out to about 167,000 tokens on a 200K-token model. Past that line, the harness summarizes the conversation, extracting the files touched, the decisions made, and the state of the current task, and replaces the raw back-and-forth with that summary. The session keeps running instead of erroring out. Cursor, Windsurf, and most other agent products ship a version of the same idea, and this blog has already covered the eviction-and-paging approach some scaffolds use instead, pinning and evicting content without generating a summary at all.
Compaction, the generative kind, is the one worth pricing carefully, because the summarization step is itself an LLM call, and what it does to the turns that follow is not neutral.
Why the summary call isn't free.
Prompt caching works by matching a byte-identical prefix against what the provider already has stored. The moment a harness summarizes, compresses, or otherwise rewrites the history, the provider sees a new prefix. Every token in it gets billed at the full input rate, not the cached rate, on the very next call, and on every call after that until the prefix stabilizes again.
That matters because cache discounts are large. DeepSeek prices a cache hit at roughly $0.0028 per million tokens against a $0.14 standard rate, a 50x gap; Gemini's cached rate runs about 90% off list. The cache write tax already covered the asymmetric side of this: writing to cache can cost more than a plain input token depending on the provider and TTL. Compaction adds a second asymmetry on top: a summarization pass is a full rewrite, not a write extension, so it forfeits the discount on the entire history at once rather than paying a premium on the marginal new tokens.
The crossover point works out to a specific number: keeping full, uncompacted history wins on cost as long as the cached input rate is under roughly $0.55 per million tokens, a threshold most frontier and mid-tier providers clear today. Below that line, letting a session's history grow, paying full price only once per token and cache-hit price on every re-read after, beats summarizing it, even though summarizing sends fewer tokens on the wire.
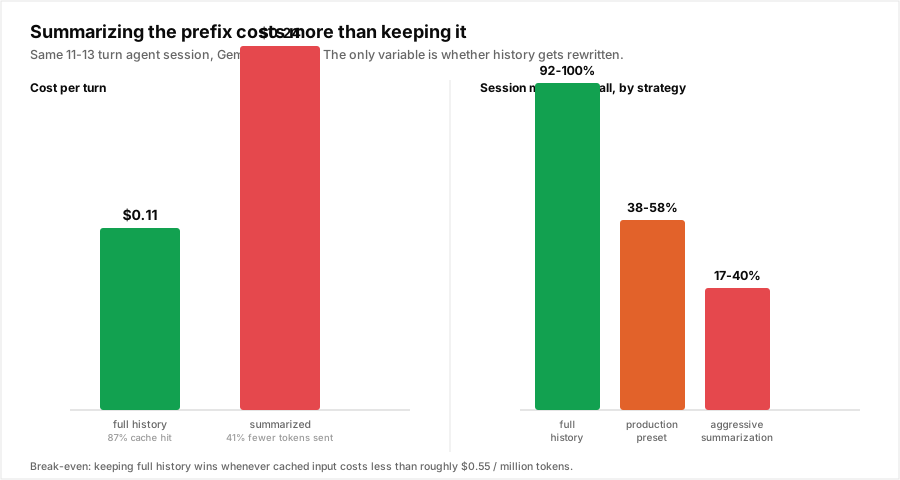
The recall numbers are the part a pure cost analysis misses. The summarization strategies in that comparison didn't just cost more per turn, despite sending fewer tokens, they also recalled less of the session correctly. The context rot research this blog has covered before found long context degrading model quality even without compaction; a lossy summary compounds that risk by construction, since whatever the summarizer judged unimportant is now permanently gone, not just harder to find.
What compaction actually costs, at real session scale.
None of this means compaction is always the wrong call, agent sessions do eventually exceed even a 1M-token window, and paying full price forever isn't an option either. It means the naive version of the feature, fire a summarization call whenever a counter crosses a line, is running against your bill in a direction most teams never measure.
A 50-turn coding session runs roughly 1 million input tokens against 40,000 output tokens, a ratio near 25:1, with input tokens dominating around 85% of total session cost. That input-heavy shape is exactly what a cache-invalidating compaction event taxes the hardest: a rewrite mid-session doesn't just cost tokens, it resets the cache-hit rate that was carrying most of that 85% at a discount.
| Model | Cost per 50-turn session | Annual, 25-engineer team at ~1,000 sessions/month |
|---|---|---|
| Premium flagship tier | ~$6.00 | ~$72,000 |
| Mid-tier frontier | ~$3.10 | ~$37,200 |
| Fast/budget tier | ~$1.80 | ~$21,600 |
| Efficient budget tier | ~$0.60 | ~$7,200 |
A roughly 10x spread between the top and bottom rows, before compaction strategy is even a variable, is the same lesson this blog's cost-stacking piece already made about optimization order: which model handles a session is usually a bigger lever than how its context gets managed. But a naive compaction trigger firing repeatedly across a long agentic session, the same sessions already shown to burn far more tokens than chat traffic, can turn a 10x model-choice gap into something worse on any tier, because a cache-invalidating rewrite taxes the expensive tier and the cheap tier by the same percentage.
The fix isn't "compact less," it's "compact on purpose."
A June 2026 paper from Johns Hopkins researchers, SelfCompact, tested the actual alternative to a fixed token threshold: let the model decide when to compact. The scaffold pairs two pieces, a compaction tool the model can call as an explicit action, and a lightweight rubric telling it when firing is safe, a sub-task has resolved, the trajectory is converging, and when to hold, mid-derivation, or stuck. The paper's own ablation makes the point sharply: the tool alone, without the rubric, gets invoked unevenly and often at the wrong moment; the rubric alone can't act without the tool. Neither works by itself.
Tested across six benchmarks in competitive math and agentic search, and seven models, with no fine-tuning required, decision-based compaction matched or beat fixed-interval summarization while using 30 to 70% less token cost per question, and it improved over a no-summarization baseline by up to 18.1 points on math and 5 to 9 points on agentic search, where fixed-interval compaction's quality gain over no summarization was smaller on the same tasks.
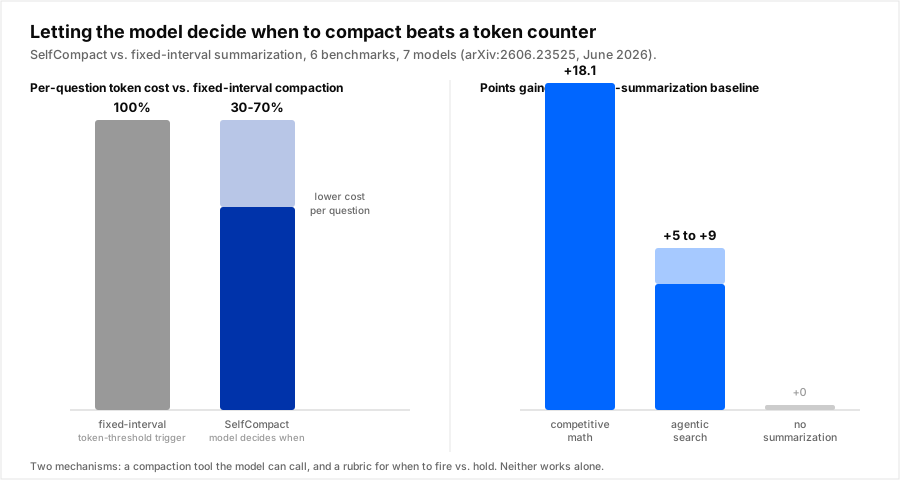
The mechanism behind the win is intuitive once it's named: a token counter has no idea whether the agent is mid-derivation or between sub-tasks. Firing compaction at a bad moment doesn't just cost a summarization call, it risks discarding partial work the agent then has to redo, paying for the same reasoning twice. The trajectory-reduction work this blog covered earlier made a version of the same point about filtering agent history mid-run: what gets cut matters as much as how much gets cut, and a rule that ignores task structure will occasionally cut the wrong thing.
A minimal version to prototype.
The full SelfCompact scaffold trains no new weights, it's inference-time only, a tool definition plus a rubric prompt. A stripped-down version worth trying first replaces the token-threshold trigger with a cheap classification call that checks whether the current point in the trajectory looks safe to compact, before falling back to the threshold as a hard ceiling.
from dataclasses import dataclass

@dataclass
class CompactionDecision:
    should_compact: bool
    reason: str

def safe_to_compact(trajectory_tail: str, classify) -> CompactionDecision:
    """classify: a cheap model call returning one of
    'resolved' | 'converging' | 'mid_derivation' | 'stuck'
    for the last few turns of the trajectory."""
    state = classify(
        f"Classify the state of this agent trajectory's last few turns "
        f"as resolved, converging, mid_derivation, or stuck:\n\n{trajectory_tail}"
    )
    if state in ("resolved", "converging"):
        return CompactionDecision(True, f"safe: trajectory is {state}")
    return CompactionDecision(False, f"hold: trajectory is {state}")


class DecisionGatedCompactor:
    """Wraps a hard token ceiling around a decision-based trigger, so a
    stuck-forever trajectory still compacts eventually instead of hitting
    the context limit uncompacted."""

    def __init__(self, hard_ceiling_tokens: int, classify, summarize):
        self.hard_ceiling = hard_ceiling_tokens
        self.classify = classify
        self.summarize = summarize

    def maybe_compact(self, token_count: int, trajectory_tail: str, full_history: str):
        decision = safe_to_compact(trajectory_tail, self.classify)
        forced = token_count >= self.hard_ceiling
        if decision.should_compact or forced:
            reason = decision.reason if decision.should_compact else "forced: hit hard ceiling"
            return self.summarize(full_history), reason
        return None, decision.reason  # keep the cached prefix, don't rewrite it
Two choices in that snippet carry the actual savings. First, classify should run on the cheapest model that reliably tells "resolved" from "mid-derivation" apart, not the same frontier model running the agent, since this call fires on every turn near the threshold, not once per compaction event. Second, the hard ceiling stays in place: a decision-based trigger that never fires on a genuinely stuck trajectory would eventually blow the context window, so the token threshold survives as a backstop, not the primary signal.
What this doesn't solve.
SelfCompact's benchmark suite is competitive math and agentic search, both domains with a relatively clean notion of "sub-task resolved" the rubric can key off of. A long-running production coding session mixes exploration, half-finished refactors, and genuinely ambiguous stopping points more than a benchmark trajectory does, and the paper is explicit that the tool alone is unevenly used across open-weight models, some call it too rarely, some at unhelpful moments, which is exactly why the rubric has to be paired with it rather than treated as a nice-to-have. The cache-economics side has its own caveat: the $0.55-per-million break-even point moves with provider pricing, and a team on a provider with an unusually cheap cache-write rate or an unusually short cache TTL will land on a different number than the one measured here.
What to check before you change your compaction strategy.
- Measure your own cache-hit rate before assuming compaction saves money. If a session is already running at 80%+ cache hits, as most multi-turn chat and coding traffic does, a fixed-interval compaction event is resetting a discount that was doing more work than the tokens it removes.
- Route the summarization call itself to a cheap, fast model, not the frontier model running the agent loop. The classification and summarization steps in the snippet above are exactly the kind of short, well-defined sub-task this blog's cascade-routing coverage argues shouldn't default to the same tier as the main reasoning task.
- Treat a re-derivation after compaction as a bug, not a fluke. If the agent redoes work it had already completed, the trigger fired at the wrong moment; that's a signal to move the threshold, not just retry.
- Keep a hard token ceiling as a backstop even after adding a decision-based trigger. A rubric that can hold indefinitely on a stuck trajectory needs a fallback that still fires before the context window does.
- **Nadir already routes classification and summarization sub-steps to the cheapest model that clears the bar**, on a live cost-quality signal per request, so a compaction trigger like the one above doesn't need its own separate model-selection logic to avoid running on the most expensive tier in the stack by default.
Conclusion.
Auto-compaction reads as a free win because it makes a hard limit disappear. The bill tells a more specific story: rewriting the prefix a provider was about to serve at a 50 to 90% discount forfeits that discount on the entire history at once, with a real break-even point, and a summarization trigger fired by a token counter instead of task structure costs 30 to 70% more per question than one the model decides for itself, while losing quality points in the process. Neither finding argues for never compacting. Both argue for treating the trigger as a decision with its own cost, measured against your own cache-hit rate and your own trajectory shape, instead of a threshold a harness ships by default and nobody revisits.
Sources: [Li, Zhang, Jurayj, Wang, Jin, Farajtabar, Nalisnick, Khashabi, "Self-Compacting Language Model Agents," arXiv:2606.23525, submitted June 22, 2026](https://arxiv.org/abs/2606.23525). [Claude Code documentation: context window and auto-compact](https://code.claude.com/docs/en/context-window). [Louis Bouchard, "Context Engineering in 2026: Why We Stopped Compacting Our Agent's Context"](https://www.louisbouchard.ai/context-engineering-2026/). [Vantage, "The Hidden Cost Driver in Agentic Coding Sessions in 2026"](https://www.vantage.sh/blog/agentic-coding-costs). [The Cache Write Tax](/blog/cache-write-tax-prompt-caching-cost). [The Missing L2: Context Window as Virtual Memory](/blog/context-window-virtual-memory-demand-paging). [Coding Agents Burn 1,000x More Tokens Than Chat](/blog/coding-agents-burn-1000x-tokens-research).