Update, 2 November 2026: this post first ran on September 23, when the GPT-6 family had no Terra model, and it said so. OpenAI shipped GPT-6.1 Terra on October 26 at $1 input, $0.05 cached input and $5 output per million tokens, and its GPT-6 Sol page now points to GPT-6.1 Sol as the newer Sol model. The price card, the ladder, the monthly bill and the migration plan below are updated. One correction: every GPT-6 model, not only Astra, bills prompts over 272K input tokens at a higher rate.
The GPT-6 lineup, with Terra back
OpenAI's GPT-6 API family runs from GPT-6 Luna at $0.10 input and $0.50 output per million tokens, through GPT-6.1 Terra at $1 and $5 and GPT-6.1 Sol at $2 and $10, to GPT-6 Astra at $10 and $50. On every one of them, a prompt over 272K input tokens is billed at 2x input and 1.5x output for the whole request. Source: OpenAI, GPT-6.1 Terra model page
The family arrived in three steps. GPT-6 Astra came first in early September. On September 22, OpenAI shipped GPT-6 Sol and GPT-6 Luna, both at half the promotional price of their GPT-5.6 predecessors. Source: OpenAI Developer Community Simon Willison called Luna "one of the cheapest models OpenAI have ever released". Source: Simon Willison
For five weeks there was no GPT-6 Terra. GPT-5.6 had three tiers, Sol, Terra and Luna, and the middle one had no successor. On October 26, OpenAI shipped GPT-6.1 Terra at half the price of GPT-6.1 Sol. Source: BleepingComputer The ladder has four rungs again.
This post covers the price card, what replaces each GPT-5.6 model, what the cuts do per task rather than per token, and a migration plan for each tier.
The price card
| Model | Input | Cached input | Output | Notes |
|---|---|---|---|---|
| GPT-6 Astra | $10.00 | $1.00 | $50.00 | Flagship |
| GPT-6.1 Sol | $2.00 | $0.10 | $10.00 | Newer Sol model. Fast mode 2x, Ultrafast 6x |
| GPT-6 Sol | $2.00 | $0.20 | $10.00 | Sept 22. OpenAI now points to GPT-6.1 Sol |
| GPT-6.1 Terra | $1.00 | $0.05 | $5.00 | New Oct 26 |
| GPT-6 Luna | $0.10 | $0.01 | $0.50 | Sept 22 |
| GPT-5.6 Sol (promo) | $4.00 | $0.40 | $20.00 | OpenAI lists the promo as available at least through Nov 21. List is $5 / $30 |
| GPT-5.6 Terra | $2.00 | $0.20 | $12.00 | Replaced by GPT-6.1 Terra |
| GPT-5.6 Luna | $0.20 | $0.02 | $1.20 |
USD per million tokens. GPT-6 prices come from OpenAI's model pages for Astra, GPT-6.1 Sol, GPT-6 Sol, GPT-6.1 Terra and Luna. GPT-5.6 prices as reported by Simon Willison and Codersera. Batch and Flex run at 50% of standard on GPT-6 Astra, Sol and Luna.
The 272K line applies to the whole family. Each GPT-6 and GPT-6.1 model page says prompts with more than 272K input tokens are "priced at 2x input and cache rates and 1.5x output for the full request." The 1.05M-token context window is real, but everything past 272K costs more, and the surcharge covers the first 272K tokens of that request too.
GPT-6 Sol and Luna both have a 128K-token output cap and keep reasoning_effort: "none", which Astra dropped. That matters for latency-sensitive calls that don't need to think.
GPT-5.6 Terra is dominated, and GPT-6.1 Terra replaced it
Put GPT-5.6 Terra next to the two models that can replace it:
| GPT-5.6 Terra | GPT-6 Sol | GPT-6.1 Terra | |
|---|---|---|---|
| Input | $2.00 | $2.00 | $1.00 |
| Cached input | $0.20 | $0.20 | $0.05 |
| Output | $12.00 | $10.00 | $5.00 |
| Generation | GPT-5.6 | GPT-6 | GPT-6.1 |
In September the story was that GPT-6 Sol matched GPT-5.6 Terra on input and cache and undercut it on output, so Terra was strictly dominated on price. Willison's verdict then: "any remaining reasons to use Terra just evaporated." That still holds for GPT-5.6 Terra. What changed is the replacement. GPT-6.1 Terra costs half of GPT-5.6 Terra on input, a quarter on cached input and 42% on output.
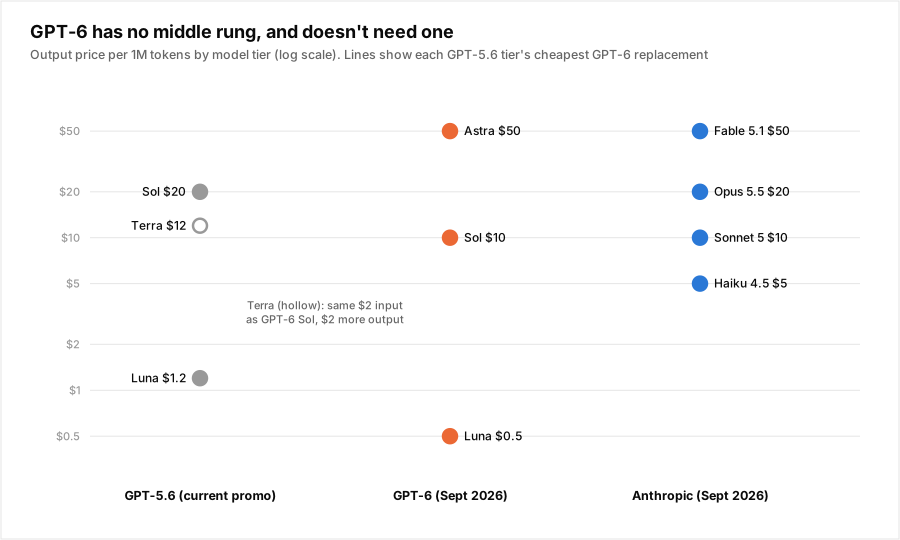
The chart shows the ladder as of September 23, before GPT-6.1 Terra and Anthropic's 5.5 models. OpenAI's ladder now has four rungs with uneven gaps:
- Luna → Terra is a 10x step on both input and output.
- Terra → Sol is a 2x step.
- Sol → Astra is a 5x step.
- Luna → Astra is 100x. One family, one API, two orders of magnitude.
Anthropic's current ladder is Claude Haiku 5.5 ($0.10 / $0.50), Sonnet 5.5 ($2 / $10), Opus 5.5 ($4 / $20) and Fable 5.1 ($10 / $50). Source: Anthropic pricing Two pairs now share list prices across the labs:
- GPT-6.1 Sol and Claude Sonnet 5.5: $2 input, $10 output and $0.10 cached input.
- GPT-6 Luna and Claude Haiku 5.5: $0.10 input, $0.50 output and $0.01 cached input, up to their thresholds. Haiku 5.5 bills 5x on every token once a prompt passes 100K tokens. Luna's line is at 272K, at 2x input and 1.5x output.
Price no longer separates those pairs. Quality on your workload does, along with where your prompts sit against each threshold. As our Fable 5.1 vs GPT-6 Astra comparison showed, when list prices match, the cache columns and the task mix decide the bill.
Per token vs per task
A 50% cut per token isn't a 50% cut per task. Newer models can use more or fewer tokens for the same job. Artificial Analysis's cost to run its Intelligence Index at the September launch, as reported by Codersera:
| Previous | GPT-6 | Change | |
|---|---|---|---|
| Sol, cost per Intelligence Index run | $1.99 (GPT-5.6 Sol) | $1.06 | −47% |
| Luna, cost per Intelligence Index run | $0.18 (GPT-5.6 Luna) | $0.07 | −61% |
| Sol, Intelligence Index | 47 | 48 | +1 |
| Luna, Intelligence Index | 37 | 37 | same |
So per task, Sol got cheaper by a little less than its price cut, and Luna by a little more. Luna isn't free of trade-offs, though: the same report put its output at about 51K tokens per run against 41K for GPT-5.6 Luna. That's more tokens, at a price low enough that the total still falls. Token price cuts don't automatically lower cost per task. Here they mostly did, but measure it on your own prompts.
The regressions are the other half. At launch, OpenAI's reported numbers put GPT-6 Sol 3.9 points below GPT-5.6 Sol on DeepSWE and 5.2 points below it on OSWorld 2.0, even as factual accuracy and deception rates improved. Source: Codersera Half the price for roughly the same model isn't the same thing as half the price for the same model on your hardest agentic tasks. Test GPT-6.1 Sol on those tasks before you assume the gap is closed.
What it does to a monthly bill
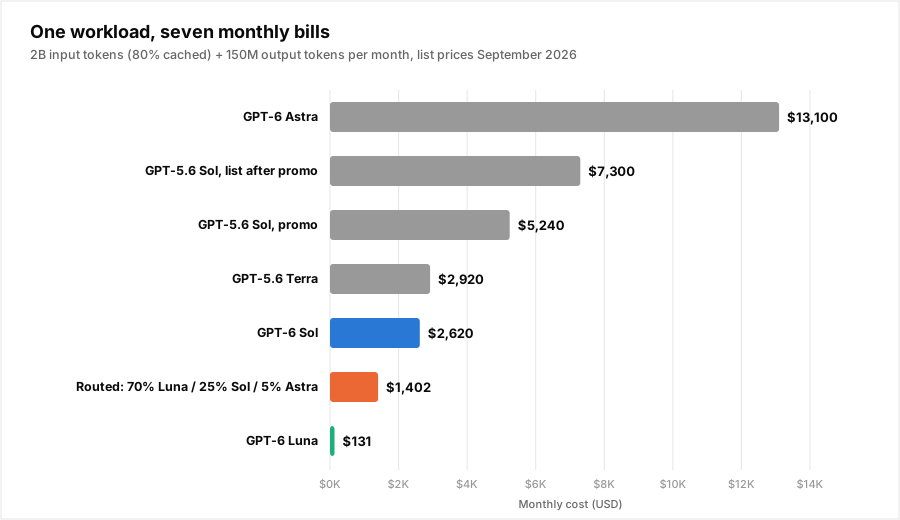
One workload: 2B input tokens a month, 80% served from cache, plus 150M output tokens. At list prices:
| Setup | Monthly cost |
|---|---|
| GPT-6 Astra | $13,100 |
| GPT-5.6 Sol, list price after the promo ends | $7,300 |
| GPT-5.6 Sol, promo | $5,240 |
| GPT-5.6 Terra | $2,920 |
| GPT-6 Sol | $2,620 |
| GPT-6.1 Sol | $2,460 |
| Routed: 70% Luna, 25% GPT-6 Sol, 5% Astra | $1,402 |
| GPT-6.1 Terra | $1,230 |
| GPT-6 Luna | $131 |
The chart predates the two GPT-6.1 rows. GPT-6.1 Terra is 400M uncached input at $1, plus 1.6B cached at $0.05, plus 150M output at $5: $400 + $80 + $750. GPT-6.1 Sol is $800 + $160 + $1,500.
Three takeaways:
- GPT-5.6 Terra → GPT-6.1 Terra saves 58% ($2,920 → $1,230). It's the biggest like-for-like saving in the table. Whether the new Terra handles your traffic is a quality question, so shadow-test it.
- Staying on GPT-5.6 Sol is the expensive mistake. $5,240 on the promo, and $7,300 once it ends. GPT-6.1 Sol does the same job for $2,460.
- A single Terra default now undercuts the old three-rung mix. GPT-6.1 Terra alone costs less than the routed Luna, Sol and Astra mix. Routing still pays when a large share of traffic fits on Luna, which is 10x cheaper than Terra, and when the hard tail needs Sol or Astra. Your split is a measurement, not a guess.
Migration plan by tier
| If you run… | Move to | Watch for |
|---|---|---|
| GPT-5.6 Terra | GPT-6.1 Terra | Half the input price. Shadow-test quality and keep GPT-6.1 Sol as the escalation target |
| GPT-5.6 Sol | GPT-6.1 Sol | GPT-6 Sol trailed GPT-5.6 Sol on DeepSWE and OSWorld at launch. Test hard agentic steps, and keep Astra as the escalation target |
| GPT-6 Sol | GPT-6.1 Sol | Same input and output price, half the cached-input price |
| GPT-5.6 Luna | GPT-6 Luna | Longer outputs. Cap max_output_tokens and measure cost per task, not per token |
| One model as a "safe default" for everything | Luna + Terra + Sol + Astra, routed | Needs a routing decision per request |
GPT-6.1 Terra makes a single default workable again: it's cheap enough that many teams can run everything on it and escalate by hand. The gaps around it are the reason to route anyway. Traffic Luna can handle costs a tenth as much, and traffic that needs Sol or Astra fails quietly on Terra.
Don't swap models on price alone. Mirror a slice of production traffic to the new model first and compare. We've written up that shadow-testing and canary pattern:
import random
from openai import OpenAI

client = OpenAI()
MIGRATION = {
    "gpt-5.6-terra": "gpt-6.1-terra",
    "gpt-5.6-sol": "gpt-6.1-sol",
    "gpt-6-sol": "gpt-6.1-sol",
    "gpt-5.6-luna": "gpt-6-luna",
}

def call(model: str, messages: list, shadow_rate: float = 0.05):
    primary = client.chat.completions.create(model=model, messages=messages)
    candidate = MIGRATION.get(model)
    if candidate and random.random() < shadow_rate:
        shadow = client.chat.completions.create(model=candidate, messages=messages)
        log_pair(model, candidate, primary, shadow)  # compare quality, tokens and cost offline
    return primary
Log the usage block from both calls, not just the answers. The per-task cost difference, including Luna's longer outputs, is the number that decides the migration.
Where Nadir fits
Nadir decides, per request, which tier a prompt needs: simple, medium or complex, with a confidence score. You map tiers to the models you run, for example Luna for simple, Terra or Sol for medium and Astra for complex. When a lineup changes the way this one did twice in five weeks, you remap tiers to models instead of rewriting every call site that hardcoded gpt-5.6-terra. Hardcoded model names and prices are the trap that turns a price cut into a migration project.
Checklist
- Move off GPT-5.6 Terra. GPT-6.1 Terra costs half as much on input and 42% as much on output. Shadow-test, then switch.
- Don't stay on GPT-5.6 Sol for the promo. OpenAI lists it as available at least through November 21, and GPT-6.1 Sol is already about half the promo price.
- Check where your prompts sit against 272K. Every GPT-6 model bills the whole request at 2x input and 1.5x output past that line.
- Measure per task, not per token. Especially on Luna, where outputs got longer.
- Keep an escalation path for hard agentic work. GPT-6 Sol trailed on DeepSWE and OSWorld at launch. Astra is 5x Sol, not 50x, so escalating the hard tail is affordable.
- Route across the gaps. Luna-eligible traffic is where the biggest saving is. Find out how much of yours qualifies.
The GPT-6 lineup is cheaper than GPT-5.6 on every rung, and its gaps are uneven: 10x, then 2x, then 5x. That rewards teams that decide per request. Start free to put a routing decision in front of your OpenAI traffic, or read the complete guide to cutting LLM API costs.
Related reading
- LLM API pricing across every major provider, updated monthly.
- Fable 5.1 vs GPT-6 Astra: same list price, 57% apart on an agent bill.
- Shadow testing and canary rollouts for model swaps.
- Token price cuts don't lower agent cost per task.
- The 72-hour model deprecation problem.
- Reasoning effort and thinking budgets across providers.