Two $10 models, two different bills
The frontier tier now has two models at exactly the same list price. Claude Fable 5.1 shipped on September 1 at $10 per million input tokens and $50 per million output. Source: Anthropic, Pricing GPT-6 Astra lists at the same $10 in and $50 out. Source: OpenAI, GPT-6 Astra model page Any comparison table built from those two columns calls it a tie.
It isn't, and the difference sits in a column most comparison tables leave out. Fable 5.1 bills cache reads at $0.25 per million, 2.5% of its input price and 75% below Fable 5's $1.00. Astra bills cached input at $1.00, the 10% ratio the whole industry has used since prompt caching launched. Anthropic's own estimate is that the cut lowers Fable 5.1's effective cost by around 25% on typical workloads and by as much as 45% on highly agentic ones. Source: VentureBeat
Agents spend most of their input on cache reads, so for agent traffic that is the column that matters. This post works through the same agent session on both $10 models, then on Anthropic's cheaper tiers. It found three things:
- Same list price, 57% apart on the bill. On a 40-turn agent session, Astra costs $6.47 and Fable 5.1 costs $4.13.
- The gap between cheap and expensive models has mostly closed on cached input. A cached token costs $0.25 on Fable 5.1 and $0.20 on Sonnet 5. On list price they're 5x apart.
- A cheaper model can make one turn cost more. On turn 30 of a warm Fable 5.1 session, sending a single step to Haiku 4.5 costs 36% more than staying put. Sending it to Sonnet 5 costs 2.7x more.
The price card that matters for agents
| Model | Input | Cache write (5 min) | Cache read | Read / input | Output |
|---|---|---|---|---|---|
| Claude Fable 5.1 | $10.00 | $12.50 | $0.25 | 2.5% | $50.00 |
| GPT-6 Astra | $10.00 | $12.50 | $1.00 | 10% | $50.00 |
| Claude Fable 5 | $10.00 | $12.50 | $1.00 | 10% | $50.00 |
| Claude Opus 5.5 | $4.00 | $5.00 | $0.20 | 5% | $20.00 |
| Claude Sonnet 5 | $2.00 | $2.50 | $0.20 | 10% | $10.00 |
| Claude Haiku 4.5 | $1.00 | $1.25 | $0.10 | 10% | $5.00 |
All prices are USD per million tokens at list rates, September 2026. Anthropic's rates come from its pricing page, and Astra's from OpenAI's model page, which also lists a $12.50 cache-write rate and a surcharge on prompts over 272K tokens. Sonnet 5 is listed at $2/$10: the increase to $3/$15 that was scheduled for September 1 was cancelled, a trap this blog covered when it was announced.
Fable 5 and Astra match on every column of this table. Fable 5.1 changed only the cache-read column, and that is enough to change which model is cheaper for agents.
The session: 40 turns, one agent
The worked example is a typical coding or research agent loop:
- a 20K-token prefix (system prompt, tool schemas, project context)
- 3K tokens of new context per turn (tool results, file reads, the user's follow-up)
- 800 output tokens per turn
- 40 turns, each turn well inside the 5-minute cache window
Each turn reads the previous turn's prefix from cache and writes the new 3K to cache. Across the session that comes to 3.12M cache-read tokens, 140K cache-write tokens and 32K output tokens. Cache reads make up 95.7% of all input, which is normal for agents. An agent's prompt grows every turn, so most of each prompt is history the provider has already seen.
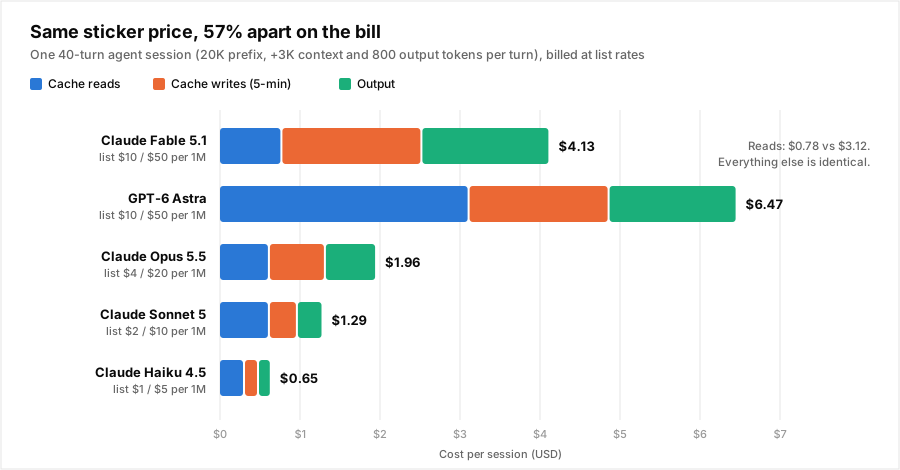
| Model | Cache reads | Cache writes | Output | **Session total** | Uncached (no caching) |
|---|---|---|---|---|---|
| Claude Fable 5.1 | $0.78 | $1.75 | $1.60 | $4.13 | $34.20 |
| GPT-6 Astra | $3.12 | $1.75 | $1.60 | $6.47 | $34.20 |
| Claude Opus 5.5 | $0.62 | $0.70 | $0.64 | $1.96 | $13.68 |
| Claude Sonnet 5 | $0.62 | $0.35 | $0.32 | $1.29 | $6.84 |
| Claude Haiku 4.5 | $0.31 | $0.18 | $0.16 | $0.65 | $3.42 |
On list prices alone the two $10 models look identical. On the bill Astra costs 57% more, because the cache-read segment is the only one that differs. Two more details are easy to miss:
- On Fable 5.1, cache writes now cost more than cache reads. Cache writes are $1.75 of the session and reads are $0.78. On a 10% read model it's the other way round. At 2.5%, the new tokens you write each turn cost more than the history you re-read.
- Output is now Fable 5.1's biggest cost. It's 39% of the Fable session, against 25% on Astra. When cached input gets this cheap, what the model writes counts for more of the bill than what it reads.
What "$10 per million input" really costs
List input price describes a request with no cache hits, which agents almost never send. What an agent actually pays per input token is a blend: reads at the read rate, plus new tokens at the write rate. It depends almost entirely on your cache hit rate.
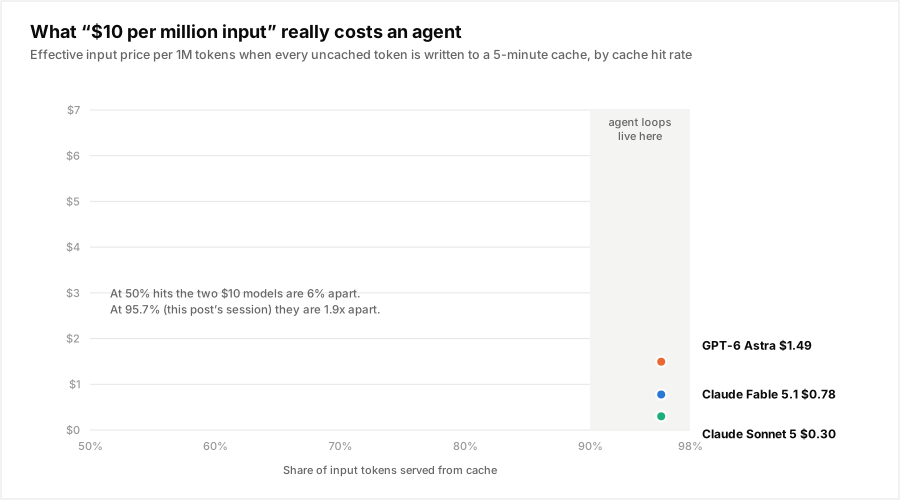
At a 50% hit rate the two $10 models are 6% apart, and the cheaper cache reads barely matter. At the 90-98% hit rates agent loops actually run at, the gap grows to about 2x. The discount pays off in proportion to how much of your traffic is long, warm sessions. A support bot answering one-shot questions sees almost none of it. A coding agent in a 40-turn loop sees most of it. That's why Anthropic quotes a range, around 25% typical and up to 45% agentic, rather than one number.
The model tiers are closer together on cached input
This is the part with consequences for routing. Here is the price gap between the top and bottom of Anthropic's lineup, token type by token type:
| Token type | Fable 5.1 | Sonnet 5 | Fable vs Sonnet |
|---|---|---|---|
| Uncached input | $10.00 | $2.00 | 5.0x |
| Cache write (5 min) | $12.50 | $2.50 | 5.0x |
| Cache read | $0.25 | $0.20 | 1.25x |
| Output | $50.00 | $10.00 | 5.0x |
The 5x gap that makes downrouting worth it still applies to output, uncached input and cache writes. On cache reads, the token type agents consume most of, the gap is now 1.25x. Opus 5.5 reads at $0.20 too, the same as Sonnet 5.
So a router that compares list prices will overestimate what it saves on warm agent turns. Across the whole session, Fable 5.1 costs 3.2x as much as Sonnet 5 ($4.13 vs $1.29), not the 5x the list prices suggest. Downrouting still saves money. The savings are just in different places now.
The cheaper model can cost more for one turn
Prompt caches belong to one model. Switch models in the middle of a session and the new model has no copy of the prefix. It has to take the whole prompt in again at full price, or write it to a fresh cache at 1.25x. This blog has priced that switch penalty before. Fable 5.1 makes it much bigger, because what you give up by leaving is a 97.5% discount rather than a 90% one.
Here's turn 30 of the same session: a 107K-token cached prefix, 3K of new context, 800 output tokens.
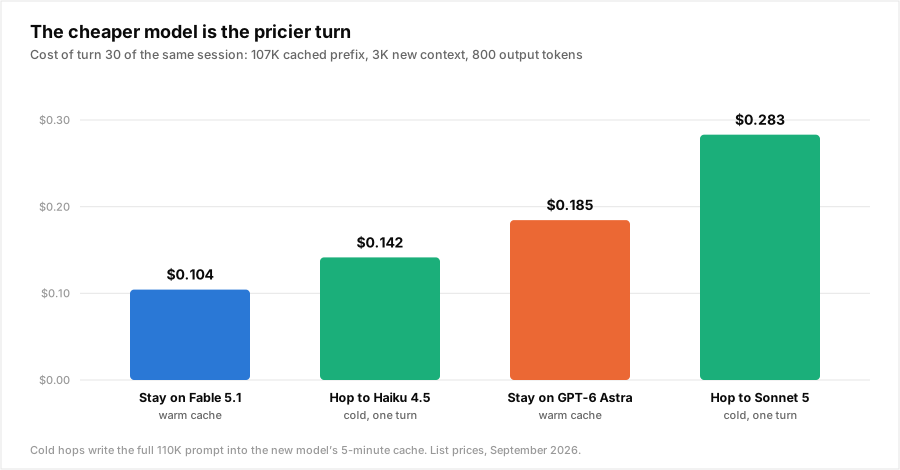
The warm turn on Fable 5.1 costs $0.104. The same turn sent cold to Haiku 4.5, a model with one tenth of Fable's list price, costs $0.142. Sent cold to Sonnet 5 it costs $0.283, 2.7x more than not switching. Using the cheaper model makes that one turn more expensive.
That doesn't make switching wrong. It makes switching for a single step wrong. What matters is how many turns you'll stay on the cheaper model:
| Switch at turn 30 | Switch turn vs staying | Turns needed to break even |
|---|---|---|
| Fable 5.1 → Sonnet 5 | $0.283 vs $0.104 | 4 |
| Fable 5.1 → Haiku 4.5 | $0.142 vs $0.104 | 2 |
| GPT-6 Astra → Sonnet 5 | $0.283 vs $0.185 | 2 |
| GPT-6 Astra → Haiku 4.5 | $0.142 vs $0.185 | 1 (wins immediately) |
On Astra, the old 10% read ratio, a switch to Haiku pays for itself on the first turn. On Fable 5.1, a switch to Sonnet needs to stay for four turns. Commit to Sonnet 5 for the last 11 turns of the session and you pay $0.69 instead of $1.19, so the switch still wins. The same change for a single turn loses. The cheaper cache reads doubled the number of turns a switch must last before it pays off.
Where routing still saves money in September 2026
None of this makes model routing less valuable. It changes where the savings are:
- Session boundaries. A new session or a new task has no warm cache to lose. The first request is the cheapest point to pick a model, because the choice is locked in by the cache from turn 2 onwards.
- Subagents and fresh-context branches. A subagent that starts with a clean prompt, such as a search worker or a file summarizer, has no cache to protect. Send it to the cheapest model that can do the job. Multi-agent systems create a lot of these.
- Output-heavy steps. Output is still priced 5x apart between tiers, and on Fable 5.1 it's the biggest single cost. A step that writes 4K tokens of code or a long report is where the tier gap is largest.
- One-shot traffic. Classification, extraction, short chat replies. With hit rates near zero, the effective price is the list price and the full 5-10x tier gap applies.
- Long runs on a cheaper model. If a session has reached a routine phase, like applying the same fix to 30 files, switching once and staying there is worth it. Switching back and forth turn by turn isn't.
The mistake is treating routing as a per-request choice between list prices. Every routing decision is now also a caching decision, and the cheaper reads get, the more a router that ignores caching costs you.
Tutorial: work out your effective price from your own logs
You don't need our session model. Your API responses already contain the numbers. Anthropic splits every request's input into input_tokens (uncached), cache_creation_input_tokens (writes) and cache_read_input_tokens (reads). OpenAI reports cached input under prompt_tokens_details.cached_tokens in Chat Completions, or input_tokens_details.cached_tokens in the Responses API.
# Effective price per model from logged usage blocks. Prices in USD / 1M tokens.
PRICES = {
    "claude-fable-5-1": {"in": 10.0, "write": 12.50, "read": 0.25, "out": 50.0},
    "gpt-6-astra":      {"in": 10.0, "write": 12.50, "read": 1.00, "out": 50.0},
    "claude-sonnet-5":  {"in": 2.0,  "write": 2.50,  "read": 0.20, "out": 10.0},
    "claude-haiku-4-5": {"in": 1.0,  "write": 1.25,  "read": 0.10, "out": 5.0},
}

def split_usage(provider: str, u: dict) -> dict:
    """Normalize one response's usage block to uncached / write / read / output."""
    if provider == "anthropic":
        return {
            "in": u.get("input_tokens", 0),
            "write": u.get("cache_creation_input_tokens", 0),
            "read": u.get("cache_read_input_tokens", 0),
            "out": u.get("output_tokens", 0),
        }
    # OpenAI Chat Completions. Anything not served from cache is billed at the
    # write rate here, the conservative reading of Astra's $12.50 write price.
    cached = (u.get("prompt_tokens_details") or {}).get("cached_tokens", 0)
    return {
        "in": 0,
        "write": u.get("prompt_tokens", 0) - cached,
        "read": cached,
        "out": u.get("completion_tokens", 0),
    }

def effective_prices(rows):
    """rows: iterable of (model, provider, usage_dict). Returns a per-model report."""
    agg = {}
    for model, provider, usage in rows:
        a = agg.setdefault(model, {"in": 0, "write": 0, "read": 0, "out": 0})
        for k, v in split_usage(provider, usage).items():
            a[k] += v
    report = {}
    for model, t in agg.items():
        p = PRICES[model]
        input_tokens = t["in"] + t["write"] + t["read"]
        input_cost = (t["in"] * p["in"] + t["write"] * p["write"] + t["read"] * p["read"]) / 1e6
        output_cost = t["out"] * p["out"] / 1e6
        report[model] = {
            "hit_rate": t["read"] / max(input_tokens, 1),
            "effective_input_per_m": input_cost / max(input_tokens, 1) * 1e6,
            "list_input_per_m": p["in"],
            "output_share": output_cost / max(input_cost + output_cost, 1e-9),
            "total_usd": input_cost + output_cost,
        }
    return report
Run it over a week of production logs and look at three numbers per model:
- `hit_rate`. Below about 80% and the 2.5% read price hardly matters for you. Fix cache stability first: anything that rewrites the prefix turns reads back into writes.
- `effective_input_per_m` against `list_input_per_m`. This is your real input price. On a healthy agent it should be 5-15% of the list price.
- `output_share`. Above about 35% and output tokens are the biggest cost. Shorter outputs and routing output-heavy steps to a cheaper model will save more than any input-side trick.
One caveat for comparing across vendors: tokenizers differ. Anthropic notes that Claude 4.7 and later models produce roughly 30% more tokens for the same text than earlier Claude models. We've covered what that does to per-task cost. The fair comparison is the effective price multiplied by how many tokens each model uses for your prompts, which is what total_usd above measures from real traffic.
Getting a cache-aware routing decision from Nadir
Nadir's decision endpoint takes the session's cache state as an input, so the router weighs the cost of losing a warm cache against what it would save on the cheaper model. It uses each model's own cache-read rate rather than assuming a flat 10%, which is the difference between a correct and an incorrect answer on Fable 5.1:
curl https://api.getnadir.com/v1/recommend \
  -H "X-API-Key: $NADIR_API_KEY" \
  -d '{
    "prompt": "Rename the helper and update its two call sites.",
    "cache_state": {
      "model": "claude-fable-5-1",
      "cached_tokens": 107000,
      "ttl": "5m",
      "expected_remaining_turns": 1
    }
  }'
With one turn left, the answer is to stay on the warm model even though a cheaper model could handle the prompt. With a dozen turns left, the answer is to switch now. The response includes both projected costs and the reason for the decision, so you can audit the call instead of taking it on trust. The same cache-read and cache-write breakdown appears per model in the dashboard's cost view. If you're choosing between Fable 5.1 and Astra for an agent product, that breakdown answers the question with your own traffic.
Checklist
- Add a cache-read column to your model comparison sheet. Blended prices that leave it out were reasonable when every model read cache at 10% of input. They aren't any more.
- Estimate cost at your own hit rate, not at list price. The two $10 models are 6% apart at 50% hits and about 2x apart at 96%.
- Pick models at session boundaries, not step by step. On a 2.5%-read model, a switch needs to last several turns before it pays off.
- Send fresh-context work to cheaper models. Subagents, one-shot calls and new sessions have no cache to lose.
- Keep an eye on output. When input gets this cheap, output becomes the biggest cost, and it's still priced 5x apart between tiers.
- Recompute when prices change. Cache-read rates now vary by model, by generation and by vendor. A router with hardcoded prices will be wrong after the next price change.
List prices were never the full story for agents, and September made the gap large enough to change which model is cheaper. Price the cache-read column alongside the other two and route with it. Start free, or read the complete guide to cutting LLM API costs for the rest of the stack.
Related reading
- Every routing decision is also a cache decision: the prompt-cache switch penalty.
- The cache-write tax: when the 1.25x premium doesn't pay for itself.
- Pay to Forget: Claude context editing and the cache-write bill.
- The Overcaching Tax: caching strategy for agent loops.
- Four Prices, One Model: the service-tier price ladder.