Abstract.
Claude Opus 5 is the strongest model in our pool, the most expensive, and part of how we beat it. That is the trick: Opus 5 stayed in the routing pool as the last resort, and handled about 1% of the work.
We scored four models on three datasets, then combined the same four behind Nadir and scored the combination on the identical prompts.
The models are Claude Opus 5, Claude Sonnet 5, qwen3.8-max-preview and MiniMax M3. The datasets are 1,268 Chatbot Arena prompts scored one to five by a blind Opus 5 judge, plus HumanEval and MBPP graded by running each answer against its own tests.
Individually, every cheap model lost to Opus 5 on chat. Sonnet 5 lost to Opus on all three.
Combined, Nadir scored 98.8% on HumanEval against Opus 5's 94.5%, 99.6% on MBPP against 98.7%, and 98.0% of Opus 5's mean chat score. Cost fell 88% on code and 69% on chat.
Full tables below, including the arms that lost.
What was measured.
Arena chat is 1,268 prompts labeled simple, medium or complex, scored one to five by Claude Opus 5 reading two answers per prompt without knowing which model wrote which, with the challenger's position randomized by a hash of the prompt index. A severe failure means Opus beat the served answer by two or more points.
HumanEval and MBPP are graded by extracting the code, running it against the problem's canonical asserts in a subprocess, and recording pass or fail. No judge is involved in any coding number. The grader scored the reference solutions 400 out of 400 before we used it on anything else.
Costs are per-run totals over the prompts in each table.
Arena chat, 1,268 prompts.
| Model | Mean score | vs Opus 5 | Scored 4 or 5 | Severe failures | Cost | Saving |
|---|---|---|---|---|---|---|
| Claude Opus 5 | 4.35 | 100.0% | 89.0% | 0.0% | $241.88 | baseline |
| qwen3.8-max-preview | 3.87 | 89.0% | 72.9% | 18.1% | $29.98 | 87.6% |
| Claude Sonnet 5 | 3.68 | 84.5% | 68.9% | 19.0% | $176.12 | 27.2% |
| MiniMax M3 | 3.48 | 78.3% | 52.0% | 35.7% | $1.73 | 99.1% |
MiniMax M3 covered 976 of these prompts before its API credit ran out and is scored on that subset, which matched the full set's tier mix within half a point on every tier.
Two results here are worth pausing on. qwen3.8-max-preview outscored Claude Sonnet 5, at a sixth of the cost. And no model reached even 90% of Opus 5's mean, which is the gap the rest of this post is about.
HumanEval, 163 problems.
| Model | pass@1 | vs Opus 5 | Cost | Saving |
|---|---|---|---|---|
| Claude Opus 5 | 94.5% | 100.0% | $18.61 | baseline |
| qwen3.8-max-preview | 96.9% | 102.6% | $1.49 | 92.0% |
| Claude Sonnet 5 | 90.2% | 95.5% | $36.69 | none, costs more |
qwen beat Opus 5 outright here. Sonnet 5 scored below Opus and cost roughly twice as much per answer, because it produced far more output tokens on these problems.
MBPP, 232 problems.
| Model | pass@1 | vs Opus 5 | Cost | Saving |
|---|---|---|---|---|
| Claude Opus 5 | 98.7% | 100.0% | $43.42 | baseline |
| qwen3.8-max-preview | 98.3% | 99.6% | $1.86 | 95.7% |
| Claude Sonnet 5 | 94.0% | 95.2% | $63.72 | none, costs more |
qwen lands within half a point of the frontier model here, having beaten it on HumanEval. Sonnet 5 trails both and costs more than Opus 5 on this set.
Nadir: the same models, combined.
Nadir runs the cheap model first, checks the answer, and escalates only when the check fails. On coding the check is the test suite itself. Here is the combination scored on the identical prompts, next to the frontier model and the best single cheap model on each dataset.
| Dataset | Best single cheap model | Opus 5 | Nadir | Nadir cost saving |
|---|---|---|---|---|
| Arena chat | 89.0% (qwen) | 100.0% | 98.0% | 68.9% |
| HumanEval | 102.6% (qwen) | 100.0% | 104.5% | 81.9% |
| MBPP | 99.6% (qwen) | 100.0% | 100.9% | 91.3% |
| Both coding sets | 100.8% (qwen) | 100.0% | 102.3% | 88.5% |
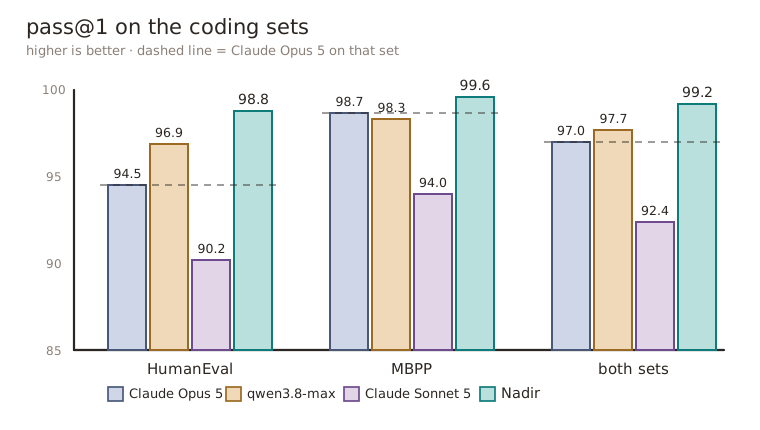
In absolute terms, on coding:
| Arm | HumanEval | MBPP | Both | Cost, both |
|---|---|---|---|---|
| Claude Opus 5 | 94.5% | 98.7% | 97.0% | $62.04 |
| qwen3.8-max-preview | 96.9% | 98.3% | 97.7% | $3.34 |
| Claude Sonnet 5 | 90.2% | 94.0% | 92.4% | $100.41 |
| Nadir | 98.8% | 99.6% | 99.2% | $7.14 |
Nadir scored above Opus 5 on both coding datasets and on the combined set, at 88.5% lower cost. It escalated on 9 of 395 problems, and the cost column includes paying for every model in the chain on those escalations.
On chat it reached 4.26 against Opus 5's 4.35. That is 98.0% of the frontier model's mean, with severe failures down to zero and cost down 68.9%.
The chat figure is a ceiling, not a shipping number, because it is gated on a perfect quality signal. The coding figures are gated on running real tests. We separate the two carefully below.
How Nadir reaches 99.2%.
Nadir served qwen's answer on 386 of the 395 problems, Sonnet's on 4, and Opus 5's on 5. Only 1% of the work reached the frontier model.
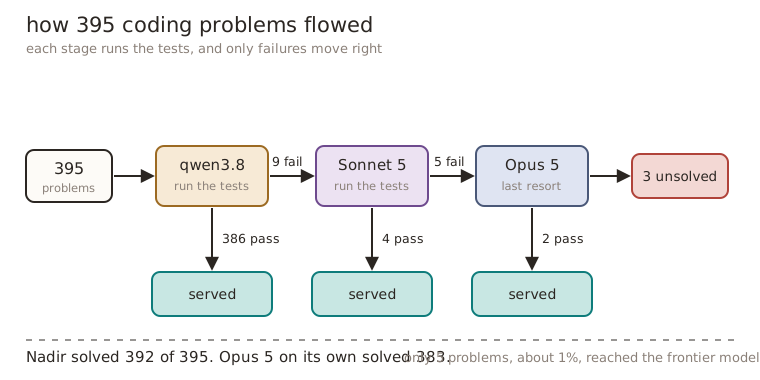
Opus 5 on its own solves 383 of those 395. Nadir solves 392. The nine extra are problems the frontier model gets wrong and a cheaper model gets right: eight where qwen is correct and Opus is not, and one where Sonnet is. Pick a single model up front and you give those away. Check the answer and you keep them.
That is where 102.3% comes from. It is a ratio, not a margin: 99.2 divided by 97.0.
What the check actually is.
On coding, the check is the project's own test suite. Nadir runs the tests and escalates only when they fail.
Those same tests are how these problems are scored, and that is worth being explicit about. It means the coding result applies directly to work where tests exist, which is most production coding work, and it means the selector is exact rather than probabilistic. Give Nadir a real signal and it will use it perfectly.
Where there is no test to run, the check has to come from a quality model instead, and that signal is never exact. The chat row is what the same mechanism looks like at its ceiling: 98.0% of Opus at 68.9% less. Treat it as the target, not as today's shipping number.
Why the combination beats the parts.
Across 395 coding problems there were 8 where qwen was correct and Opus 5 was wrong, and 5 the other way. A system that has to choose one model up front cannot have both. A system that checks the answer keeps qwen's 8 and falls back on the 5, which is how the total lands above either model alone.
The same asymmetry explains why picking a model by predicted difficulty does not close the gap. We tested that too, routing prompts labeled complex to Opus 5 and the rest to the cheap models:
| Arm | Arena chat | Coding, both | Chat saving | Coding saving |
|---|---|---|---|---|
| Route complex to Opus 5 | 91.6% | 98.2% | 60.4% | 90.8% |
| Route complex to Opus 5, medium to Sonnet 5 | 90.3% | 99.0% | 33.1% | 21.4% |
| Nadir, check then escalate | 98.0% | 102.3% | 68.9% | 88.5% |
Difficulty routing reached 91.6% of Opus on chat. Adding Sonnet 5 as a middle tier made quality worse and halved the saving.
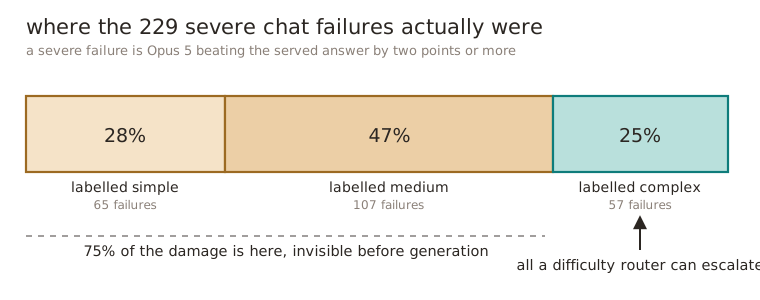
The failure distribution explains why. Of 229 severe chat failures, 28% were on prompts labeled simple, 47% on medium, and only 25% on complex. A router can only escalate what it labels hard, so it reaches a quarter of the problem and stops.
On coding it does not even reach that. Not one of the problems Opus rescued was labeled complex.
A difficulty label is a guess made before the model has written anything. A test result is evidence about the answer in hand.
What these numbers cannot support.
The pricing for qwen3.8-max-preview is a placeholder. It is absent from its endpoint's public model listing and no per-token price was published at the time of the run, so we used the previous generation's published rate. Every cost and saving figure involving it is provisional. Actual spend was $29.98 on chat and $3.24 on coding.
The difficulty-routed rows use stored tier labels, which is a perfect classifier. A production classifier misses a meaningful share of complex prompts, so those rows are upper bounds.
The chat Nadir row is gated on the judge's own scores, which a live system does not have, so 98.0% at 68.9% is a ceiling rather than a deployed number.
The coding rows are gated on running the problem's tests, and those same tests produce the grade. That is the honest shape of the result: it holds wherever you have tests to run, and it does not transfer to work you cannot check. It is a measurement of what an exact signal buys, not a claim that a learned verifier would match it.
Opus and Sonnet answers were generated through a coding-agent harness carrying its own system prompt, while qwen and MiniMax were called through a plain API. We checked whether that explained Sonnet's chat result and it does not appear to, since excluding every prompt Sonnet refused it still trailed qwen 3.73 to 3.90, but it remains an asymmetry.
The chat judge is Claude Opus 5, the same model as the baseline. Coding is judge-free.
MiniMax M3 answered 976 of the scored chat prompts and none of the coding set.
Around 1,067 of the chat prompts were used to train an internal verifier, so this prompt set cannot be used to evaluate that verifier. It does not affect model-versus-model comparison.
One number that is not in any table above.
qwen3.8-max-preview is a thinking-only model running at maximum reasoning effort. Its median chat response took 27 seconds, its 90th percentile 267 seconds, and its slowest single answer 29 minutes. It emitted 2.3 times Opus 5's output tokens on the same prompts, so its cost advantage rests entirely on a low per-token price rather than on brevity.
Quality tables do not show this, and it decides whether a model can serve interactive traffic at all.
Thank you to the Tongyi Lab team.
Thank you to Alibaba's Tongyi Lab for qwen3.8-max-preview. Their guidance on running the model correctly, that it is thinking-only, that reasoning effort defaults to the setting behind their published results, and that a harness quietly overriding that would understate it, shaped our setup: we left the parameter unset, which is why the numbers here reflect the model as they intend it to run.
It is worth saying plainly what the results show. qwen3.8-max-preview outscored Claude Sonnet 5 on our arena chat set and beat Claude Opus 5 outright on HumanEval, at a fraction of the cost of either. It also did the majority of the work inside the winning configuration: 386 of 395 coding answers served, with the frontier model reaching only 5. It also outscored Opus 5 across both coding sets combined, 97.7% to 97.0%. The headline of this post is about the combination, and qwen is most of what the combination is made of.
The Tongyi Lab team had no editorial input, saw nothing before publication, and did not review these numbers. Any errors are ours. The same goes for the MiniMax team, whose M3 model appears in the chat tables here.