The paper that quietly changes a GPU's math
On March 24, 2026, Google Research published TurboQuant, a method that compresses an LLM's key-value cache down to 3 bits per coordinate with no retraining, no calibration dataset, and no accuracy loss reported on its benchmarks. Source: Google Research, "TurboQuant," accepted to ICLR 2026. It combines PolarQuant, a rotation-based coordinate transform, with a 1-bit QJL residual correction, and runs data-obliviously: no learned codebooks, no second-order statistics, no preprocessing pass over the sequence. Each key and value vector gets quantized the instant it's produced. The headline numbers are at least 6x less KV-cache memory and up to 8x faster attention-logit computation on an NVIDIA H100 at 4-bit, landing within roughly 2.7x of the information-theoretic compression limit.
Independent ports showed up within weeks, not years: a llama.cpp discussion thread tracking an implementation, and separate GitHub projects wiring TurboQuant into vLLM. That's the tell that this isn't a benchmark curiosity sitting in a paper PDF. It's heading into the serving engines teams already run.
The distinction worth being precise about: this is not prompt caching. The Cache Write Tax already covered how DeepSeek, OpenAI, and Anthropic price a repeated prefix — that's about whether the same request shows up twice inside a cache window. TurboQuant compresses the KV cache every session accumulates regardless of repetition: the per-token memory a GPU holds just to keep one conversation or one agent loop alive while it runs. A brand-new, never-repeated 150K-token agent session gets zero benefit from prompt caching and the full benefit of TurboQuant.
Why a GPU runs out of memory before it runs out of FLOPs
Self-hosted serving has a batch-size ceiling that most cost conversations skip past. A GPU's compute (FLOPs) and its memory bandwidth get most of the attention in benchmarks, but the thing that actually caps how many concurrent requests a serving engine can hold in flight is usually memory capacity: model weights plus the KV cache for every in-flight sequence. Weights are fixed once a model is loaded. The KV cache is not. It grows linearly with context length and linearly with the number of concurrent sequences, which means a long-context agentic workload, the kind this blog has tracked getting more expensive all year, is exactly the shape of traffic that eats a GPU's memory fastest and stops accepting new requests first, well before the compute is saturated.
That's the lever TurboQuant pulls. Shrink the bytes each token's KV entry costs by 6x, and the same fixed GPU memory budget holds roughly 6x as many concurrent long-context sequences, or the same sequence count at roughly 6x the context length, before the scheduler has to start queuing or rejecting work.
The concrete number
| Quantization scheme | Bits per coordinate | Memory vs. FP16 | Illustrative 128K-context sessions on one fixed memory budget |
|---|---|---|---|
| FP16 (serving default) | 16 | 1x | 8 |
| FP8 KV cache (already shipping in vLLM/SGLang) | 8 | ~2x smaller | 16 |
| TurboQuant | 3 | ≥6x smaller | 48 |
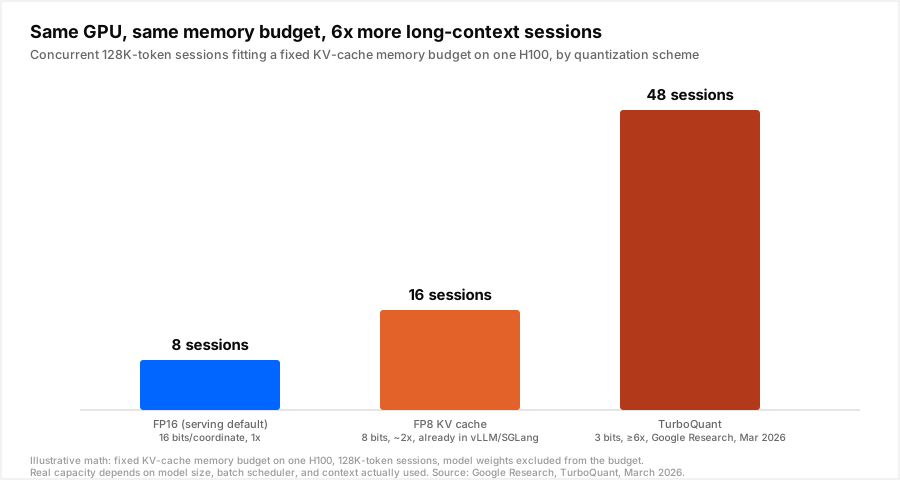
FP8 KV-cache quantization is not new; it already ships as an option in vLLM and SGLang and buys a real but modest ~2x. TurboQuant's claim is a further 3x on top of that, at half the bit-width, without the accuracy tuning that finer quantization schemes usually demand. Source: Google Research, TurboQuant.
What this does to a breakeven curve that was already a moving target
This blog modeled the self-host-vs-managed-API breakeven volume as fixed cost divided by the per-token price gap, and separately showed that effective cost per token on a self-hosted fleet swings more than 36x between a saturated GPU and an idle one, because idle GPU-hours are still billed hours. TurboQuant doesn't change the sticker price of an H100. It changes how much useful work that H100 can hold at once, which is the other half of the same equation: the same fixed monthly GPU bill divided among roughly 6x more concurrent long-context sessions moves the effective cost per token down and pulls the breakeven crossover further toward "self-hosting wins" than it sat a release cycle ago.
The same mechanic runs in reverse for hosted APIs. A lab that serves an open-weight model behind its own API and adopts a technique like this internally doesn't have to pass any of the saving along, but the historical pattern says most of them eventually do: average output pricing for frontier-tier models has fallen roughly 94.5% since March 2023, largely on serving-side efficiency gains exactly like this one, not on anyone paying more for the same GPU. A price list that looked correct in March can be stale by July for reasons that have nothing to do with the model itself.
The part of your routing policy that doesn't stay fixed
If a routing policy hardcodes a rule like "self-host once a workload crosses N million tokens a month," that rule is really a frozen snapshot of a GPU-hours-to-token-price ratio, and every input to that ratio, GPU rental rate, achievable utilization, and now KV-cache memory efficiency, keeps moving underneath it. The same failure mode broke teams who hardcoded a model name string instead of routing by request: the thing you wrote down stopped matching the thing that was actually true, and nothing told you until a bill or an outage did.
import openai

client = openai.OpenAI(
    base_url="https://api.getnadir.com/v1",
    api_key="YOUR_NADIR_KEY",
)

response = client.chat.completions.create(
    model="auto",  # Nadir scores the request against live, measured cost
                    # per tier, not a policy written down the quarter a GPU
                    # was priced or a paper hadn't shipped yet
    messages=[{"role": "user", "content": task_prompt}],
)

print(response.model)
print(response.model_extra["nadir_metadata"]["cost"]["total_cost_usd"])
The two response metadata report exactly which tier answered and what it actually cost, per request, which is the only way to know whether last quarter's self-host-vs-API line still holds this quarter. A router that re-measures beats one that remembers.
What to actually do this week
- Stop treating "self-host beats the API above X tokens/month" as a fact. It's a ratio of a GPU rental rate to a per-token price gap, and both sides move. Recompute it on a cadence, not once at kickoff.
- Check your serving engine's release notes for KV-cache quantization, not just throughput numbers. FP8 KV cache is already there in vLLM and SGLang if you haven't turned it on; a 3-bit scheme is the next one to watch land.
- Measure memory headroom, not just GPU utilization percentage. The Utilization Tax already covered why idle compute is expensive; a fleet that's compute-idle but memory-full from long-context sessions is a different problem with a different fix.
- Don't confuse KV-cache compression with prompt caching. They solve different problems and stack: one shrinks what a single running session costs to hold in memory, the other discounts a prefix repeated across sessions.
- Route on measured cost per request, not a remembered tier boundary. The boundary between "cheap enough to self-host" and "cheaper to call the API" is exactly the number that papers like this one move without asking anyone's permission.
Conclusion
TurboQuant is a memory paper, not a routing paper, and it's easy to read it as somebody else's infrastructure problem if you don't run your own GPUs. But the number it moves, effective cost per token on a self-hosted tier, is an input to a decision every team with more than one model tier is already making, whether that decision is written down explicitly or baked into whichever default nobody's revisited since it was set. A 6x memory win on the exact resource that caps long-context and agentic concurrency doesn't stay a research footnote for long once it's sitting in a public llama.cpp thread and a handful of GitHub forks already targeting vLLM. The teams whose routing policy re-measures cost per tier on every request absorb that shift automatically. The teams whose policy is a comment in a config file from last quarter find out about it on the invoice.
Sources: [Google Research / ggml-org, "TurboQuant — Extreme KV Cache Quantization," llama.cpp Discussion #20969](https://github.com/ggml-org/llama.cpp/discussions/20969). [AmesianX, "TurboQuant: Implementation of Google DeepMind's TurboQuant (ICLR 2026)"](https://github.com/AmesianX/TurboQuant). [0xSero, "TurboQuant: Near-optimal KV cache quantization for LLM inference"](https://github.com/0xSero/turboquant).