Two savings that are supposed to stack
Prompt caching and prompt compression get pitched as the same kind of thing: independent levers on the same bill, safe to run together, savings that add up. This blog has made that case before about compression and routing, and it holds. A July 2026 measurement of Anthropic's Sonnet 4.6 API found a case where it does not hold between compression and caching specifically: run the wrong kind of compression in front of a cache and the two do not add, they collide. On the public tau-bench retail benchmark, the combination came out 40.1% more expensive than doing nothing at all, on the same task, with no quality deficit to show for the extra cost. Source: Yan Song, PayPal, "Cache-Aware Prompt Compression: A Two-Tier Cost Model for LLM API Caching," arXiv:2607.15516, July 17, 2026
The paper is a single-author, $98.96-total-experiment-cost piece of work, cheap enough that its author points out anyone can reproduce it. That is unusual candor for a cost-optimization claim, and it is worth taking seriously precisely because the mechanism it describes is simple, structural, and already sitting in most production stacks that combine an off-the-shelf compressor with an API's prompt cache.
The mechanic: compression that looks at the question breaks the cache
Prompt caching is prefix-strict. A provider's cache matches on a byte-identical prefix, discounts the tokens that hit, and charges full price, sometimes a premium, for anything that misses. This blog covered that premium, and DeepSeek's contrasting no-premium disk cache, in "The Cache Write Tax." None of that changes here.
What has changed is which compression methods the literature standardized on. Most prompt-compression research, LLMLingua and its descendants included, is query-aware: the compressor looks at both the source document and the specific question being asked, and produces a compressed context tailored to that question. That is good for compression ratio and answer quality. It is also, mechanically, a different string of tokens on every single call, because the question changes on every call. A prefix-strict cache has nothing stable to match against. Query-aware compression does not merely fail to help the cache; by construction, it invalidates it on every request.
The compression literature's own cost models mostly do not notice, because they implicitly assume a cache hit rate of 1.0, that caching, wherever it is used, always works perfectly. The paper's contribution starts with checking whether that assumption is true.
Sonnet's cache turns out to have two tiers, and only one of them is a real cache
It is not true, and the gap is structural, not incidental. Characterizing Anthropic's cache empirically across 30-call sessions, at a total cost of $1.91, the paper finds a sharp architectural threshold near 3,500 tokens of prefix length:
- Below 3,500 tokens (the "hot tier"): hit rate does not converge to 1.0 no matter how many times the same prefix repeats. At a 2.4k-token prefix, it climbs from ρ=0.47 after 5 calls to a plateau of ρ=0.89 by 50 calls, and stays there.
- Above 3,500 tokens (the "persistent tier"): hit rate jumps to roughly 1.0 starting from the very first repeat call.
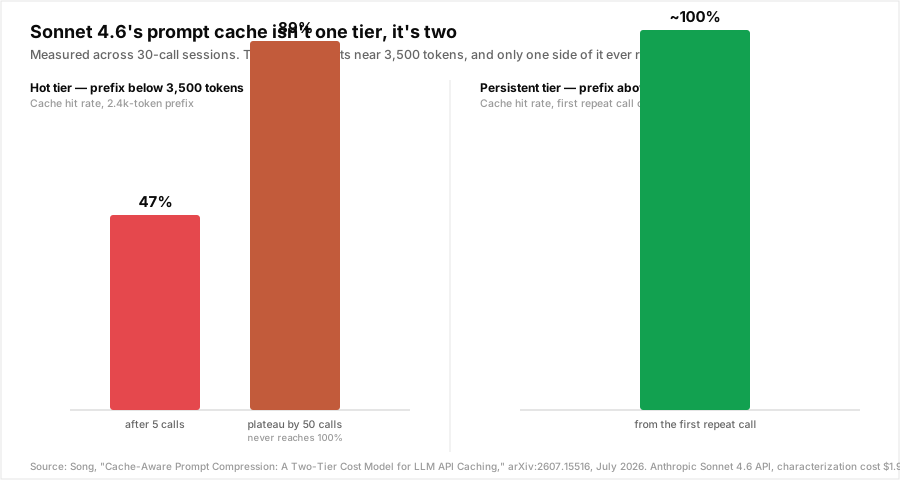
Every cost model built on "caching gives you the discounted rate" is quietly assuming the persistent tier. A huge amount of real traffic, short system prompts, small tool schemas, brief RAG snippets, lives in the hot tier instead, where roughly one call in nine or ten never gets the discount at all, forever, regardless of how many times the prefix repeats.
Why that changes which strategy actually wins
Here is where the paper earns its title. Feed a realistic hit rate, not the textbook ρ=1.0, into a provider-agnostic cost model comparing "cache the prefix, send the query as-is" against "compress the prefix for every query, and don't bother caching it," and the crossover point moves. At compression ratios of 6x or higher, query-aware compression's per-call token reduction outweighs what an imperfect cache was ever going to save, even though every single call is a guaranteed cache miss. The model predicts it; the paper's experiments confirm it. Conventional wisdom, that caching alone beats any compression scheme that breaks it, turns out to be backwards once the cache is measured rather than assumed.
That is not an argument for abandoning caching. It is an argument for knowing which regime your own traffic sits in, because getting it wrong runs in both directions. Query-aware compression at a ratio below that crossover, which is the common case for lighter compression settings, pays the full cache-miss penalty for a token reduction too small to cover it. That is exactly what happened on tau-bench: query-aware compression there was the single most expensive of four tested strategies, worse than sending the full, uncompressed prompt.
Four strategies, one public, deterministic benchmark
τ-bench retail is a useful test case specifically because its reward metric is deterministic, not judge-scored, so quality differences are not a matter of interpretation:
| Strategy | What it does | Cost vs. vanilla | Reward (of 50 tasks) |
|---|---|---|---|
| Vanilla | No caching, no compression | baseline | 36 (0.720) |
| Cache-only | Cache the prefix, compress nothing | +0.6% | 37 (0.740) |
| Query-aware compression | Compress per-query, cache broken every call | +40.1% | 38 (0.760) |
| CAPC (proposed) | Compress once, keep the cache intact | −7.9% | 36 (0.720) |
All four strategies land within four tasks of each other on the 50-task suite, well inside the noise band for a benchmark this size. CAPC and vanilla tie exactly, 36 of 50, statistically indistinguishable (two-proportion z=0.00, p=1.00), while costing 7.9% less. Query-aware compression, the most expensive strategy by a wide margin, does not buy back any of that cost in quality; it scores marginally higher than vanilla, not lower, which rules out "worse answers, cheaper tokens" as the explanation for the price gap. The 40-point spread between the cheapest and most expensive strategy, on tasks scored within noise of each other, is caching mechanics, full stop, not a quality tradeoff.
The fix: compress the document once, not the question every time
The paper's proposed method, Cache-Aware Prompt Compression (CAPC), is almost aggressively simple once the diagnosis is clear. Three changes:
- Compress query-agnostically. Shrink the shared document or tool-schema prefix once, independent of any specific question, and reuse that same compressed output across every query in the session. The prefix stops changing call to call, so it becomes cacheable again.
- Put the cache marker on the compressed block, not the query. An explicit
cache_controlboundary goes immediately after the compressed, stable prefix and before the part of the prompt that actually varies per call. - Bound the compression ratio to the tier threshold.
r_max(P) = floor(P / 3500)caps how aggressively a prefix can be shrunk, so compression never accidentally pushes a prefix that used to sit safely in the persistent tier back down into the leaky hot tier. Compress too hard on a prefix near the 3,500-token line and you can convert a ~100%-hit-rate prefix into an ~89%-hit-rate one, giving back the savings compression just bought you.
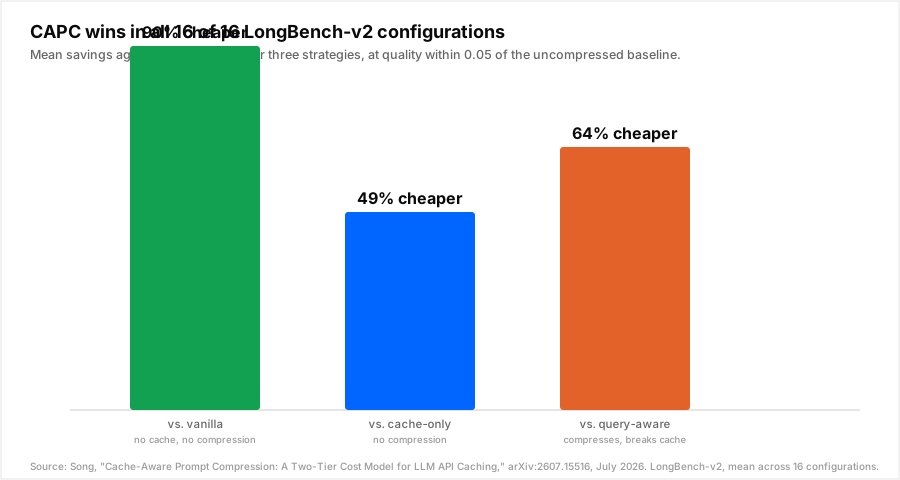
On LongBench-v2, CAPC was the cheapest strategy in all 16 of 16 tested configurations, averaging 49% cheaper than cache-only, 64% cheaper than query-aware compression, and 90% cheaper than sending the uncompressed prompt with no caching at all, holding quality within 0.05 of the uncompressed baseline.
Validated past the benchmark, on production-shaped workloads
The paper does not stop at a leaderboard. Three separate validations, closer to what an actual production stack looks like:
- A tool-using assistant with a 94k-token schema prefix: CAPC cut cost 51.7% against the uncompressed baseline at a 3x compression ratio, matching cache-only's tool-selection quality almost exactly (0.700 vs. 0.703), and held a 45.5% end-to-end cost reduction in a full production-style run.
- A knowledge-graph RAG pipeline ("graphify") across two real codebases: 9.3x cheaper than caching everything on FastAPI, 2.4x cheaper on httpx, stable across prefixes ranging from 5k to 260k tokens.
- τ-bench retail, the public benchmark above: cheapest of four strategies, at reward exactly equal to vanilla.
If you already run a compressor in front of an API cache, this is worth an afternoon to check
The teams most exposed to this are the ones who did the seemingly responsible thing already: adopted a compression library to cut input tokens, and separately turned on prompt caching because the provider docs said it was close to free money. This blog called it exactly that. If that compression step is query-aware, rewriting the prompt differently depending on the question, those two "free" savings may be quietly fighting each other on every single call, and the only way to know is to measure your own hit rate with the compressor in the loop, not assume the vendor's benchmark number carries over.
This is the same shape of collision this blog keeps finding between two things that look independent on a pricing page and are not independent at the byte level: a router that ignores which replica holds a warm KV cache, a JSON-heavy tool result that costs more punctuation than data, and now a compressor that quietly rewrites the one part of the prompt a cache needed to stay still. None of these are exotic failure modes. They are the default behavior of tools that were each individually optimized for a metric, tokens saved, cache hit rate, that stopped being the metric that mattered the moment the two tools sat in the same request path.
It is also why Nadir's own Context Optimize trims a request the way CAPC's fix does rather than the way the compression literature standardized on: its safe pass, deduplicating repeated tool schemas and system prompts, minifying embedded JSON, normalizing whitespace, is a deterministic function of the input, not of the question being asked inside it. The same tool schema compresses to the same output on call one and call fifty, which is precisely the property CAPC has to engineer back in by hand for compressors that were built query-aware from the start. Compression and cacheability are not two goals in tension here; the design that keeps them aligned by construction is the one that never had to choose.
What to actually do this week
- Measure your compressor's output stability, not just its ratio. Feed the same document through your compression step with two or three different questions attached. If the compressed prefix changes at all, it is query-aware, and it is invalidating any cache sitting behind it.
- If it's query-aware, check your compression ratio against roughly 6x. Below that, the paper's cost model says a broken cache is probably costing you more than the compression saves. Above it, compression alone may genuinely beat an intact cache, but you're then choosing not to cache at all, not accidentally paying for both and getting neither.
- Separate the stable part of your prompt from the part that actually varies. A shared system prompt, tool schema, or retrieved document is a compression target that can stay query-agnostic. Push the literal user question to the end of the prompt, after the cache boundary, not folded into the same compression pass.
- Watch prefixes sitting near 3,500 tokens especially closely. That is exactly where an eager compression pass can shove a prefix out of the persistent tier and into the leaky hot tier, and the failure is invisible unless you are tracking hit rate directly.
- Don't assume ρ=1.0 in your own cost math. Whatever provider you're on, measure your actual hit rate the way this paper measured Anthropic's, in production, with your real session lengths, not the discount rate off the pricing page.
Conclusion
Caching and compression are both real, both cheap to adopt, and both routinely sold as savings that simply add up. This paper's contribution is showing a specific, common way they instead subtract from each other: compression that looks at the question breaks a cache that needed the prefix to hold still, and the resulting bill can land 40% above doing nothing at all, with no quality gain to justify it. The fix costs nothing extra to run, compress the stable part once, cache it explicitly, cap the ratio at the tier boundary, and it won in 16 of 16 tested configurations against every alternative, including doing nothing. If a compression step sits anywhere in front of a cache in your own stack, it is worth an afternoon to find out which side of that line you're actually on.
Sources: [Yan Song, PayPal, "Cache-Aware Prompt Compression: A Two-Tier Cost Model for LLM API Caching," arXiv:2607.15516, July 17, 2026](https://arxiv.org/abs/2607.15516).