Abstract.
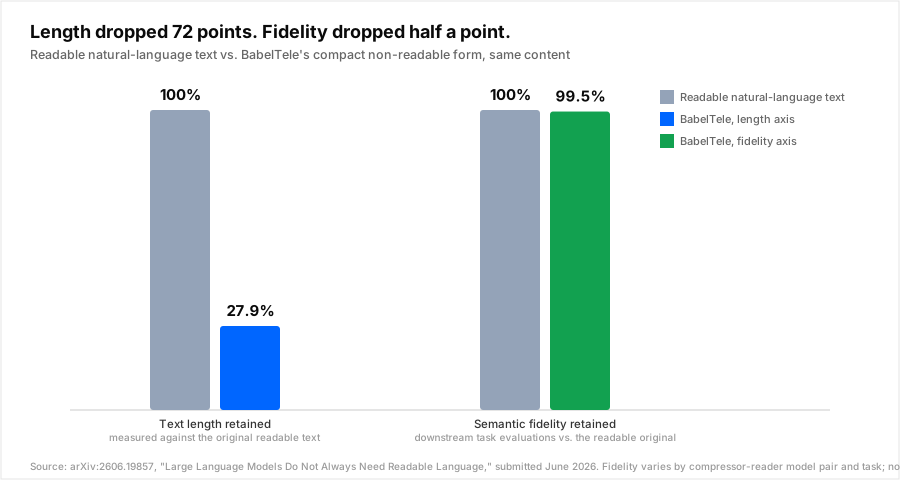
Every optimization this blog has covered so far, routing, LLMLingua's extractive compression, TOON's leaner serialization, shares one constraint nobody states out loud: whatever gets sent to the model still has to be readable English, or at least readable JSON. A June 2026 paper asks why. "Large Language Models Do Not Always Need Readable Language" (arXiv:2606.19857) tests whether an LLM can generate and interpret text that a human could not comfortably parse, as long as another LLM can still recover the meaning. The authors call this class of representation BabelTele, not a protocol, a probe. The headline number: 99.5% semantic fidelity retained while text volume dropped to 27.9% of the original, a 72-point reduction, evaluated across cross-model transfer, agent memory, and multi-agent communication. This post walks through what the paper actually measured, where it sits relative to compression techniques already in production, and where the idea is safe to test without betting anything a human needs to read on it.
Research question.
If human readability is dropped as a design constraint, how much can a textual representation shrink while an LLM reader still recovers its meaning, and does that hold up when the model reading the message is not the same model that wrote it?
English was never optimized for a model reading it.
Every prompt-engineering convention in production today, full sentences, consistent grammar, JSON with quoted keys, exists because a human either wrote it, will read it, or was the original audience the format was designed for. That convention got inherited wholesale into machine-to-machine text. A tool result gets serialized as pretty-printed JSON nobody will look at. An agent's scratchpad reasoning gets written in complete English sentences, even though the next reader is the same agent's next turn, a process with no eyes. TOON already found one seam in this constraint: dropping repeated punctuation in structured data cuts tokens 42.6% in its own benchmark without touching readability at all, the format is still plainly legible, just less redundant. The BabelTele paper asks a more direct question: what if the constraint itself, not just its redundancy, is negotiable for text no human will ever read.
What the paper actually tested.
The authors do not propose BabelTele as a fixed encoding scheme with a spec sheet. They frame it as an empirical probe into instruction-tuned models' capacity to generate and interpret representations that depart from natural-language typicality, then measure how far that departure can go before meaning breaks. Four evaluation angles: readability diagnostics and human questionnaires, to confirm the output really is less human-legible and not just terser English; model likelihood measures; downstream task evaluations, to check the reader model still performs correctly on what the compact text described; and three specific stress tests, cross-model transfer (does a representation one model wrote survive being read by a different model), agent memory (does compressed context still serve its purpose across turns), and multi-agent communication (does the saving hold when the message is the entire channel between two agents, not a compressed prompt to a human-facing model).
| Metric | Readable text (baseline) | BabelTele |
|---|---|---|
| Text length | 100% | 27.9% |
| Semantic fidelity | 100% | 99.5% |
Read literally: the same information that took 1,000 tokens in ordinary English took roughly 279 in the compact form, and a downstream reader model recovered 99.5% of the meaning either way. The paper's own qualifier matters as much as the number: results "suggest that BabelTele can reduce context overhead while generally maintaining reliable downstream performance, although its effectiveness depends on the compressor-reader pair and task setting." That is not a universal ratio, it is a ceiling the authors observed under specific conditions, with an explicit warning that the pairing of which model compresses and which model reads changes the outcome.
Three layers of token reduction, and where this one sits.
This blog has now covered three distinct answers to "the model doesn't need every token you're sending it," and they are not the same lever wearing different clothes.
| LLMLingua / Selective Context | TOON | BabelTele | |
|---|---|---|---|
| What it operates on | Natural-language prose | Structured data (arrays, objects) | Any text, structure or prose |
| Stays human-readable | Yes, shorter English | Yes, still legible, less punctuation | No, that is the point |
| Mechanism | Drops low-information tokens, scored by a small model | Declares a shared field header once instead of per row | Departs from natural-language typicality while staying model-recoverable |
| Reported reduction | 3 to 5x on benchmarks, 40 to 62% in Microsoft's production workloads | 42.6% fewer tokens than JSON in its own benchmark | Text volume cut to 27.9% of original at 99.5% fidelity in one evaluation |
| Where it belongs today | RAG context, retrieved documents, conversation history | Tool results, API responses, any uniform array | Agent-to-agent messages, agent memory, nothing a human reads |
| Maturity | Shipped, MIT-licensed, production use at Microsoft | Shipped format, five language ports | A June 2026 research probe, not released software |
Source: Microsoft Research, "LLMLingua-2," 2024; TOON benchmark cited in The Punctuation Tax; arXiv:2606.19857
The three do not compete for the same tokens. LLMLingua shortens prose a human might still glance at during debugging. TOON changes how structured data is punctuated without touching legibility. BabelTele is the only one of the three that treats readability itself as a cost, applicable only where nobody is paying for that cost to begin with.
The catch: readability is also your audit trail.
The paper is honest about the boundary, and it is worth restating plainly rather than glossing over. "Human readability, natural-language typicality, and model-side semantic recoverability can be partially decoupled" is the finding, and "partially" is doing real work in that sentence. Decoupling readability from recoverability means exactly what it sounds like: a message optimized this way is, by design, harder for a person to check. That is a fine trade for a scratchpad no one audits. It is a bad trade for anything a support engineer needs to read during an incident, anything compliance needs to inspect, or any tool-call payload a human reviews before it executes an action with real consequences. The paper's own qualifier, that fidelity depends on the specific compressor-reader pair and task, means a representation that held up in the published evaluation is not guaranteed to hold up on your model pair and your task without measuring it yourself first.
Where this is actually safe to try today.
Not as a library, there isn't one. As an experiment, on the narrow slice of text that already has no human reader: an agent's internal scratchpad between reasoning steps, memory carried across turns of the same agent, or a status message one agent sends another mid-loop that a user interface never renders. The shape of a small, honest test, not a reproduction of the paper's method, looks like this:
def round_trip_fidelity(writer_model, reader_model, original_text, compact_text):
    """Ask a reader model to reconstruct meaning from a compact message,
    then score it against the original with a separate judge call."""
    reconstruction = reader_model.complete(
        f"Reconstruct the full meaning of this message: {compact_text}"
    )
    judge_score = judge_model.complete(
        f"On a 0-100 scale, how much of this original meaning survived?\n"
        f"Original: {original_text}\nReconstruction: {reconstruction}"
    )
    return float(judge_score)

# Run on your own agent-to-agent messages, not the paper's dataset.
# A single compressor-reader pair holding 95%+ fidelity on your task
# is a result specific to that pair. Re-measure if either model changes.
That is the whole discipline the paper points at: measure fidelity for your specific writer and reader models before trusting a compact representation with anything that matters, and never let the technique anywhere near text a human is the intended reader of. Nadir's context optimization already strips redundant tool schemas and repeated boilerplate before a request goes out, on the same premise this paper pushes one layer further: not every token in a message is there because the reader needs it, some are there because a human designed the format for a human. On the machine-only side of that line, where multi-agent workflows already multiply token spend well beyond a single chat call, that is exactly where a denser representation has the most room to matter.
Conclusion.
TOON found that structured data doesn't need to repeat its own punctuation. LLMLingua found that prose carries tokens a downstream task doesn't need. This paper asks the more uncomfortable version of the same question: does the text even need to be readable at all, for a reader that was never going to be a person. The answer, on one evaluation, was that 27.9% of the original length carried 99.5% of the meaning, measured across cross-model transfer, agent memory, and multi-agent communication, with an explicit caveat that the result is pair- and task-dependent, not a fixed guarantee. That is not a library to install this afternoon. It is a boundary worth knowing exists the next time a token bill is dominated by messages no human was ever going to read.