The market split into two prices, and only one of them is falling.
BenchLM's Token Price Index tracked 143 models with live API pricing over the twelve months to August 2026 and found two trend lines moving in opposite directions on the same chart. Frontier-tier pricing, BenchLM's top 10 ranked models, rose 36.4% year over year. Mid-tier and budget pricing, the other 133 models, fell 35.8% over the identical window. Same market, same twelve months, a nearly 72-point spread between the two curves.
For three years, the standard line on LLM pricing was one number: prices keep falling, and routing to a cheaper model is free money with no expiration date. That is still true for most of the market. It stopped being true for the top of it in January 2026, and most routing setups built on the old, single-direction story have not been updated to reflect the split.
Why the top of the market got a repricing, not a discount
OpenAI's GPT-5.6 Sol, the frontier flagship as of July 29, 2026, prices at $5.00 per million input tokens and $30.00 per million output, roughly double what the equivalent frontier tier charged in January 2026. Anthropic's Claude Fable 5 runs $10.00 input and $50.00 output. Neither number reflects a shortage or a subsidy ending. It reflects a genuine capability jump, longer agentic task horizons, deeper multi-step reasoning, priced the way a new capability tier usually gets priced: at a premium, not a discount.
That is a different mechanism from the deflation that defined 2023 through 2025, which came from efficiency gains and competition forcing cuts on models whose capability was not moving much generation to generation. When the capability itself jumps, providers reprice upward instead of down. Both dynamics are running in the same market right now, on different rows of the same price list.
The three tiers, side by side
| Tier | Model | Input ($/M) | Output ($/M) | 12-month direction |
|---|---|---|---|---|
| Frontier | GPT-5.6 Sol | $5.00 | $30.00 | +100% since Jan 2026 |
| Frontier | Claude Fable 5 | $10.00 | $50.00 | up |
| Mid | Gemini 3.1 Pro | $2.00 | $12.00 | down |
| Mid | Claude Opus 5 | $5.00 | $25.00 | down |
| Mid | GPT-5.6 Luna | $1.00 | $6.00 | down |
| Budget | DeepSeek V4-Flash | $0.14 | $0.28 | down |
| Budget | GPT-4.1 Nano | $0.10 | $0.40 | down |
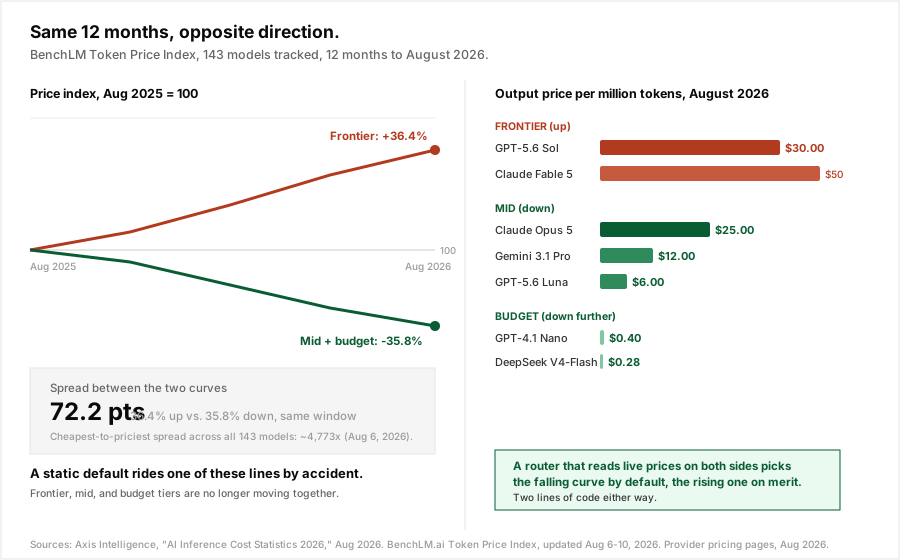
The gap between the cheapest and most expensive model BenchLM tracks now runs to roughly 4,773x on a blended per-million-token basis, as of August 6, 2026, the widest that spread has been since BenchLM started publishing the index. A market that spreads out this far is not a market where one number, "AI is getting cheaper," tells you anything useful about where your own traffic sits.
What "prices fell in aggregate" was hiding
The 40-month, 214x price collapse on the cheapest tracked models since GPT-4's March 2023 launch at $30 per million input tokens is real, and it is the reason the overall narrative has been "costs keep dropping" for three years running. But an aggregate built from 143 models, most of them budget and mid-tier, absorbs a 36.4% frontier increase without the average line even flinching. The average is not wrong. It is just describing a different 133 models than the ones a team defaulting to the frontier tier is actually paying for.
Open-weight models carry the deflation the furthest: a median blended price around $0.53 per million tokens against roughly $2.81 to $3.00 for proprietary models, an 81% to 82% gap that has only widened as budget-tier proprietary pricing chases it down. That's the pull driving the mid and budget curve toward zero. It has no bearing on what happens at the top of the market, where a harder task and a longer context window are now underwritten by a price increase instead of absorbed by one.
The default that quietly got 36% more expensive
Here's the part that matters for a routing decision made months ago and never revisited. A team that standardized on a frontier model as the safe, one-size-fits-all default, "just use the best model for everything so we don't have to think about it," is not looking at flat pricing while they wait to decide whether routing is worth building. They are on a curve that added 36.4% to the same workload, at the same volume, with zero growth in traffic, purely from the provider's own repricing over the last twelve months. That's not a cost of doing more. It's the cost of standing still.
The inverse holds for a setup that already routes simple, well-defined requests to a mid or budget-tier model by default and escalates only when a task needs it. That default rides the 35.8% deflation curve down, on the same twelve-month clock, again with zero change in behavior. Two teams running an identical workload, one default apart, are now 72 points of relative cost away from each other, and the gap is compounding every quarter both defaults stay unreviewed.
Three questions for your own stack
- Do you know, right now, whether your default model sits on the tier that went up 36% or the one that went down 36%? Most teams can name their default model. Few have checked which side of this split it landed on in the last twelve months specifically.
- Is your routing threshold pinned to a price ratio you measured before this divergence started? A cascade tuned against last year's frontier-to-budget gap is tuned against a gap that has since widened by roughly 72 percentage points. The threshold that made sense in August 2025 is escalating too eagerly, or not eagerly enough, today.
- Would a repricing on either side show up in your dashboard before it shows up on the invoice? A market moving in two directions at once needs a routing layer that reads both, not a table someone wrote down when the market still moved in one.
Where Nadir fits
Nadir's classifier scores each prompt against live provider pricing on both sides of this split, a frontier tier that's getting more expensive and a mid and budget tier that's getting cheaper, rather than a price ratio someone captured during a cost review before the divergence widened. Simple requests route down to whichever model on the falling side of the market can handle them; only the requests that need frontier-level reasoning escalate to the rising side, and the quality floor you set per API key decides where that line sits, not a hardcoded model name.
The integration is two lines: point the base URL at Nadir, set model="auto". When a priced benchmark comparison is available, the response includes the nadir_metadata.benchmark_comparison.savings_usd field, so when either tier reprices, frontier up or budget down, you see the shift in your own metrics instead of finding out from the bill.
Conclusion
The story was never just "AI got cheaper." As of August 2026, it's "AI got cheaper for most of the market and meaningfully more expensive for the top of it, at the same time." A static default, in either direction, now rides one side of that split by accident. A routing layer that checks live pricing on every request rides whichever side actually fits the task, on purpose, and that difference compounds every quarter the split keeps widening.
Related reading
- The Floor Just Moved
- The Rate Card Trap
- OpenAI's $14 billion loss and what it means for your API price
- The Real Monthly Bill
Sources: [Axis Intelligence, "AI Inference Cost Statistics 2026: The Market That Split in Two"](https://axis-intelligence.com/ai-inference-cost-statistics/) (accessed August 2026). [BenchLM.ai, "LLM Pricing Statistics 2026: Cost Per Million Tokens Data"](https://benchlm.ai/stats/llm-pricing) (updated August 6-10, 2026). Provider pricing pages for OpenAI, Anthropic, Google, and DeepSeek, accessed August 2026.