The line didn't move. What sat on which side of it kept changing.
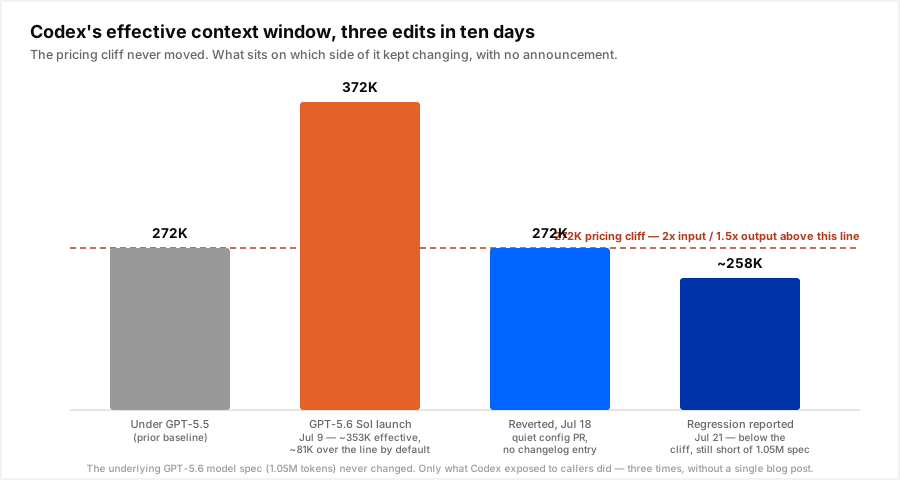
On July 9, 2026, OpenAI's GPT-5.6 family went generally available across ChatGPT, Codex, and the API, in three tiers: Sol, Terra, and Luna. Source: Simon Willison, "The new GPT-5.6 family: Luna, Terra, Sol" At launch, Codex's exposed context window for GPT-5.6 Sol expanded to 372,000 tokens, up from the 272,000 tokens Codex had run at under GPT-5.5. Source: sakutto, "Why Codex's Context Shrank to 272k"
There's a second number attached to GPT-5.6 Sol that has nothing to do with how much context Codex decides to expose: OpenAI's own pricing documentation states that "prompts with >272K input tokens are priced at 2x input and 1.5x output for the full request," across standard, batch, and flex modes. Source: sakutto, "Why Codex's Context Shrank to 272k" Not the tokens over the line. The whole request.
Nine days after GPT-5.6 shipped, a developer filed a GitHub issue pointing out the obvious consequence: the 372K default, at roughly 95% effective utilization, works out to about 353,400 usable tokens, which is already 81,400 tokens past the 272K pricing cliff. Source: openai/codex, Issue #32486 Any session that actually used the context Codex advertised was landing in the 2x/1.5x tier by default, silently, for however many days it took someone to notice.
Then it moved again, twice, with no announcement either time
On July 18, OpenAI merged a configuration change reverting Codex's exposed window back to 272,000 tokens. Source: sakutto, "Why Codex's Context Shrank to 272k" There was no blog post and no changelog entry a normal user would see; it surfaced because developers noticed their sessions behaving differently and went digging, which is its own small case study in why silent capacity changes are worse than silent price changes. Source: NoCode.Tech, "OpenAI Quietly Slashed Codex's Context Window by 27%"
Three days after that, a second GitHub issue reported the window had been cut again, down to roughly 258,000 tokens, below the 272K line entirely, and flagged it as a severe regression given the underlying model still advertises a 1.05 million token context window. Source: openai/codex, Issue #32806 The raw GPT-5.6 spec, 1,050,000 tokens of context and 128,000 tokens of max output, never changed through any of this. Source: QCode, "GPT-5.6 Sol, Terra & Luna — Benchmarks, Pricing & Access" Only what Codex chose to expose did, three times in ten days, in both directions, without a release note attached to any of the three moves.
OpenAI's own explanation for why the window shrank in the first place isn't really about the 272K sticker price at all. Thibault Sottiaux described the actual driver as infrastructure cost, not the pricing tier: "It is caused by overall cost of cache reads going up with the size of the context being shuffled back and forth between toolcalls." Source: sakutto, "Why Codex's Context Shrank to 272k" An agentic tool-calling loop re-reads its accumulated context on every turn; the bigger that context, the more that re-read costs OpenAI to serve, independent of whatever a customer sees on their own invoice. Sottiaux says the team is working on "tuning the system differently so that we can go back higher without it resulting in higher usage being charged," which is a reasonable engineering goal and also a tacit admission that the window size and the price a customer pays have been coupled by coincidence of a shared number, not by design. Source: sakutto, "Why Codex's Context Shrank to 272k"
What crossing the line actually costs
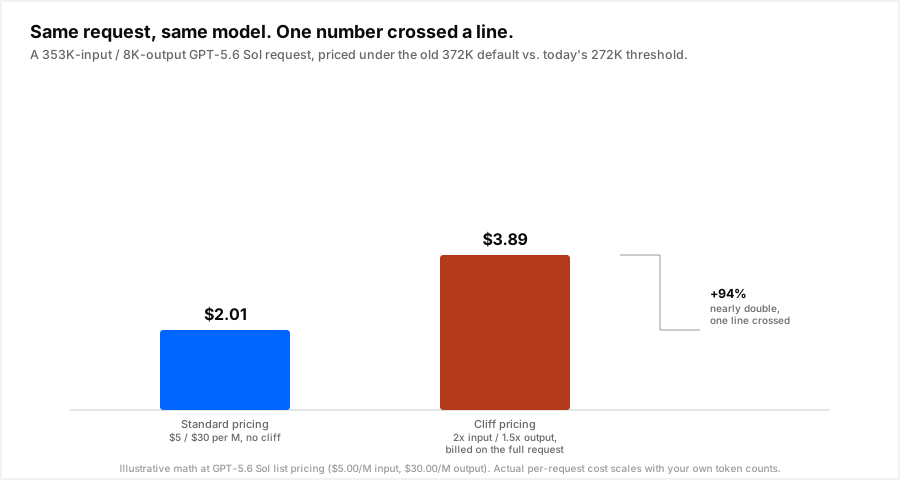
Take a single GPT-5.6 Sol request at the old 372K default's effective size, roughly 353,400 input tokens, with a typical 8,000-token output. At Sol's list price of $5.00 per million input tokens and $30.00 per million output tokens, that request costs about $2.01 priced normally. Source: Finout, "GPT-5.6 Pricing 2026: Sol, Terra and Luna Tiers Explained" Priced at the 2x input / 1.5x output cliff rate, because the request crossed 272K tokens, the same call costs about $3.89. Nothing about the task changed. Nothing about the answer changed. The bill nearly doubled because one input number sat on the wrong side of a line drawn at 272,000.
Multiply that across an agentic coding session that spends dozens of turns above the threshold before anyone notices, and the reports of developers burning hundreds of dollars in an afternoon stop looking like exaggeration. Most IDE integrations don't surface a warning before a session crosses 272K; the first signal is usually the invoice.
Three vendors, three answers to the same design question
The interesting part isn't that OpenAI has a long-context pricing cliff. It's that all three frontier labs built the identical mechanic, 2x input, 1.5x output, above a fixed token threshold, and each one has handled it differently since:
| Provider | Cliff mechanic | Threshold | Status, July 2026 |
|---|---|---|---|
| OpenAI (GPT-5.5, GPT-5.6 Sol) | 2x input / 1.5x output, billed on the full request | 272K tokens | Active. Codex's exposed window has moved around this line three times since July 9 |
| Google (Gemini 3.1 Pro) | 2x input ($2.00 → $4.00/M) / 1.5x output ($12.00 → $18.00/M) | 200K tokens | Active, unchanged |
| Anthropic (Opus 4.6+, Sonnet 4.6+) | Had the same 2x input / 1.5x output structure above 200K tokens | 200K tokens | Removed March 13, 2026. Full 1M-token window now billed at standard rates, no surcharge |
Source: eesel AI, "Google Gemini 3 pricing 2026"; Source: The New Stack, "Anthropic makes a pricing change that matters for Claude's longest prompts"; Source: byteiota, "Anthropic Drops Long-Context Premium"
Anthropic carried the identical cliff on its own long-context tier before removing it outright in March. Google kept it as-is. OpenAI kept the price mechanic and is instead adjusting the much blunter lever sitting next to it, how much context a specific product surface even lets you reach, which is how you end up with a pricing threshold that's stable while the thing that determines whether you hit it moves three times in ten days.
The fix isn't picking the vendor without a cliff. It's not caring where the cliff is.
Standardizing on Anthropic because it dropped its surcharge solves this exact problem and creates the next one: whichever vendor's pricing structure looks safest today is one blog post away from changing, same as Codex's window did three times this month. The durable fix is architectural, not vendor selection: track cumulative input tokens per request before it goes out, and route or trim before a session crosses whatever threshold currently applies to whichever model it's headed toward.
import openai

client = openai.OpenAI(
    base_url="https://api.getnadir.com/v1",
    api_key="YOUR_NADIR_KEY",
)

response = client.chat.completions.create(
    model="auto",
    messages=conversation_history,
    extra_body={"layers": {"optimize": "safe"}},
    # Context Optimize (off by default, on here) runs deterministic
    # dedup and trimming on tool schemas, chat history, and repeated
    # system prompts before the call reaches the provider, typically
    # a 30-70% cut in input tokens. That's the same margin that keeps
    # a long agentic session under whichever provider's long-context
    # cliff it's about to route to, instead of finding out from
    # the invoice that it already crossed one.
)

print(response.model)   # which model actually answered
metadata = response.model_extra["nadir_metadata"]
print(metadata["cost"]["total_cost_usd"])
print((metadata.get("benchmark_comparison") or {}).get("savings_usd"))
The response paths are real, not illustrative filler: complete non-streaming calls include model and nadir_metadata.cost.total_cost_usd; when a benchmark is configured and priced, nadir_metadata.benchmark_comparison.savings_usd is present too. The point is the same discipline this blog applies to prompt cache write premiums and model-name deprecations: build the layer that checks before each call instead of memorizing which vendor is safest this week.
What to actually do this week
- Instrument input tokens per request, not just total spend. A monthly bill going up doesn't tell you whether it's more traffic or more requests quietly crossing a pricing cliff. Per-request token counts do.
- Check your default context settings on every agentic tool you run, today. Codex's exposed window has changed three times in ten days with no announcement attached to any of them. Whatever number you tested against last week may not be the number in production this week.
- Treat "the model supports 1M tokens" and "your provider will bill you standard rates for using it" as two separate facts. The GPT-5.6 spec sheet and Codex's actual exposed default have disagreed by up to 100K tokens this month alone.
- Trim before you route, not after you're billed. Deterministic context compaction, tool-schema deduplication, and chat-history trimming all reduce the input tokens a request carries before it ever reaches a provider's pricing tier boundary.
- Don't bet the fix on one vendor's current policy. Anthropic removed its cliff in March. Google hasn't. OpenAI is actively moving the exposed-window number around its own fixed threshold in both directions. Whichever one looks safest today is a policy change away from not being safest.
The number that matters isn't 272K
It's whatever threshold is active, for whatever model a given request is about to hit, at the moment that request goes out, because that number has now demonstrably changed three times in ten days for one provider alone and once, permanently, for another. A team that hardcodes "we're under the limit" once and moves on is betting against a line item three different vendors have each redrawn at least once this year. Start free and let the routing layer track the threshold instead, or read the complete guide to cutting LLM API costs for what else changes once a moving pricing cliff stops being something your team has to watch by hand.
Sources: [Simon Willison, "The new GPT-5.6 family: Luna, Terra, Sol"](https://simonwillison.net/2026/Jul/9/gpt-5-6/). [sakutto, "Why Codex's Context Shrank to 272k: OpenAI's Explanation and the Impact"](https://sakutto.ai/en/articles/openai-codex-context-cut). [openai/codex, Issue #32486, "Default GPT-5.6 context can cross the 272K higher-usage threshold"](https://github.com/openai/codex/issues/32486). [openai/codex, Issue #32806, "SEVERE REGRESSION: GPT-5.6 Sol context cut again"](https://github.com/openai/codex/issues/32806). [NoCode.Tech, "OpenAI Quietly Slashed Codex's Context Window by 27%"](https://www.nocode.tech/article/openai-quietly-slashed-codexs-context-window-by-27-check-your-no-code-ai-workflows). [Finout, "GPT-5.6 Pricing 2026: Sol, Terra and Luna Tiers Explained"](https://www.finout.io/blog/gpt-5.6-pricing-2026-sol-terra-and-luna-tiers-explained). [QCode, "GPT-5.6 Sol, Terra & Luna — Benchmarks, Pricing & Access"](https://qcode.cc/en/gpt-5-6-guide). [eesel AI, "Google Gemini 3 pricing 2026"](https://www.eesel.ai/blog/google-gemini-3-pricing). [The New Stack, "Anthropic makes a pricing change that matters for Claude's longest prompts"](https://thenewstack.io/claude-million-token-pricing/). [byteiota, "Anthropic Drops Long-Context Premium: 1M Tokens at Standard Pricing"](https://byteiota.com/anthropic-drops-long-context-premium-1m-tokens-at-standard-pricing/).