Same lever, three names, one invoice
Every frontier reasoning model now ships a dial for how much it thinks before it answers, and every vendor calls it something different. OpenAI's o-series and GPT-5.5 reasoning tier take a reasoning_effort string. Claude Opus 4.8 takes an effort string with five levels. Gemini 2.5 Pro and Flash take a thinking_budget integer, a raw token count instead of a label. Three parameter names, three shapes, one identical mechanic underneath: the model reasons internally before it writes the answer you see, and that internal reasoning is billed as output tokens, at output rates, whether anyone ever reads it or not.
A typical o-series call generates 3x to 10x more reasoning tokens than the visible response contains. Nobody sees those tokens by default. Everybody pays for them.
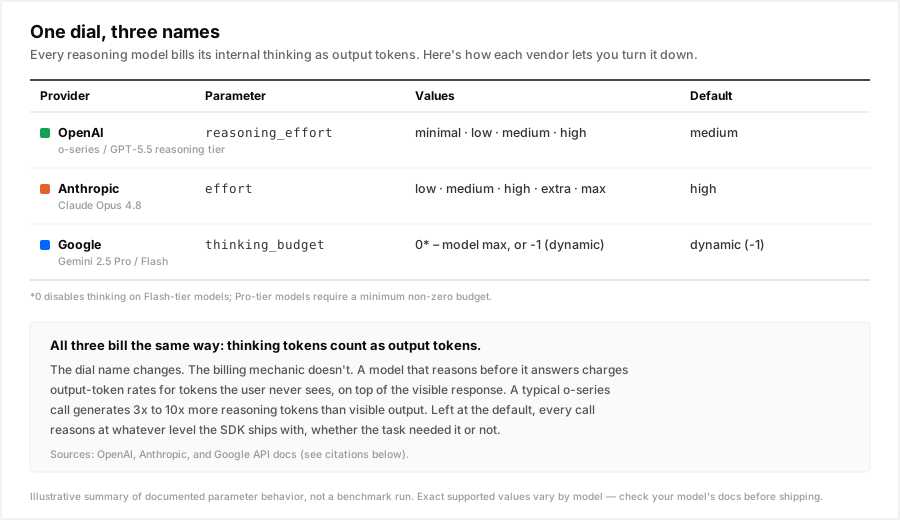
Most teams never touch the dial. They call the reasoning model, get an answer, and move on, reasoning at whatever level the SDK defaults to, on every call, for every task, regardless of whether the task needed deep reasoning or a two-second classification. This is the tutorial for turning the dial down, provider by provider, with the code to do it.
The three parameters, side by side
| Provider | Parameter | Values | Default | Docs |
|---|---|---|---|---|
| OpenAI (o-series, GPT-5.5 reasoning tier) | reasoning_effort | minimal · low · medium · high | medium | OpenAI, "Reasoning models" |
| Anthropic (Claude Opus 4.8) | effort | low · medium · high · extra · max | high | Claude API Docs, "Effort" |
| Google (Gemini 2.5 Pro / Flash) | thinking_budget | 0* – model max, or -1 for dynamic | dynamic (-1) | Google, "Gemini thinking" |
*thinking_budget: 0 disables thinking entirely on Flash-tier models. Pro-tier models require a minimum non-zero budget and can't be fully turned off. Exact supported values vary by model snapshot, so check the docs for the specific model you're calling before you ship a hardcoded level.
Note what's consistent across all three: none of them expose a separate line item for reasoning tokens in the response object. The number folds into output_tokens (or the provider's equivalent), so the only way to see what the dial is actually costing you is to instrument it yourself, the same problem this blog has already covered for Claude specifically.
Setting the dial, provider by provider
OpenAI:
import openai

client = openai.OpenAI()

response = client.chat.completions.create(
    model="gpt-5.5",
    reasoning_effort="low",  # minimal / low / medium / high
    messages=[{"role": "user", "content": task_prompt}],
)
Anthropic:
import anthropic

client = anthropic.Anthropic()

response = client.messages.create(
    model="claude-opus-4-8",
    max_tokens=4096,
    effort="low",  # low / medium / high / extra / max
    messages=[{"role": "user", "content": task_prompt}],
)
Google:
from google import genai
from google.genai import types

client = genai.Client()

response = client.models.generate_content(
    model="gemini-2.5-flash",
    contents=task_prompt,
    config=types.GenerateContentConfig(
        thinking_config=types.ThinkingConfig(thinking_budget=0)  # off, Flash-tier only
    ),
)
Three SDKs, three call shapes, one line each. The hard part was never the code. It's remembering the line exists, and deciding what value belongs on which call site.
The decision most teams skip
Setting a global default and forgetting it is the common failure mode, and it fails in both directions. Leave every call at the vendor default and a document-triage step, a status check, a one-line classification, reasons as hard as a multi-file code review. Hardcode low everywhere to save money and the one call that actually needs deep reasoning, a contract clause interpretation, a multi-step debugging trace, ships a shallow answer because the dial never moved back up.
The fix is the same discipline this blog keeps coming back to for model selection: treat effort level as a routing decision, not a deployment-wide constant. A rough starting split that works across most agent pipelines:
- Low / minimal. Classification, formatting, extraction, status checks, anything with a narrow, checkable answer space. The model doesn't need to deliberate to get these right.
- Medium. Standard analytical tasks, single-document Q&A, most customer-facing generation. The default tier for a reason.
- High / extra / max. Multi-step reasoning, multi-file code review, anything where a wrong answer is expensive to catch downstream. Reserve the top tier for the calls that actually justify it.
The same cascade logic that routes a request to a cheap model when a cheap model can answer it applies one level down, inside a single model, to how hard that model is allowed to think. Model selection and effort selection are two separate levers on the same bill, and most teams only ever pull one of them.
What changes when a router picks the dial instead of a developer
Hand-maintaining three branches of provider-specific effort logic across a codebase is exactly the kind of per-provider bookkeeping a routing layer exists to absorb. Nadir's proxy accepts one normalized shape and maps it to whichever parameter the routed provider actually expects:
import openai

client = openai.OpenAI(
    base_url="https://api.getnadir.com/v1",
    api_key="YOUR_NADIR_KEY",
)

response = client.chat.completions.create(
    model="auto",
    reasoning={"effort": "low"},  # translated to reasoning_effort, effort,
                                   # or thinking_budget depending on where
                                   # the request routes
    messages=[{"role": "user", "content": task_prompt}],
)
One field on the request, instead of three SDKs and three conditionals in application code. The response's cost header still reflects whatever reasoning tokens actually got spent on that specific call, so switching a task from high to low shows up immediately in the number, not in a monthly invoice three weeks later.
A checklist to run this week
- Grep your call sites for reasoning models. Anywhere you call an o-series model, GPT-5.5 in its reasoning tier, Opus 4.8, or Gemini 2.5, check whether an effort or budget parameter is set at all. Most calls have none, which means every one of them is running at the vendor default.
- Segment those call sites by task type. Classification and extraction calls almost never need the top effort tier. Multi-step reasoning calls almost always underperform at the bottom one.
- Set explicit levels, don't inherit defaults. A default is a decision someone else made for a workload they've never seen. Pin the level per call site instead.
- Instrument the delta before and after. Compare the cost header (or your own token accounting) on the same task at two effort levels before rolling the change out broadly. The 3x-to-10x range this post opened with is a range, not a guarantee, and it varies by task.
- Move it into routing once the pattern holds. A hardcoded effort level per call site is better than no level at all, but it's still a constant. The same task complexity signal that decides which model to call is usually enough to decide how hard that model should think.
The dial exists on every reasoning model shipping today. The cost of leaving it untouched doesn't show up as an error or a warning, it shows up as a slightly higher number on every single call, compounding silently across however many requests a production pipeline sends in a day. Start free and let routing set the dial per request, or read the complete guide to cutting LLM API costs for the rest of what's on the table.