One prompt, priced differently depending on what language it's typed in
Every cost-optimization post on this blog, routing, compression, caching, starts from one assumption: the request is in English. That assumption is invisible right up until it isn't. Tokenizers are trained overwhelmingly on English text, and the vocabulary they learn compresses English into fewer tokens than it compresses almost anything else. The result is a tax nobody bills you for by name: the same question, asked with the same intent and answered to the same quality bar, costs more tokens, and therefore more money, depending on which language it was written in.
An analysis of OpenAI's o200k_base tokenizer, the one shipping in GPT-4o, measured this directly across the 50,000 most frequent words in 12 languages. English needs 1.16 tokens per word on average. Arabic needs 1.97, a 70% premium, before the model has generated a single output token. Source: Kathane, "Not Speaking English to ChatGPT Costs You Millions of Tokens," Nov 2025.
The premium, by language
| Language | Tokens per word | Premium vs. English | Cost per 1M words @ $2.50/M tokens |
|---|---|---|---|
| English | 1.16 | — | $2.90 |
| Chinese | 1.32 | +14% | $3.30 |
| French | 1.52 | +31% | $3.80 |
| German | 1.52 | +31% | $3.80 |
| Spanish | 1.56 | +34% | $3.90 |
| Indonesian | 1.84 | +58% | $4.60 |
| Hindi | 1.89 | +63% | $4.73 |
| Russian | 1.96 | +69% | $4.90 |
| Arabic | 1.97 | +70% | $4.93 |
Source: Kathane, "Not Speaking English to ChatGPT Costs You Millions of Tokens," Nov 2025.
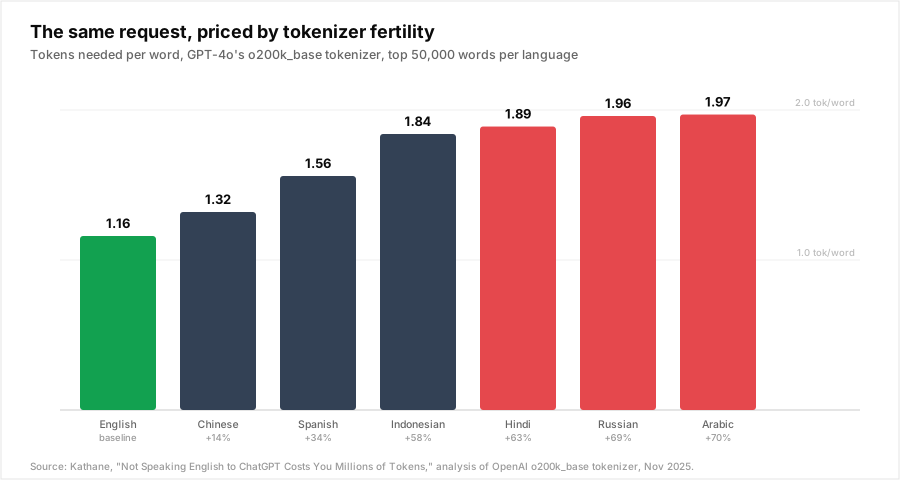
Run that per-word rate at the volume a real product sees and it stops looking like rounding error. A company processing 100 million words a month pays about $290,000 a year in English tokens and about $473,000 a year for the same content in Hindi, a $183,000 annual surcharge for serving one market instead of another, with identical prompts and identical model quality. Scaled down, the same math is why the substack piece above lands on a clean, quotable framing: for every dollar an English speaker spends on the same request, a Hindi speaker's equivalent costs about $1.63.
It used to be CJK. Now it's Indic, Cyrillic, and Arabic scripts
The popular version of this story is a few years stale. Chinese, Japanese, and Korean used to carry the worst penalty of all, running close to one token per character on older byte-pair tokenizers, roughly 4x worse than English on the same text. Bigger vocabularies fixed most of that: OpenAI's 200k-token o200k_base and Gemini's 256k-token SentencePiece vocabulary both allocate enough dedicated tokens to CJK scripts that Chinese now sits at a 14% premium, closer to French than to Arabic.
That fix does not generalize. Hindi, Arabic, Russian, and Indonesian remain 58-70% more expensive per word on the newest tokenizers, because the problem for those languages isn't script coverage, it's morphology. A vocabulary can learn "the" as one token because English inflects almost nothing. It cannot as easily learn every case-marked, prefixed, or agglutinated form a Hindi or Arabic word can take, so those words keep fragmenting into two, three, or four pieces regardless of how large the vocabulary gets. A November 2024 evaluation across the 22 official Indian languages confirms the tokenizers are improving, GPT-4 scored zero best-fertility placements across those languages; GPT-4o scored 5, a real jump, but the paper's own framing is that the improvement narrows a gap, it does not close it. Source: Tamang & Bora, "Evaluating Tokenizer Performance of Large Language Models Across Official Indian Languages," Nov 2024.
The historical trend line backs that up. Hindi tokenization on OpenAI's own tokenizers ran at roughly 6.55 tokens per word in 2021 and sits at 1.89 today, a 71% reduction over three years. Source: Kathane, "Not Speaking English to ChatGPT Costs You Millions of Tokens," Nov 2025. That's real progress, and it means this post will read differently in another three years. It is also still a 63% premium today, which is the number that hits this quarter's invoice.
The tax shrinks your context window too
A token budget is a token budget whether it's priced per request or fixed as a context window. The same fertility gap that inflates the bill also eats the window. A 128,000-token context holds roughly 110,000 words of English. The same window holds only about 68,000 words of Hindi, 38% less usable context for an identical price and an identical window size. Source: Kathane, "Not Speaking English to ChatGPT Costs You Millions of Tokens," Nov 2025.
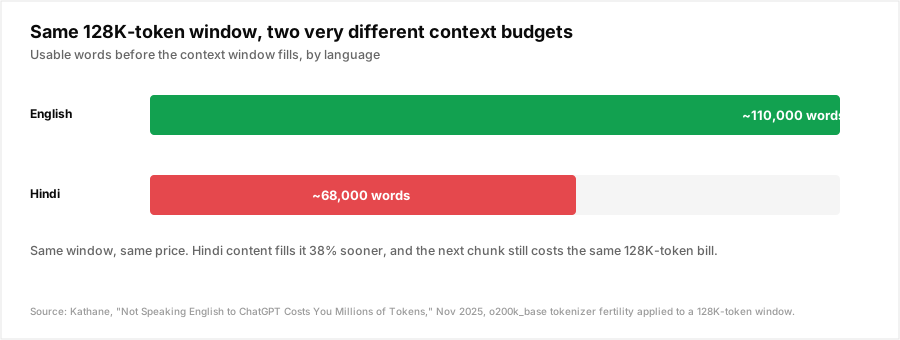
Every RAG pipeline, agent scaffold, or long-document workflow built and load-tested in English inherits an assumption about how much content fits, and that assumption is wrong by more than a third the moment the content is Hindi, Arabic, or Russian. A retrieval system tuned to pull "8 chunks" of context was tuned against English chunk sizes; the same 8 chunks in a high-fertility language can blow the same window that comfortably held them in English, exactly the failure mode covered in why over-retrieval quietly taxes your RAG bill, now compounded by language.
The quality gap doesn't go the other way either
The tax would sting less if the extra tokens at least bought better answers. They don't. MMLU-ProX, a 2025 reasoning benchmark spanning 13 typologically diverse languages, evaluated 36 frontier and mid-size models and found accuracy dropping sharply from high-resource to low-resource languages, models clearing roughly 70%+ on English versions of a reasoning question landing closer to 40% on the Swahili version of the identical question. Source: Xuan et al., "MMLU-ProX: A Multilingual Benchmark for Advanced Large Language Model Evaluation," arXiv:2503.10497, 2025. Paying 60-70% more tokens for a worse answer is the actual shape of the problem: the tax and the quality gap track the same axis, how much of a language's data the model actually trained on, and they compound rather than cancel.
The part that changes how you route: "cheapest" is not one ranking
Here's the mechanic most cost dashboards miss entirely. A router's cost ranking, which model is cheapest for a given quality bar, is built by measuring English tokens. That ranking is not portable to other languages, because tokenizer fertility does not move in lockstep across models. The same November 2024 study that measured the Indian-language gap also measured which tokenizer was most efficient per language, and no single model won:
| Tokenizer | Best-fertility placements (of 22 Indian languages) |
|---|---|
| SUTRA | 14 |
| MBZUAI Nanda | 6 |
| GPT-4o | 5 |
| Project Indus | 4 |
| OpenHathi / MahaMarathi | 2 each |
| Indic Gemma / Microsoft Phi / Airavata | 1 each |
SUTRA wins on fertility in 14 of 22 languages and would lose badly on an English-only cost comparison against a frontier model. GPT-4o wins on exactly 5. A router that picks "the cheapest model" once, globally, and applies that pick to every request regardless of language is optimizing for a ranking that only holds for the slice of traffic written in English, the same blind spot covered from the caching side in why a router that ignores prompt-cache state fights its own cost model: the router is confident, and confidently wrong, because it's missing one input.
What a language-aware router actually needs to check
- Detect language before pricing the request, not after. The cost comparison between two candidate models has to run per detected language, not once against a cached English benchmark.
- Keep the boilerplate in English. System prompts, tool schemas, and few-shot examples don't have to match the user's language, and English boilerplate doesn't pay the tax, only the user's own content does. That structural overhead is already the biggest line item in most agent budgets; don't let it also become a multilingual one.
- Compress harder on high-fertility turns. A given percentage of words trimmed by prompt compression removes more tokens in a language sitting at 1.9+ tokens per word than in one sitting at 1.16, so the same compression pass is worth more on exactly the traffic that needs it most.
- Measure cost per language, not blended. A blended $/1K-requests number that mixes English and Hindi traffic hides a 60-70% markup on one segment inside an average that looks fine.
- Re-run the model comparison per market before you standardize on one model. The evaluation cited above shows the fertility ranking flips by language; a model chosen for its English efficiency can be a below-average pick for your actual Hindi, Bengali, or Tamil traffic.
Nadir's /v1/recommend takes an optional detected_language hint the same way it takes cache_state: the cost side of the recommendation is priced against that language's own tokenizer fertility instead of an English-token assumption, so a model that looks cheaper in aggregate doesn't get picked for a language where it's actually the expensive option.
curl https://api.getnadir.com/v1/recommend \
  -H "X-API-Key: $NADIR_API_KEY" \
  -d '{
    "prompt": "इस बग को ठीक करने में मदद करें",
    "detected_language": "hi"
  }'
Same quality bar, same cascade, priced against the tokenizer your actual traffic runs on rather than the one your benchmark happened to be written in. If your product serves more than one language, that's the fix worth checking before anything else on this list: start free, or read the complete guide to cutting LLM API costs for the rest of the levers that stack on top of this one.