Abstract.
Aider, the open-source AI pair-programming tool, ships four different ways for a model to hand back a code edit: whole (return the entire file), diff (search/replace blocks for just the changed lines), diff-fenced (the same thing with the file path moved inside the fence, added specifically because Gemini models kept breaking the plain version), and udiff (a modified unified-diff format built for GPT-4 Turbo, because that model family kept getting "lazy" and skipping code it was supposed to keep). Source: Aider, "Edit formats". The diff-style formats are dramatically cheaper: the model only has to emit the lines that changed, not the file around them. Aider's own documentation is direct about why every model doesn't just use the cheap one: "for less capable models, or models with strange code-editing behaviors, aider defaults to using the whole editing format." A model too unreliable to be trusted with diff doesn't retry more often on the cheap format — it never gets offered the cheap format at all. It pays the whole-format token bill on every single edit, for the rest of the session. That eligibility cliff, not the occasional bad guess, is the number this post is about.
All token counts and cost figures in this post are an illustrative worked example built to show the mechanism, not a benchmark measurement or a proprietary trace. Format descriptions, the whole-format default for less capable models, and the architect/editor split are sourced directly from Aider's own documentation, linked throughout.
Four formats for the same five-line fix.
Say a coding agent needs to change five lines inside a 400-line file. Here is what each format actually asks the model to produce:
- whole — the complete, updated 400-line file, every unchanged line included, because the format has no way to say "leave this part alone." At roughly 8 tokens per line, that is close to 3,200 output tokens to move five lines.
- diff — a search/replace block: the handful of old lines, the handful of new lines, nothing else. Roughly 150 tokens for the same fix.
- diff-fenced — functionally the same as
diff, with the file path moved inside the code fence instead of above it, because Gemini models kept failing to close the fence correctly with the plain version. Comparable cost, ~160 tokens. - udiff — the standard unified-diff format (
@@hunks,-/+lines), simplified for LLM output. Built for the GPT-4 Turbo family specifically because that family tended to quietly drop code it was supposed to leave untouched — a different failure mode than fence-breaking, fixed with a different format. Roughly 190 tokens.
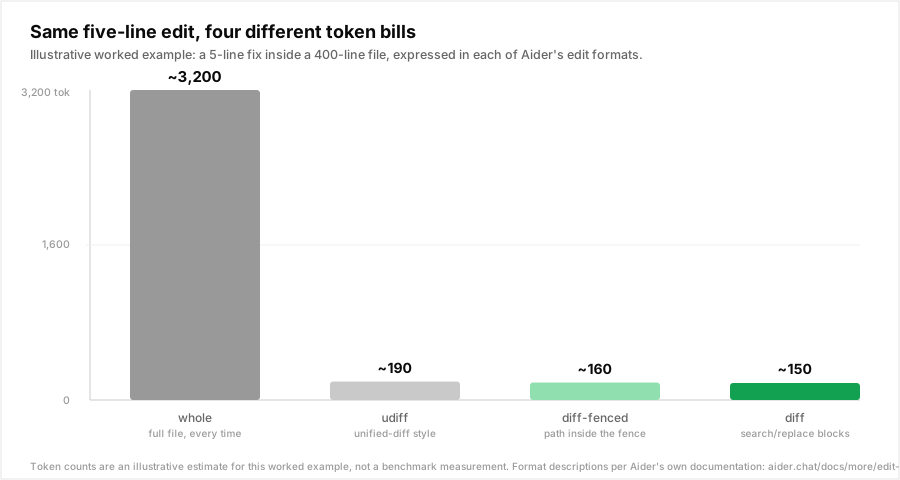
Roughly a 20x gap between the cheapest and most expensive way to say the same thing to the same model. That gap is exactly the kind of number a cost-optimization checklist tells you to go collect. The part the checklist usually skips: collecting it requires a model that can be trusted to produce a syntactically exact patch, and not every model can.
The cheap format needs an expensive kind of trust.
A diff block only works if the search half matches the file byte-for-byte. Miss a line, get the whitespace wrong, paraphrase a comment instead of copying it verbatim, and the patch does not apply. whole has no such failure mode — there is nothing to match, the model just overwrites the file with what it returned. That is precisely why Aider's docs describe whole as the fallback for "less capable models, or models with strange code-editing behaviors": it is the format that cannot be gotten wrong, at the cost of being the format that is never cheap.
This is a second, separate axis from the one most routing advice already covers. Model-tier routing asks "is this model smart enough to solve the task." Format eligibility asks a narrower, more mechanical question: "can this model's raw output be trusted to apply, verbatim, without a human or a verifier catching the mismatch." A model can clear the first bar and miss the second — plenty of small, fast models reason well enough to propose the right five-line fix and still botch the exact-match formatting required to express it as a diff. Route only on capability and you will hand a fast, cheap model a diff job it cannot format, then pay for the failure anyway.
What a missed patch actually costs.
Aider's benchmark harness gives every attempt a second try: if the model's edit does not apply, or the resulting code fails its hidden tests, aider feeds the error back and asks for a corrected version before scoring the attempt as failed. Source: Aider, "Benchmark notes". That second attempt is a second full round trip — the original context plus the failure message, generated again — and it is the mechanism most homegrown coding-agent harnesses reach for by default because it is the simplest thing that could work.
It is also the smaller of the two costs on the table. Model B below occasionally fails to apply on the first try and pays for a reflection round; Model C is unreliable enough with diff that it is not attempting diff at all, and pays the full whole-format token count on one hundred percent of its edits, not just the ones that would have failed.
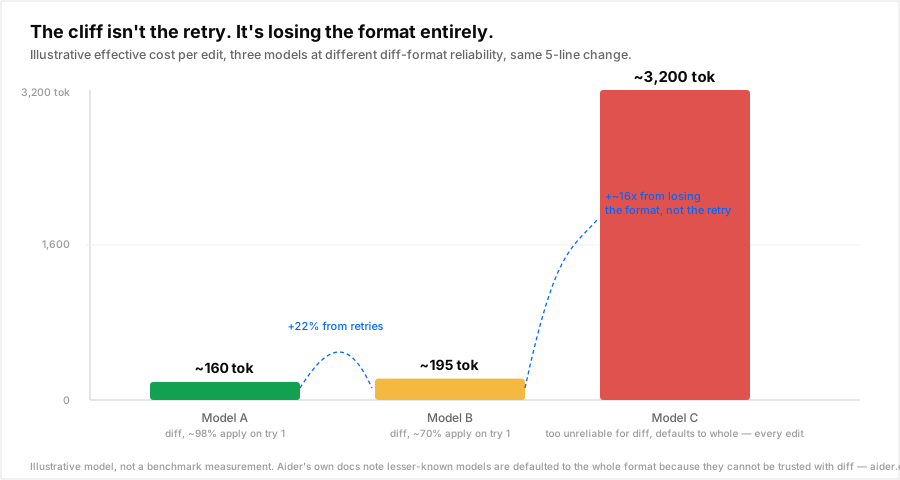
Going from Model A to Model B costs about 22% more per edit — a real number, worth measuring, not worth panicking over. Going from Model B to Model C costs roughly 16x more per edit, and that gap has nothing to do with how often the model gets the answer right. It is a formatting eligibility problem wearing a reasoning-quality costume. Judge these three models by accuracy alone and Model C might not even look like the worst one; judge them by what a coding agent actually bills per edit, and the format it is allowed to use is doing most of the work.
Aider already routes this. Most agent harnesses don't.
In September 2024, Aider shipped exactly the fix this implies, months before "routing" was a term most teams applied to their own coding agents: the architect/editor split. Source: Aider, "Separating code reasoning and editing," September 26, 2024. An architect model reasons about the problem and describes the fix however comes naturally to it, in prose, with no formatting constraints. A second, editor model takes that description and turns it into a syntactically exact set of edits — and, per Aider's own docs, "the architect and editor can use two different models." The reasoning step and the formatting step are decoupled on purpose, because they are different skills with different failure modes, and pinning both to one model means one of the two jobs is always being done by a model that wasn't picked for it.
That is a routing cascade wearing a code-editing name tag. This blog has already argued that a verified escalation, not a blind retry, is what makes a cascade worth its cost; Aider's own two-attempt benchmark loop is a verifier by construction — the check is "did the patch apply, did the tests pass" — it just is not wired to escalate to a different, more format-reliable model when the check fails, only to re-ask the same one. Most agent frameworks built after Aider skipped the format-eligibility half of this lesson entirely: they inherited the idea of retrying on a bad tool call, and dropped the idea of treating "can this model be trusted to produce an exact patch" as its own measured, per-model, per-format signal.
What to check this week.
- Measure apply-rate per model per format, separately from accuracy. Pull your agent's edit logs and check how often each model's raw
diffoutput applied cleanly on the first try. This is a different number from "did it solve the task," and most teams have never looked at it on its own. - Don't hand-pick the format once and forget it. A model that was reliable at
diffon last quarter's prompt template can regress after a prompt change, a model upgrade, or a longer context window — the same drift this blog has covered in router confidence calibration applies to format compliance too. - Verify before you bill the escalation as saved. A failed patch apply is a free, cheap, local signal — no extra model call needed — that the current model/format pair isn't working for this request. Escalate on that signal, not after a human notices broken code in review.
- Split the reasoning step from the formatting step for anything below your top-tier model. Aider's architect/editor pattern generalizes past Aider: let a stronger model describe the fix in prose, and route only the mechanical "turn this into an exact patch" step to whichever model is cheapest and still clears your measured apply-rate bar.
A minimal version: try the cheap model's diff, verify it actually applies before trusting it, escalate only on a real failure.
import subprocess
import tempfile
import openai

client = openai.OpenAI(
    base_url="https://api.getnadir.com/v1",
    api_key="ndr_...",
)

def propose_edit(prompt, model):
    response = client.chat.completions.create(
        model=model,
        messages=[{"role": "user", "content": prompt}],
    )
    return response.choices[0].message.content

def patch_applies(diff_text, repo_path):
    with tempfile.NamedTemporaryFile(mode="w", suffix=".diff") as f:
        f.write(diff_text)
        f.flush()
        result = subprocess.run(
            ["git", "apply", "--check", f.name],
            cwd=repo_path,
            capture_output=True,
        )
        return result.returncode == 0

def edit_with_verified_escalation(prompt, repo_path):
    # Cheap and fast first — "auto" lets Nadir route to whichever model
    # clears the accuracy bar for this prompt at the lowest cost.
    diff = propose_edit(prompt, model="auto")
    if patch_applies(diff, repo_path):
        return diff, "auto", 1

    # The check failed locally, no second model call spent finding that out.
    # Escalate to a model picked for format reliability, not just capability.
    diff = propose_edit(prompt, model="claude-opus-4-8")
    return diff, "claude-opus-4-8", 2
Same call shape as talking to any OpenAI-compatible endpoint. The git apply --check call is free — it costs no tokens and no extra request — so the escalation only fires when the cheap attempt actually failed, not on a fixed retry schedule. Nadir reports the routing decision and the model actually used per request, so which of the two branches above fired, and how often, becomes a number on your dashboard instead of a guess.
Related reading
- A calibrated verifier is what makes escalation worth its cost, not just its ceiling.
- A blind retry loop has its own break-even math — this post's format-eligibility cliff is the same shape at a different layer.
- Where the rest of a coding agent's tokens go before it ever proposes an edit.
- Multi-agent orchestration already runs at roughly 15x the token cost of a single chat turn — splitting reasoning from formatting is one more agent in that graph, worth costing out the same way.
- Router confidence drifts over time the same way format compliance does — both need to be measured, not set once.
Sources: [Aider, "Edit formats"](https://aider.chat/docs/more/edit-formats.html). [Aider, "Separating code reasoning and editing," September 26, 2024](https://aider.chat/2024/09/26/architect.html). [Aider, "Benchmark notes"](https://aider.chat/docs/leaderboards/notes.html). [Aider, "Code editing leaderboard"](https://aider.chat/docs/leaderboards/edit.html).