The original per-word bill
Telegrams were billed by the word, punctuation included, so people invented a way around it. Periods and commas cost as much as any other word, but ambiguity in a military dispatch could cost a lot more, so the custom that stuck was to spell out "STOP" between sentences instead of sending a punctuation mark. The habit served two purposes at once: it was one flat word regardless of length, and it removed exactly the kind of ambiguity a dropped or misheard period could cause. Cheaper and clearer, from the same constraint.
A May 2026 paper out of a small independent-researcher group, with one author at Palo Alto Networks, applies almost the same trick to LLM prompts. Telegraph English (Arbuzov, Bei, Dong, Kalaev, and Shvets, arXiv:2605.04426) doesn't delete tokens the way LLMLingua-2 does. It rewrites the prompt into a compact, symbol-rich dialect, one fact per line, with roughly 40 fixed logical and relational symbols standing in for the connective tissue of English prose. The paper's own example: sixty-eight tokens of "according to research by Johnson and colleagues (2023), the application of machine learning techniques to medical diagnostics resulted in a 27.5% increase in early detection rates while simultaneously reducing false positives by approximately 12%" becomes fourteen tokens:
ML→MEDICAL-DIAGNOSTICS: EARLY-DETECTION+27.5% ∧ FALSE-POSITIVE-12% [JOHNSON:2023]Same idea as STOP: don't drop the information, replace the verbose carrier with a fixed, unambiguous symbol.
What the paper actually measured
The authors ran 4,081 question-answer pairs sampled from LongBench-v2 (Bai et al.) through five OpenAI models, comparing Telegraph English against LLMLingua-2 at matched compression ratios. Two test suites: key_facts, headline claims with generic distractors, and the harder fine_facts, 801 pairs built adversarially around exactly the details compression tends to destroy — a percentage changed from 4.8% to 4.3%, a deadline in calendar versus business days.
| Suite | Model | Original | Telegraph English (~50%) | LLMLingua-2 (50% kept) |
|---|---|---|---|---|
| key_facts | GPT-4.1 | 100.0% | 99.1% | 99.0% |
| key_facts | GPT-4o-mini | 99.1% | 95.7% | 94.6% |
| key_facts | GPT-4.1-nano | 98.0% | 95.0% | 94.9% |
| fine_facts | GPT-4o | 99.6% | 96.5% | 93.3% |
| fine_facts | GPT-4o-mini | 93.8% | 84.3% | 82.0% |
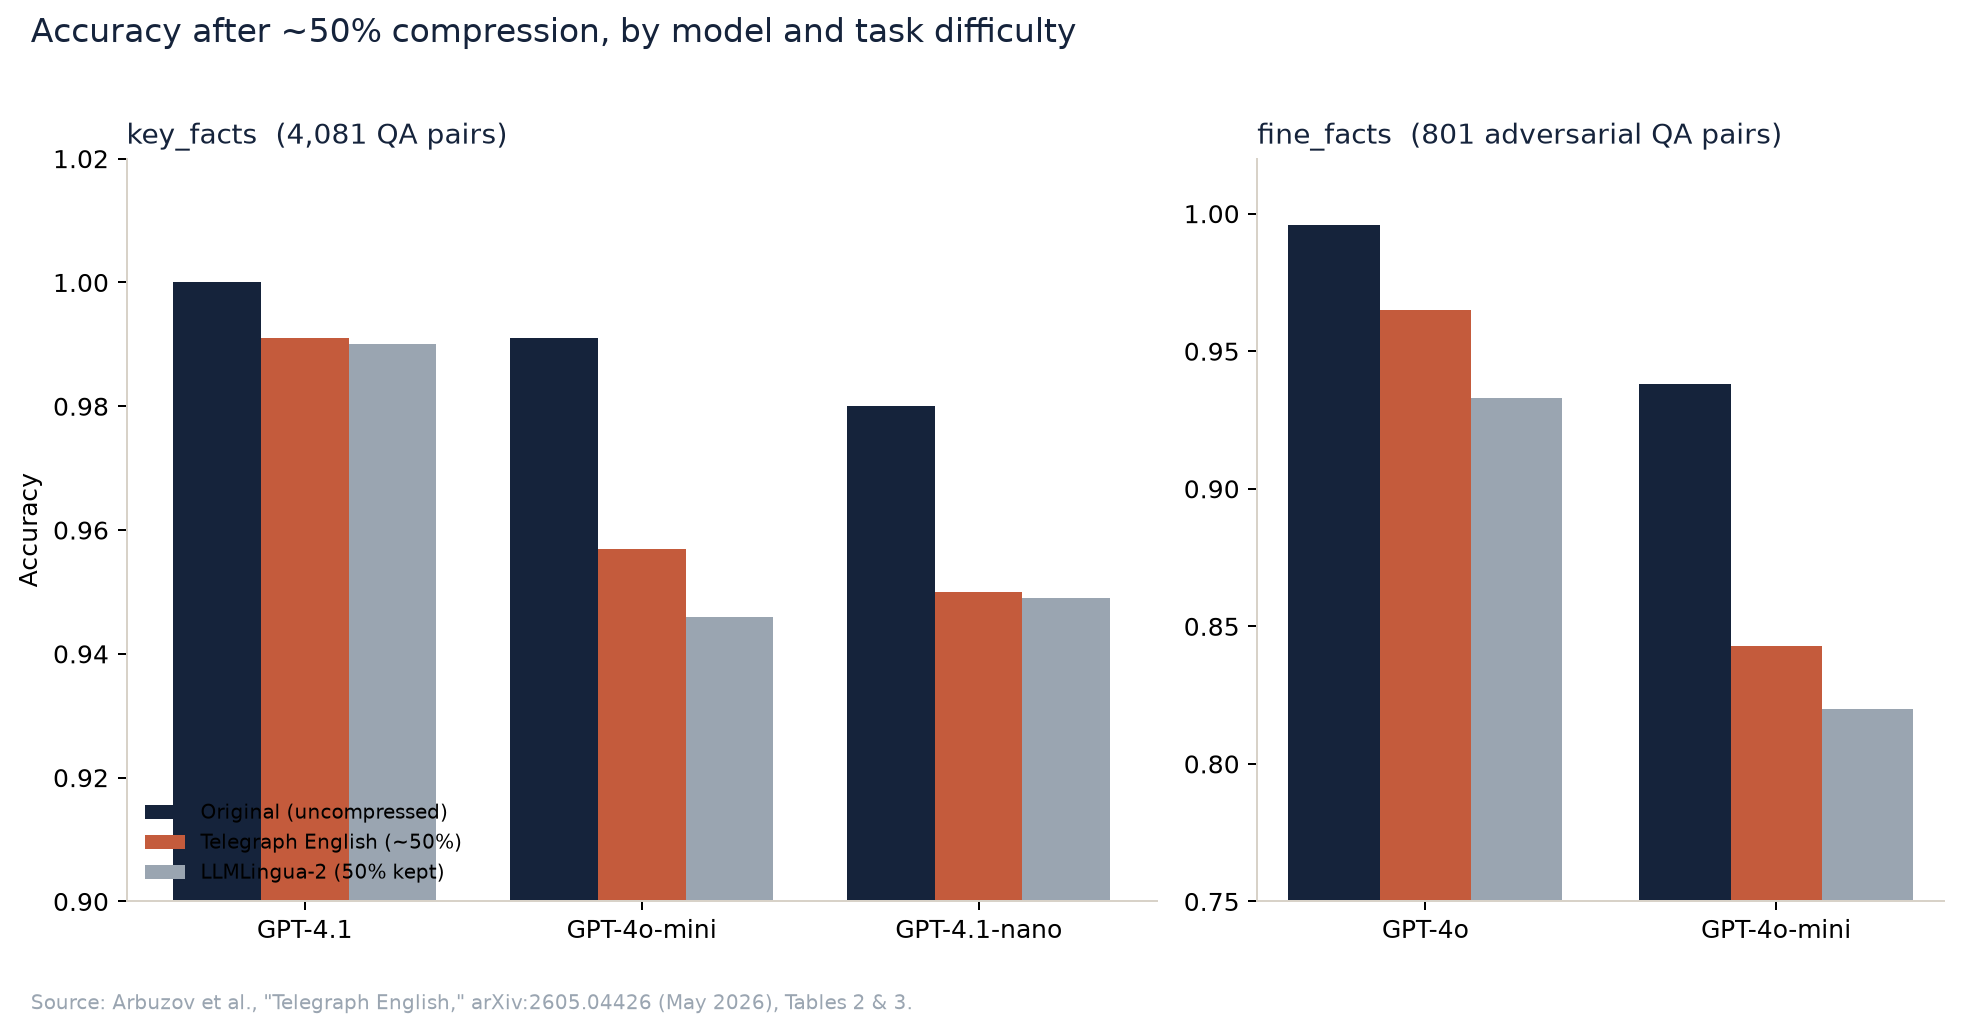
Three findings do the real work here. First, on the flagship model, both methods barely lose anything, GPT-4.1 drops under a point on either method at 50% compression, so if your pipeline is Opus- or GPT-4.1-class end to end, this paper mostly confirms compression is safe and moves on. Second, the ranking never flips: original beats Telegraph English beats LLMLingua-2 at 50% retention beats LLMLingua-2 at 33% retention, on every model, every task, every configuration tested. Third, and this is the one worth sitting with: the gap between the two compression methods widens as the model gets smaller and the question gets harder. At matched 50% retention, Telegraph English beats LLMLingua-2 by roughly a point on the biggest model and by 2 to 3 points on fine_facts for GPT-4o and GPT-4o-mini. Push LLMLingua-2 to a more aggressive 33% retention and the gap on GPT-4o-mini's fine-detail accuracy grows to roughly 11 percentage points, because LLMLingua-2 drops a full 21 points from baseline at that ratio while Telegraph English's structured symbols keep the numbers, units, and relationships explicit.
The authors' explanation is capacity, not chance: token deletion leaves gaps for the model to fill in by guessing at what used to connect the surviving fragments, and a smaller model guesses worse. Telegraph English does that reconstruction work upfront, at compression time, so the small model never has to attempt it. This blog has already measured how classification-based routers get less confident, not more, on out-of-distribution and edge-case inputs — the same shape shows up here one layer over: a cheap model asked to reconstruct meaning from degraded context is being asked to do the hard reasoning its cost tier was never meant to carry.
The compression method decides which model you can safely route to
That's the part that matters for anyone running a routing layer rather than a single fixed model. A compression method isn't just a lever on the bill, it's a constraint on how far down the model-cost ladder you can push a request and still get a right answer. Compress with a method that quietly costs a smaller model 3 to 11 points of accuracy on the details that matter, and a router calibrated on uncompressed traffic will route requests to a cheap tier that can no longer clear the bar it was calibrated against. The compression and the routing decision are not independent steps; the first changes the ground truth the second is measured against.
Telegraph English's structure has a second effect that compounds with routing, and it comes from a difference in what each method actually returns:
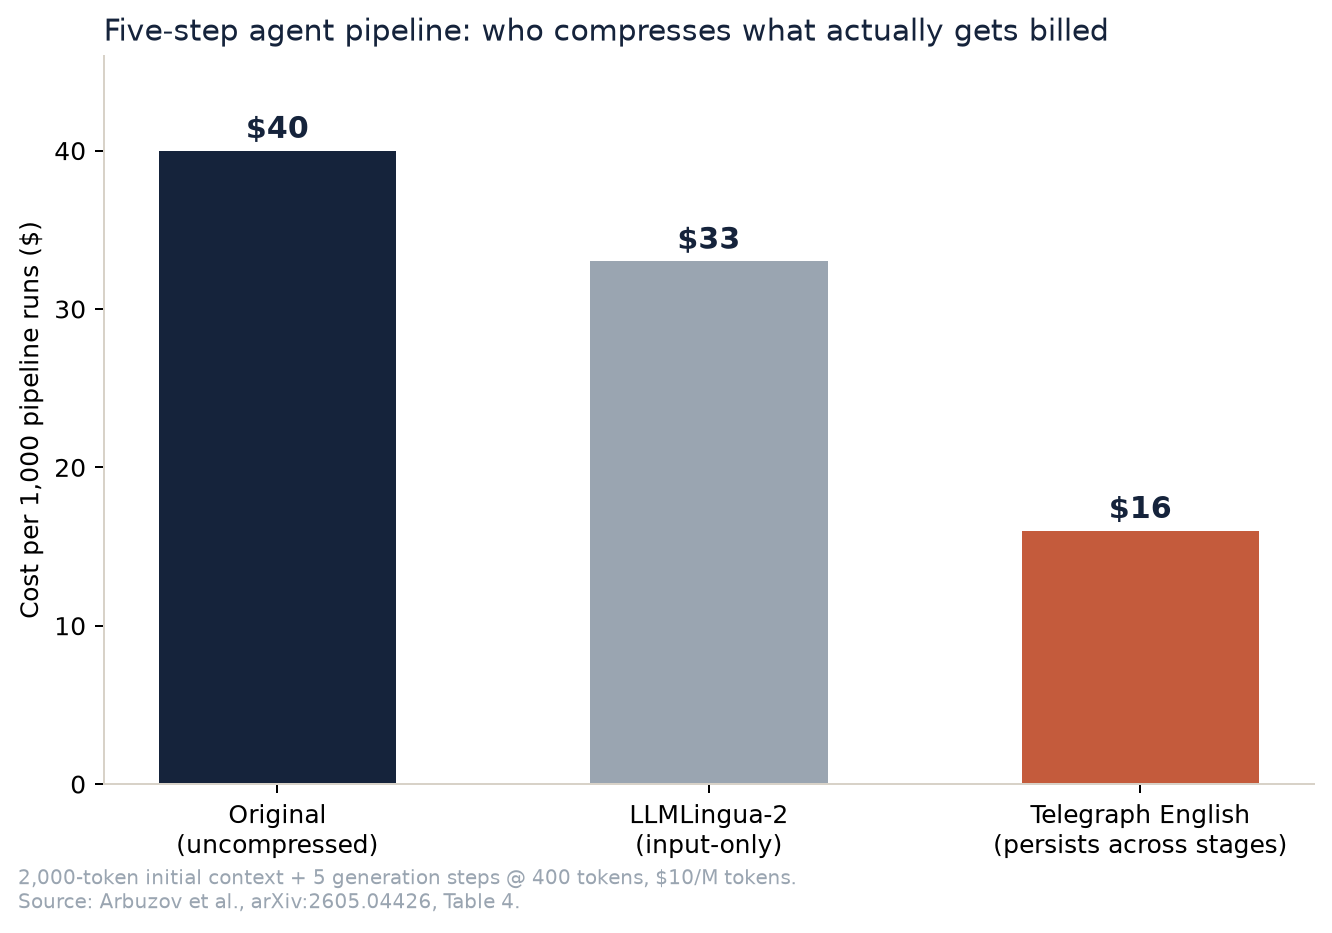
LLMLingua-2 is an input-only preprocessor: it shrinks the first prompt that goes in, but whatever the model generates at each step comes back in full, uncompressed natural language, and that's what the next step in an agent pipeline pays for. Telegraph English's output is a legitimate working format in its own right, one fact per line, so a multi-step pipeline can keep operating in it stage to stage instead of round-tripping through verbose prose each time. On the paper's own worked example — a five-step pipeline, 2,000 tokens of starting context plus five 400-token generations, at $10 per million tokens — that difference is $33 per 1,000 runs against $16. Compressing the first stage's input saves 18% of the bill. Compressing every stage saves 60%.
Why this is more than a compression trick
The line-structure rule that makes Telegraph English readable also makes it addressable. Every output line is exactly one claim, tagged with role and scope markers (CTX:, AGENT:, Q:/A:), which means the compressed text is simultaneously a semantic index: a query about adverse events can retrieve the one ADVERSE-EVENTS: line and its scope directly, no chunk-boundary heuristic, no risk of a fact getting split across two embeddings the way fixed-window RAG chunking can split it. This blog's context-selection benchmark already showed the model reads a fraction of what a pipeline retrieves; a format where retrieval granularity is a fact, not an arbitrary token window, is a more direct fix for that gap than fetching fewer, bigger chunks and hoping the boundaries land well.
The authors are careful to flag this piece as an architecture argument, not a benchmark result: nothing in their evaluation measures a multi-turn agent session updating facts in place over time, only static compress-once-read-once accuracy. Worth taking at face value rather than overselling. It also isn't free: Telegraph English needs an LLM call to do the rewrite (the paper used o4-mini), so it amortizes well on context that gets read many times and poorly on a prompt that's generated once and discarded.
What to check this week
- Stop assuming your compression ratio is your compression cost. A fixed-ratio deletion method (LLMLingua-2, and most "compress-to-X%" tools) applies the same cut to a dense paragraph and a verbose one; Telegraph English's ratio is an outcome of the input's density, not a knob, which is why the paper reports a mean of 0.585 with a full range from 0.13 (very compressible) to 1.57 (already dense enough that rewriting expands it). Measure whether your current compressor is over-cutting your densest documents.
- Test your compression method against your cheapest routed model, not your default one. If GPT-4.1 barely notices the difference between methods and GPT-4o-mini shows a multi-point gap on exactly the fine details your task needs, the accuracy number that matters is the one at the bottom of your routing ladder, not the one you validated against during a demo on the flagship model.
- Check whether your pipeline compresses once or compresses continuously. This blog has already made the case that compression and routing compound rather than compete; an input-only compressor captures that gain on step one of an agent loop and loses it back to full-price tokens on steps two through five.
- Look at your fine-detail failure mode specifically. Percentages, dates, and unit-bearing numbers are the tokens an importance classifier is most likely to flag as low-value in isolation and the tokens a downstream answer is most likely to depend on entirely. If your evals only score on headline correctness, you won't see this gap until a customer does.
A minimal version of the pattern — compress once with a structured rewrite, then route the compressed request to whichever model tier the compressed size and complexity actually justify:
import openai

client = openai.OpenAI(
    base_url="https://api.getnadir.com/v1",
    api_key="ndr_...",
)

TE_SYSTEM_PROMPT = """Rewrite the input as Telegraph English: one atomic
fact per line, using =, ->, =>, therefore, because, up/down arrows, and
AND/OR/NOT for logical relations. Never drop a number, unit, date, or
citation. Compress only where doing so loses no information."""

def compress_and_route(document: str, question: str) -> str:
    compressed = client.chat.completions.create(
        model="auto",
        messages=[
            {"role": "system", "content": TE_SYSTEM_PROMPT},
            {"role": "user", "content": document},
        ],
    ).choices[0].message.content

    return client.chat.completions.create(
        model="auto",
        messages=[
            {"role": "user", "content": f"{compressed}\n\nQ: {question}"},
        ],
    ).choices[0].message.content
The compression call and the answer call are both routed independently here, since Nadir picks the model per request rather than per pipeline, so a cheap model can do the rewrite while the answer call gets whatever tier the now-compressed, now-shorter request actually needs, and the routing decision on the second call is being made against a prompt that a smaller model has a real shot at reading correctly, not one a token-deletion pass quietly made harder for it.
Related reading
- LLMLingua ships a 3 to 5x input reduction in an afternoon; this is what it does and doesn't cover.
- Compression and routing are two separate levers on the same equation, and they compound.
- A July 2026 paper found deterministic linguistic rules can compress prompts with no model inference at deployment time — a different tradeoff than Telegraph English's per-document LLM rewrite.
- Routers get less confident exactly where compression damage concentrates: out-of-distribution and edge-case inputs.
- Most of what a RAG pipeline retrieves, the model never reads — the same waste this format's line-level addressing targets directly.
Sources: [Arbuzov, Bei, Dong, Kalaev, and Shvets, "Telegraph English: Semantic Prompt Compression via Structured Symbolic Rewriting," arXiv:2605.04426, May 2026](https://arxiv.org/abs/2605.04426). [Pan et al., "LLMLingua-2: Data Distillation for Efficient and Faithful Task-Agnostic Prompt Compression," Findings of ACL 2024](https://arxiv.org/abs/2403.12968). [Bai et al., "LongBench v2: Towards Deeper Understanding and Reasoning on Realistic Long-context Multitasks," arXiv:2412.15204](https://arxiv.org/abs/2412.15204). [UK National Archives, "Working with telegrams," on STOP as a punctuation-billing workaround](https://www.nationalarchives.gov.uk/education/students/working-with-telegrams/).