A one-line system prompt swap, no fine-tuning, no new infrastructure, no model change, cuts an LLM's reasoning tokens by up to 92% while matching or beating standard Chain-of-Thought accuracy. That is the headline result behind Chain of Draft (CoD), a February 2025 technique from Zoom Communications researchers: instead of "think step by step," tell the model to think step by step but keep each step to five words or fewer. Across GSM8K, sports understanding, and coin-flip reasoning, CoD matched or exceeded Chain-of-Thought's accuracy using as little as 7.6% of its tokens. Then, in a follow-up study, a researcher pointed the same technique at code. On all 300 samples of SWE-bench, the best CoD variant used 55.4% of Chain-of-Thought's tokens, a 44.6% cut, not a 92% one, while retaining "over 90%" of its code quality, not all of it. This post breaks down why the discount shrinks by roughly half on exactly the workload coding agents run all day, and ships a minimal version with the one guardrail the math papers didn't need.
The instruction that does the routing job in one line.
Chain-of-Thought prompting works by asking a model to reason out loud before answering, and it reliably improves accuracy on multi-step problems. It also reliably inflates the response: Claude 3.5 Sonnet answering a sports-understanding question under standard CoT wrote 189.4 tokens per response on average, most of it verbose narration around a one-word answer.
CoD's fix doesn't touch the model, the temperature, or the task. It changes one sentence in the system prompt: "Think step by step, but only keep a minimum draft for each thinking step, with 5 words at most." The model still reasons in discrete steps, it just writes each step as a terse fragment instead of a full sentence, closer to how a person scribbles "20 - x = 12" on scratch paper than how they'd explain the same step out loud.
| Task | Model | CoT: accuracy / tokens | CoD: accuracy / tokens | Token cut |
|---|---|---|---|---|
| GSM8K (math) | GPT-4o | 95.4% / 205.1 | 91.1% / 43.9 | 78.6% |
| GSM8K (math) | Claude 3.5 Sonnet | 95.8% / 190.0 | 91.4% / 39.8 | 79.1% |
| Sports understanding | GPT-4o | 95.9% / 28.7 | 98.3% / 15.0 | 47.7% |
| Sports understanding | Claude 3.5 Sonnet | 93.2% / 189.4 | 97.3% / 14.3 | 92.4% |
| Coin flip (symbolic) | GPT-4o | 100% / 52.4 | 100% / 16.8 | 67.9% |
| Coin flip (symbolic) | Claude 3.5 Sonnet | 100% / 135.3 | 100% / 18.9 | 86.0% |
The 7.6%-of-tokens headline is the best single case in that table, Claude 3.5 Sonnet on sports understanding, not a typical result. Averaged across all six model/task pairs above, CoD used roughly 25% of CoT's tokens and landed within 4.4 accuracy points of it on every task, above it on four of six. That's still a real, no-training discount available to anyone already running Chain-of-Thought prompts today. It's also a discount measured on math word problems, sports trivia, and coin flips, three domains with short, closed-form answers, which is exactly what the second paper went looking for a reason to doubt.
Then someone tried it on code.
A March 2025 study extended CoD to software engineering tasks and tested several variants against all 300 samples of the SWE-bench benchmark, real GitHub issues requiring a real code fix. The result: the most efficient variant, Baseline CoD, used 55.4% of Chain-of-Thought's tokens, translating to roughly a 45% cut in processing time and API cost. That's a genuinely useful discount. It is also less than half the reduction the original paper reported on math.
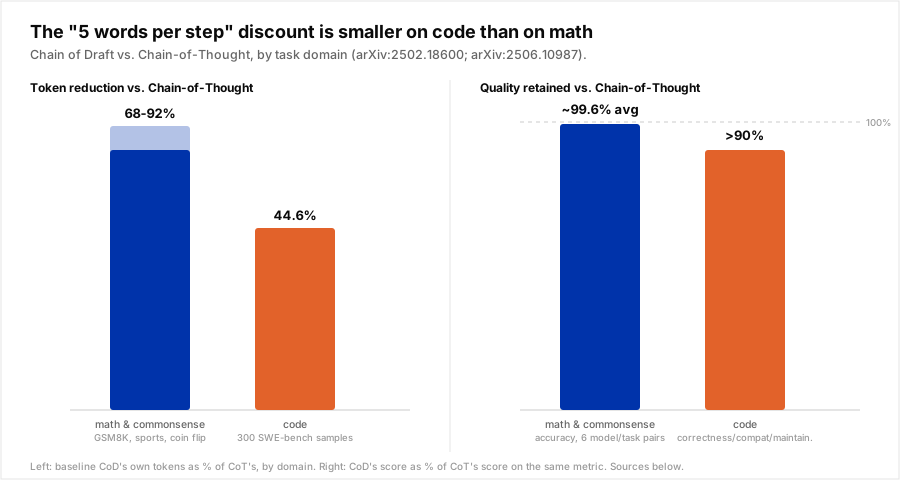
The paper's own explanation is the useful part, not just the gap: software tasks carry "inherent complexity and context-dependency" that a five-word draft step can't always compress without losing something a reviewer would catch. A GSM8K step is "20 - x = 12," fully specified by the arithmetic itself. A code-fix step might be "check null before dereference," a fragment that's fine as a note to self but can silently drop the which null, which call site, what the caller expects on failure, details that show up as a wrong diff rather than a wrong final number. The paper's multi-dimensional quality assessment measured that directly across correctness, compatibility, and maintainability, and CoD variants held "over 90%" of Chain-of-Thought's score on all three, not full parity, and not with a rounding-error gap the way the math tasks mostly showed.
This matters more for this audience than the math result does. Coding agents already burn roughly 1,000x the tokens of a chat exchange per task, and the reasoning trace inside each step of an agent loop is exactly the kind of Chain-of-Thought output CoD targets. A 45% cut on that trace, applied automatically across a fleet of agent sessions, is a real line-item change. A team that read only the original paper's 92% headline and shipped it against a coding agent unchecked would be routing on a number measured on a different kind of task entirely.
A minimal version to prototype.
The safest way to adopt CoD on a workload it wasn't validated on is to keep the escalation path the original math papers didn't need, because their tasks had a single verifiable final answer and code review doesn't happen at inference time:
COD_SYSTEM_PROMPT = (
    "Think step by step, but only keep a minimum draft for each "
    "thinking step, with 5 words at most. Return the answer after "
    "'####'."
)

def serve(task, cheap_model, strong_model, verifier, accept_threshold):
    draft = cheap_model.generate(task, system=COD_SYSTEM_PROMPT)
    score = verifier.score(task, draft)  # calibrated, not a raw judge call

    if score >= accept_threshold:
        return draft, "cod"

    # Terse draft didn't clear the bar: re-run with full reasoning,
    # not just a longer draft, since the failure mode here is a
    # compressed step hiding a wrong assumption, not a slow model.
    full = cheap_model.generate(task, system="Think step by step.")
    return full, "cot_fallback"
Two details carry the actual savings without carrying the risk. First, the verifier check runs on every response, not on a sample, the same reason continuous per-request verification beats a one-time canary: a terse draft that goes wrong does so per request, not as a slow drift a weekly audit would catch. Second, the fallback on a low score is full Chain-of-Thought on the same model, not automatically the most expensive model available. On a coding task specifically, the cheap fix is usually more reasoning tokens, not a bigger model; escalate the model tier only if the verifier keeps failing after that.
What this doesn't solve.
CoD is a prompting change, not a training run, and it inherits every risk of prompting changes: no formal guarantee, model-and-prompt-specific behavior, and a result that can shift on the next model version without warning. Both papers tested a narrow slice of tasks, closed-form reasoning benchmarks in the first case, SWE-bench specifically in the second, and neither is a stand-in for an arbitrary agent's actual tool-calling, multi-turn trajectory. Compressing input tokens has already backfired in a documented way: compressing output reasoning is a different mechanism, but the lesson generalizes, measure the actual token and quality delta on your own traffic before trusting a benchmark number from a different domain. And CoD isn't the only lever here: BudgetThinker (arXiv:2508.17196) gets budget-aware reasoning through supervised fine-tuning and RL instead of a prompt change, a heavier but potentially more reliable route to the same goal if a team has the budget to train.
What to check before adopting Chain of Draft.
- Benchmark it on your own task type, not the paper's. A 92% cut on math says nothing certain about a 45% cut on code, and neither says anything certain about a customer-support ticket or a legal summary. The linguistic-rules compression work this blog covered separately makes the same point about a different zero-cost lever: cheap tricks are task-specific, and the only way to know your number is to measure it.
- Keep a verifier or a fallback path, not a fixed word limit with no check. The SWE-bench study's "over 90%, not 100%" quality result is the whole argument for this: a five-word draft step occasionally drops something a reviewer would catch, and the fix is catching it before the diff ships, not tightening the word count further.
- Escalate to more reasoning before escalating to a bigger model. A terse-draft failure on a coding task is usually an under-specified step, not an under-powered model; the code sample above falls back to full Chain-of-Thought on the same model first.
- Don't confuse this with the reasoning-effort dial. Reasoning_effort, thinking budgets, and Anthropic's effort parameter control how much hidden, billed reasoning a model does internally before answering. CoD is a visible-output prompting instruction that works on any model, reasoning or not, and stacks with that dial rather than replacing it.
- **Nadir's verifier cascade already runs a calibrated check on every proxied response**, the same escalate-on-low-score mechanism the snippet above sketches by hand, so a terse-prompting strategy like CoD gets a safety net without a team building and maintaining its own verifier.
Conclusion.
Chain of Draft is one of the few genuinely free levers in this space: no fine-tuning, no new model, no infrastructure, just a different sentence in the system prompt. The number worth remembering isn't 92%, it's that the discount is domain-dependent and roughly half as large on the workload this audience actually runs, with a real, measured quality cost attached rather than none at all. Ship it with a verifier on the exact traffic it'll run against, not the benchmark it was announced with.
Sources: [Xu, Xie, Zhao, He, "Chain of Draft: Thinking Faster by Writing Less," Zoom Communications, arXiv:2502.18600, submitted February 25, 2025](https://arxiv.org/abs/2502.18600). [Yang, "Chain of Draft for Software Engineering: Challenges in Applying Concise Reasoning to Code Tasks," arXiv:2506.10987](https://arxiv.org/abs/2506.10987). [Wen et al., "BudgetThinker: Empowering Budget-aware LLM Reasoning with Control Tokens," arXiv:2508.17196](https://arxiv.org/abs/2508.17196). [Coding Agents Burn 1,000x More Tokens Than Chat](/blog/coding-agents-burn-1000x-tokens-research). [Shorter Prompt, Longer Bill](/blog/prompt-compression-output-token-expansion-backfire). [The Overthinking Tax](/blog/reasoning-effort-thinking-budget-cross-provider-tutorial).