Abstract.
On Microsoft's own fiscal 2026 earnings calls, CFO Amy Hood told investors the company has been short on data center capacity "for many quarters," adding, "I thought we were going to catch up. We are not." CEO Satya Nadella put the mechanism plainly: "You may actually have a bunch of chips sitting in inventory that I can't plug in. In fact, that is my problem today." Source: Data Center Dynamics, "Microsoft has AI GPUs 'sitting in inventory' because it lacks the power necessary to install them." The backlog behind that admission runs to roughly $80 billion in contracted Azure capacity Microsoft cannot yet deliver, disclosed alongside commercial remaining performance obligations that reached $627 billion. Source: Microsoft, FY2026 quarterly earnings calls. Not a chip shortage. A watt shortage, at the company that can outbid almost anyone on Earth for chips.
That changes what "cost optimization" means going forward. For three years, the entire genre, this blog included, has framed routing, compression, and caching as ways to shrink a dollar figure. Dollars were always a proxy for something physical: compute time, silicon, electricity. When GPU supply was the binding constraint, the proxy and the underlying resource moved together closely enough that nobody had to separate them. Now the binding constraint at the biggest buyer of AI compute on the planet is electrons, not chips, and a 2026 Microsoft Research paper puts a real number on what a token costs in the unit that's actually running out.
What a token costs in watt-hours, measured, not guessed.
Felipe Oviedo, Fiodar Kazhamiaka, Esha Choukse, and co-authors published "Energy Use of AI Inference, Efficiency Pathways, and Test-Time Scaling" in Joule in 2026, with the underlying methodology and simulation code released on GitHub. Source: Oviedo et al., *Joule* 2026 (arXiv:2509.20241). For frontier-scale models, over 200 billion parameters, running on H100 nodes, they measure a median of 0.31 Wh per query, interquartile range 0.16 to 0.60 Wh. Their own framing of that number is direct: "widely cited estimates are overstated by 4-20x."
Then they change one variable. Push the same model family into a test-time-scaling scenario, a reasoning trace roughly 15x longer than a typical query, and the median energy rises 13x, to 3.91 Wh, interquartile range 2.15 to 7.05 Wh.
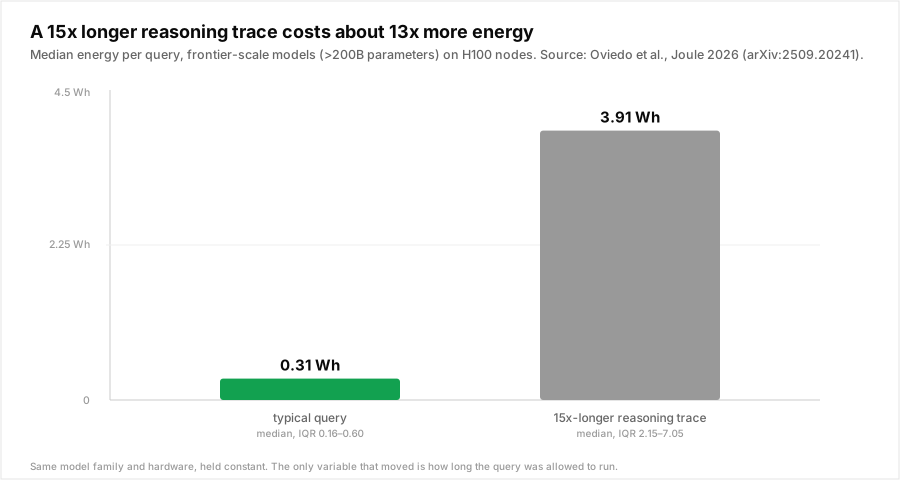
Read that pair of numbers as a policy question, not a curiosity. 13x more energy for 15x more length is close to proportional, not some runaway exponential, which means the physics here isn't exotic. What's expensive is ordinary: every additional token a model decodes burns roughly its share of the joules, whether that token was reasoning that changed the final answer or reasoning that restated the question a different way. A system that defaults hard-looking prompts into extended thinking mode is applying that near-linear multiplier to every request that trips the default, not just the ones where the extra length earned its keep.
The number everyone already believes turns out to be measuring the wrong query.
Before Oviedo's team published, the most-cited public estimate of what a single AI query costs in energy came from a 2023 paper: Alex de Vries, in Joule, estimated roughly 2.9 Wh, extrapolated in comparison to a Google search, and it became the basis of the "one ChatGPT query equals ten searches" framing that spread through mainstream coverage of AI's environmental footprint. Source: de Vries, "The growing energy footprint of artificial intelligence," *Joule* 7 (2023): 2191-2194.
Line that estimate up against Oviedo's 2026 measurements and something specific happens: 2.9 Wh doesn't land near the 0.31 Wh typical-query median at all. It lands almost exactly on the 3.91 Wh reasoning-mode median, the workload nobody was picturing when the number went viral.
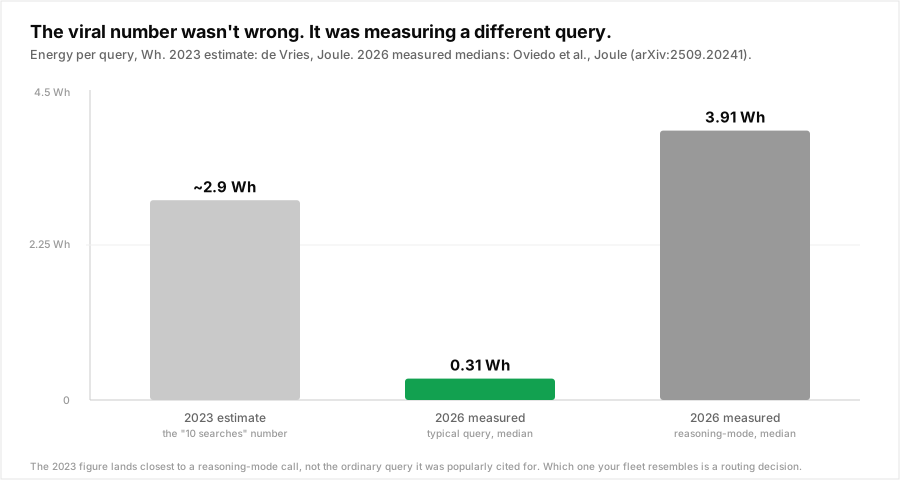
The old number wasn't fraudulent. It was measuring a call that, in 2023, wasn't the default and mostly is now. Extended reasoning, agentic tool loops, and multi-step verification, all covered on this blog as dollar-cost stories, have quietly moved a growing share of production traffic from the 0.31 Wh bucket into something closer to the 3.91 Wh one. Whether your fleet's real energy footprint looks like the reassuring small number or the scary big one was never fixed by the model you picked. It's set, request by request, by how long you let that model run.
Compression doesn't dodge this either.
The instinct once a resource gets scarce is to shrink the input and assume the output follows. It usually doesn't. A 2026 study of prompt compression across three providers and 28,421 API trials found that truncating a prompt to keep task-critical instructions intact is harder than it looks: at a 0.7 compression ratio, task success collapsed from a 26.0% baseline pass rate to 1.5%, and on the worst-behaved provider, output length ballooned in response. Source: "The Compression Paradox in LLM Inference: Provider-Dependent Energy Effects of Prompt Compression" (arXiv:2603.23528). This blog has already priced that same mechanism in dollars: a model that loses task-critical instructions to truncation doesn't fail quietly, it writes more, trying to recover context it no longer has. Output tokens are the expensive half of the ledger in dollars, at 5 to 8x the input rate on most cards, and they are the expensive half in watts for the identical reason: decoding a token costs meaningfully more than reading one, so a compression pass that inflates the output side loses on both units it was supposed to save.
The paper's own conclusion matches: "model selection and output-length control offer more reliable energy-quality tradeoffs than prompt compression techniques." Shrinking what you send is not the lever. Bounding what comes back, and choosing which model gets asked to produce it, is.
Routing was already solving this. It just didn't know it.
A separate 2026 paper makes the connection explicit. "Beyond Test-Time Compute Strategies: Advocating Energy-per-Token in LLM Inference" (arXiv:2603.20224) proposes exactly what its title says: track energy-per-token as a first-class metric next to accuracy, and route reasoning depth dynamically against an "operating curve" instead of a fixed thinking-budget setting applied to every request in a class. Source: arXiv:2603.20224.
That is architecturally the same shape as a verifier-gated cascade, which this blog has argued for on dollar grounds already: try the cheap, short path first; escalate to more tokens, or a bigger model, only when a calibrated check says the cheap attempt actually fell short. The reason it generalizes to energy without any new mechanism is that dollars and watt-hours are both, underneath, counting the same thing: how much computation ran to answer one specific prompt. A router that picks the smallest model and shortest reasoning depth that clears your accuracy bar is, by construction, picking close to the fewest joules too, because it never had two separate meters to satisfy. It had one decision, made per request, and both bills are downstream of it.
Self-hosting your own routing or reasoning layer doesn't sidestep this arithmetic either: the classifier and verifier models a DIY stack runs to make that decision are themselves drawing power on hardware you provisioned for the worst hour, all day, every day it's on. The energy question doesn't disappear when you build in-house. It just moves to a rack you're paying to keep spinning.
What to check this week.
- Measure what reasoning mode actually earns, not just what it costs. Pull a sample of requests that triggered extended thinking or a long tool-use loop and check how often the extra length changed the final answer versus how often a short pass would have cleared your accuracy bar anyway. That gap is pure multiplier, on both meters, for zero return.
- Stop treating a thinking budget as a fixed setting. A flat reasoning-effort tier applied to a whole request class pays the 13x jump on every request in that class, including the ones that never needed it. A calibrated escalation, cheap pass first, verify, extend only on a real miss, pays it only where it's earned.
- Don't compress your way around this. If the goal is a smaller footprint, bound the output and pick a leaner model for requests that qualify. Shrinking the prompt and hoping the answer follows is the one lever the research above says reliably backfires.
- If you're self-hosting, price your idle hours in joules, not just dollars. A classifier or verifier stack sized for peak load draws power around the clock; the same utilization math that inflates your self-hosted dollar cost inflates its energy footprint identically.
None of this requires new infrastructure to start measuring. The same OpenAI-compatible call already routes the decision; what changes is what you do with the model and token fields you're already logging.
import openai

client = openai.OpenAI(
    base_url="https://api.getnadir.com/v1",
    api_key="ndr_...",
)

response = client.chat.completions.create(
    model="auto",  # cheapest model, shortest reasoning depth, that clears the bar
    messages=[{"role": "user", "content": prompt}],
)

# Nadir doesn't meter your electricity bill. It does report which model
# answered and how many input/output tokens it took on every request, in
# the response body's nadir_metadata object. Multiply that against the
# published Wh-per-token figures above and you have a directional energy
# estimate for the same traffic your dollar dashboard already shows you.
usage = response.usage
model_used = response.model
The dollar number and the watt number were never two different problems. They're two units reading the same meter: how much computation this one request actually needed. A team that has already built the habit of asking that question for cost reasons has, without extra work, built the habit that also matters for the reason Microsoft's own earnings calls are now open about, that the electricity to run the alternative isn't guaranteed to be there.
Related reading
- Extended thinking tokens cost $25 per million at output rates, and most teams have never measured what reasoning mode adds to their bill.
- A flat reasoning-effort or thinking-budget setting pays the escalation cost on every request in its class, not just the ones that needed it.
- Shrinking the prompt and hoping the output follows is the same backfire in dollars that this post prices in watts.
- A calibrated verifier, not a blind escalation, is what makes a cascade worth its cost on either meter.
- Self-hosting the routing layer moves the energy question onto hardware you provision for the worst hour, not away from it.
Sources: [Data Center Dynamics, "Microsoft has AI GPUs 'sitting in inventory' because it lacks the power necessary to install them."](https://www.datacenterdynamics.com/en/news/microsoft-has-ai-gpus-sitting-in-inventory-because-it-lacks-the-power-necessary-to-install-them/) [Microsoft, FY2026 quarterly earnings calls.](https://www.microsoft.com/en-us/investor/events/fy-2026) [Oviedo, Kazhamiaka, Choukse, et al., "Energy Use of AI Inference, Efficiency Pathways, and Test-Time Scaling," Joule (2026), arXiv:2509.20241.](https://arxiv.org/abs/2509.20241) [de Vries, "The growing energy footprint of artificial intelligence," Joule 7 (2023): 2191-2194.](https://www.cell.com/joule/fulltext/S2542-4351%2823%2900365-3) ["The Compression Paradox in LLM Inference: Provider-Dependent Energy Effects of Prompt Compression," arXiv:2603.23528.](https://arxiv.org/pdf/2603.23528) ["Beyond Test-Time Compute Strategies: Advocating Energy-per-Token in LLM Inference," arXiv:2603.20224.](https://arxiv.org/pdf/2603.20224)