By April 2026, every frontier model that ships open weights, DeepSeek, Kimi, MiniMax, Qwen, Llama, is a Mixture-of-Experts model. The pitch is always the same sentence: a 671-billion-parameter model that only activates 37 billion per token costs like a 37-billion-parameter model. That sentence is true in exactly one place, an API bill from a provider running enormous batches on a compute-bound cluster, and false in the other place teams most often test it, a self-hosted box where the bottleneck was never compute to begin with. A June 2026 empirical study measured the gap directly, and it is large enough to flip a build-vs-buy decision.
The pitch: pay for the active slice, not the whole model.
Sparse activation is the entire architectural bet behind every one of these releases. A router picks a handful of experts per token out of dozens available, and the rest sit idle for that step. The headline numbers are real and public:
| Model | Total parameters | Active per token | Sparsity |
|---|---|---|---|
| OLMoE-1B-7B | 6.9B | 1.3B | 19% |
| Mixtral 8x7B | 47B | 13B | 28% |
| DeepSeek-V2 | 236B | 21B | 9% |
| DeepSeek-V3 | 671B | 37B | 5.5% |
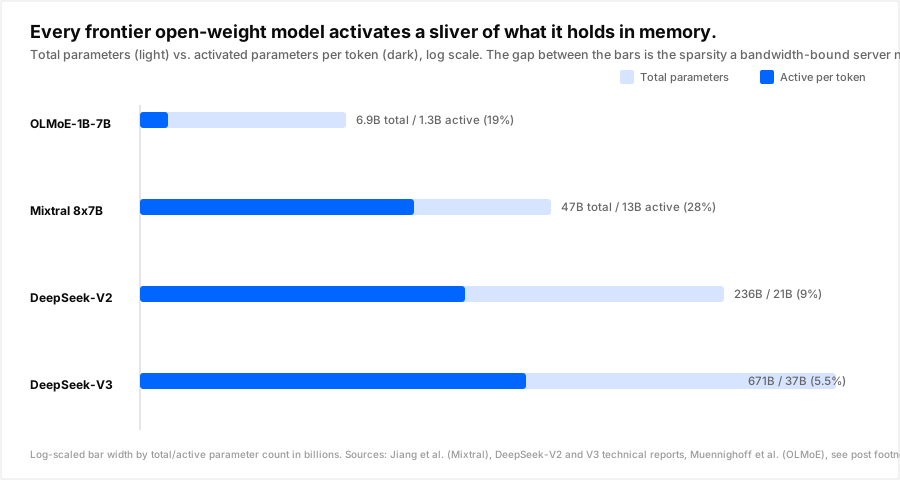
The framing that follows from this table, repeated in nearly every MoE launch post, is that inference cost tracks the dark bars, not the light ones. DeepSeek's V4 pricing already shows up in this blog's own routing math, and the open-weight price war post documents just how far list prices have fallen on the back of that architecture. None of that is wrong. It's also not the whole picture, and a June 2026 paper measured exactly where it stops being true.
Where the pitch survives: a provider's rack.
On a cloud provider's serving fleet, the assumption mostly holds. Large batch sizes keep GPUs compute-bound, request volume is high enough to keep every expert warm across the fleet, and the memory that has to hold all 671 billion parameters is amortized across thousands of concurrent requests. In that regime, FLOPs per token really do scale with the active fraction, and that's the arithmetic behind DeepSeek, Kimi K2, and MiniMax pricing their APIs at a fraction of a dense frontier model's rate. If you're calling these models through an API, the sparsity discount is largely real, and routing to whichever sparse model is cheapest at a given moment, without owning any of the serving infrastructure, is the whole value of a decision layer that treats "which model" as a per-request choice.
Where the pitch breaks: a box you own.
"Does Mixture-of-Experts Actually Help Inference on Consumer and Edge Hardware? An Empirical Study" tested OLMoE-1B-7B (1.3B active parameters out of 6.9B total) against a dense model with the same active-parameter count on two devices a team might actually self-host on: an Apple M2 Pro laptop and an NVIDIA Jetson Orin Nano edge box. Source: Alfarizy et al., arXiv:2606.21428, June-July 2026
The MoE model lost on both, despite doing less arithmetic per token:
- Apple M2 Pro: roughly 10% slower in tokens/sec than the same-active dense model.
- Jetson Orin Nano: roughly 31% slower, and burning 2.1x the energy per token.
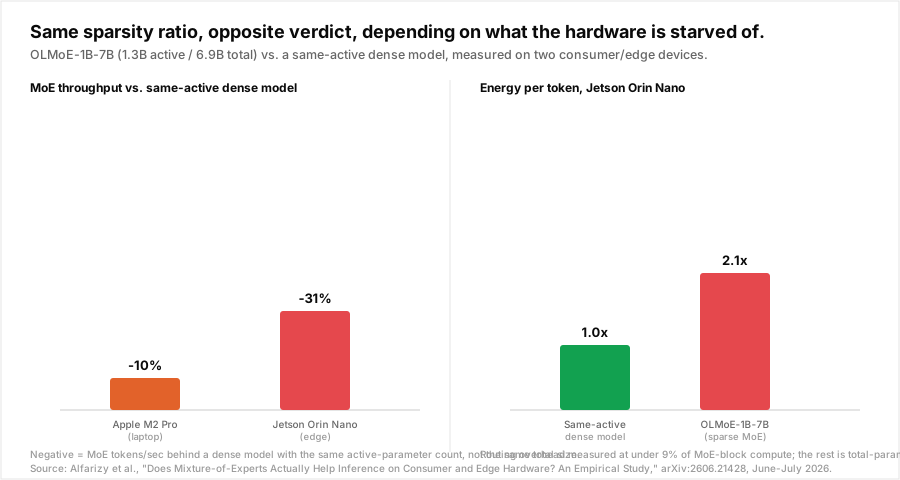
The paper's authors profiled where the time actually went, and it wasn't the routing step: dispatching tokens to the right experts accounted for under 9% of MoE-block compute. The rest came from total-parameter memory footprint, expert dispatch overhead, and KV-cache pressure, exactly the three things a bandwidth-bound device is already starved of. Their conclusion is the sentence worth pinning above any self-hosting decision: on this class of hardware, inference cost tracks total parameters, not active ones, and sparse activation does not buy back what the device is actually constrained on.
The check that would have caught this before benchmarking.
The gap isn't subtle once you separate the two things a model actually costs: compute, which scales with active parameters, and memory, which has to hold every expert the router might pick, so it scales with total parameters regardless of how few get used on any given token.
BYTES_PER_PARAM = {"fp16": 2, "fp8": 1, "int4": 0.5}

def moe_footprint(total_params_b, active_params_b, precision="fp8"):
    """Back-of-envelope split: memory to hold every expert resident,
    vs. the compute share a dense model of the active size would use."""
    memory_gb = total_params_b * BYTES_PER_PARAM[precision]
    compute_share = active_params_b / total_params_b
    return {
        "memory_to_hold_all_experts_gb": round(memory_gb, 1),
        "compute_share_of_dense_equivalent": round(compute_share, 3),
    }

print(moe_footprint(671, 37, "fp8"))
# {'memory_to_hold_all_experts_gb': 671.0, 'compute_share_of_dense_equivalent': 0.055}
DeepSeek-V3 at FP8 needs roughly 671 GB just to keep every expert resident, before a single KV cache entry, which is most of a ten-GPU H100 node, purely for weights that a given token will use 5.5% of. The compute bill really is close to a 37B-parameter model's. The memory bill is not, and on hardware where memory bandwidth is the ceiling, not compute, the memory bill is the one that decides your latency and your power draw. This is illustrative arithmetic, not a vendor-specific benchmark, but the shape holds at every scale in the table above.
The decision this actually is.
This blog has already made the general case that the real monthly bill for self-hosting rarely matches the sticker price, and that idle GPU capacity is its own tax independent of which model sits on the box. MoE adds a specific, measurable version of that same trap: a model architecture can look like a compute discount and turn into a memory-bandwidth bill the moment your box isn't running the provider-scale batch sizes that make the discount real. KV-cache quantization shaves some of that memory pressure back down, but it doesn't change which resource a sparse model is actually contending for on constrained hardware.
The practical split:
- High, sustained batch on data-center GPUs, compute-bound: the sparsity discount is close to real. This is the regime every MoE API price is built on.
- Low batch, a laptop, an edge box, or a single under-utilized GPU, bandwidth-bound: total parameters set your floor, and a same-active dense model can beat the MoE model outright, the way OLMoE lost to a same-active dense model on both devices tested.
What to check before you trust a "sparse = cheap" pitch.
- Ask which resource your box is actually bound on. If GPU utilization sits comfortably under compute saturation while memory bandwidth is maxed, you are in the regime where MoE's discount does not show up.
- Size memory for total parameters, not active ones. The 671 GB DeepSeek-V3 needs to stay resident does not shrink because only 37B activate per token.
- Don't assume routing overhead is the risk. The edge study measured it at under 9% of MoE-block compute; if a self-hosted MoE deployment is underperforming, dispatch and KV-cache pressure are the more likely causes, not the router itself.
- Re-run the comparison against a same-active dense model, not a same-total one. "MoE vs. a 671B dense model" is a comparison nobody would self-host either side of. The one that matters is against a dense model sized to the parameters you're actually paying compute for.
- If you're buying through an API instead of hosting, the batch-size and utilization problem is the provider's to solve, not yours, and the sparsity discount in DeepSeek, Kimi K2, and MiniMax pricing is the one you can actually collect without owning a GPU cluster.
Conclusion.
Sparse activation is a real architectural win, and the pricing on every major open-weight release in 2026 is proof it survives at data-center scale. What it doesn't do is travel automatically to a box a team owns and controls the batch size of. A June 2026 empirical study measured the failure mode directly: an MoE model with a fifth of a dense model's total footprint but the same active parameters lost by 10% on a laptop and by 31%, at more than double the energy, on an edge device, with routing itself cleared as the cause. The number that predicts inference cost changes depending on whether you're renting compute or hosting memory, and most teams only check the first one.
Sources: [Alfarizy, Nguyen, Richard, Razavi-Far, and Cao, "Does Mixture-of-Experts Actually Help Inference on Consumer and Edge Hardware? An Empirical Study," arXiv:2606.21428, June-July 2026](https://arxiv.org/abs/2606.21428). Jiang et al., "Mixtral of Experts," arXiv:2401.04088. DeepSeek-AI, "DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model," arXiv:2405.04434. DeepSeek-AI, "DeepSeek-V3 Technical Report," arXiv:2412.19437. Muennighoff et al., "OLMoE: Open Mixture-of-Experts Language Models," arXiv:2409.02060. [The real monthly bill: self-host vs. managed vs. frontier](/blog/real-monthly-bill-self-host-vs-managed-vs-frontier). [The Utilization Tax](/blog/utilization-tax-self-hosted-llm-cost). [The $1.16 Floor](/blog/open-weight-price-war-inference-floor-2026).